---
title: Qwen3.8-27B-CuteHuman-LoRA
canonical_url: "https://www.modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA"
md_url: "https://www.modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA.md"
repository: wesjos/Qwen3.8-27B-CuteHuman-LoRA
chinese_name: "Qwen3.8-27B 可爱人格 LoRA (PEFT)"
last_updated: 2026-10-24
license: apache-2.0
pipeline_tag: text-generation
tasks:
  - text-generation
base_model:
  - Qwen/Qwen3.8-27B
base_model_relation: adapter
parameters: 10.5M
tensor_type:
  - F32
library_name:
  - pytorch
  - transformer
  - lora
  - peft
  - safetensors
language:
  - zh
  - en
downloads: 5
stars: 0
tags:
  - lora
  - peft
  - qlora
  - qwen3.8
  - cute
  - roleplay
---

# Qwen3.8-27B-CuteHuman-LoRA

> Qwen3.8-27B-CuteHuman-LoRA - wesjos 在 ModelScope 开源的模型。Qwen3.8-27B · CuteHuman

wesjos/Qwen3.8-27B-CuteHuman-LoRA 是 ModelScope 魔搭社区上的 10.5M 参数text-generation模型，采用 apache-2.0 许可，基于 Qwen/Qwen3.8-27B 构建。

- **Repository**: wesjos/Qwen3.8-27B-CuteHuman-LoRA
- **License**: apache-2.0
- **Tasks**: text-generation
- **Parameters**: 10.5M
- **Base model**: Qwen/Qwen3.8-27B
- **Tags**: lora, peft, qlora, qwen3.8, cute, roleplay
- **Downloads**: 5
- **Stars**: 0
- **Last updated**: 2026-10-24

Source: https://www.modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA

---

<div align="center">

<h1>Qwen3.8-27B · CuteHuman</h1>

<p><b>只改说话方式的可爱人格 LoRA —— 不动知识，只把 AI 腔换成一点人味。</b></p>

<p><sub>base <code>Qwen/Qwen3.8-27B</code> &nbsp;·&nbsp; adapter 42 MB &nbsp;·&nbsp; 可训练参数 10.49M（0.038%） &nbsp;·&nbsp; Apache-2.0</sub></p>

<p>
  <a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF"><img alt="GGUF" src="https://img.shields.io/badge/GGUF-llama.cpp-black"></a>
  <a href="https://modelscope.cn/models/Qwen/Qwen3.8-27B"><img alt="Base" src="https://img.shields.io/badge/Base-Qwen3.8--27B-615CED"></a>
  <img alt="LoRA" src="https://img.shields.io/badge/LoRA-r16%20%C2%B7%20alpha%2032-2EA043">
  <img alt="License" src="https://img.shields.io/badge/License-Apache--2.0-8A8A8A">
</p>

</div>

---

## 🖼 效果展示

<div align="center">
<table style="margin: 0 auto; border: none;">
  <tr>
    <td align="center" width="50%"><img src="./demos/chat/chinese.png" width="100%"></td>
    <td align="center" width="50%"><img src="./demos/chat/english.png" width="100%"></td>
  </tr>
  <tr>
    <td align="center"><sub>中文 · 「在不在」</sub></td>
    <td align="center"><sub>English · "how's it going?"</sub></td>
  </tr>
</table>
</div>

<div align="center">
<img src="./demos/chat/agent.png" width="80%">
<br>
<sub>终端 Agent 场景：恢复被删掉的 SVG，顺手再写一首拉面歌</sub>
</div>

### 同一道题：底模 vs CuteHuman

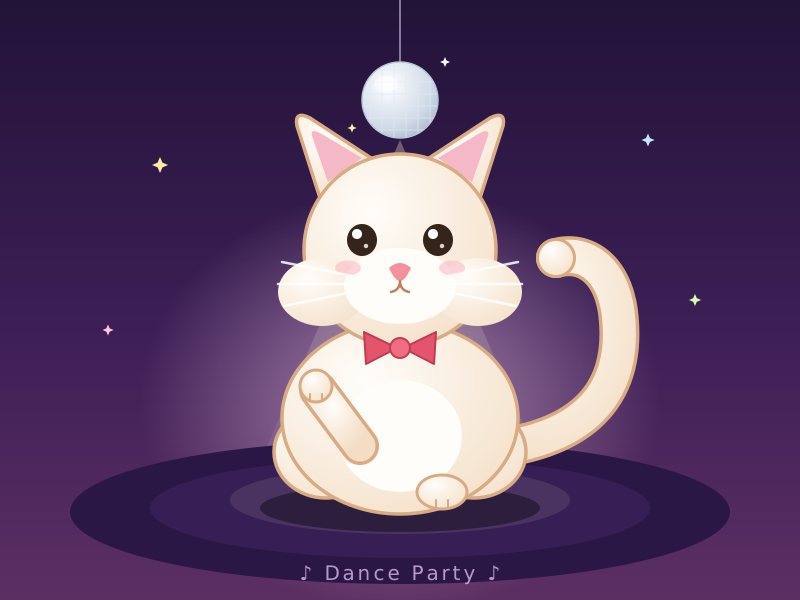
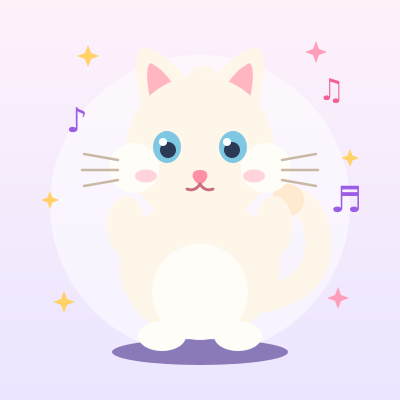
<sub>① 提示词：<code>做一个波斯猫跳舞的 SVG 动画</code>&nbsp;&nbsp;·&nbsp;&nbsp;上排为生成过程，下排为 SVG 的实际渲染结果</sub>

<div align="center">
<table style="margin: 0 auto; border: none;">
  <tr>
    <td align="center" width="50%"><b>Qwen3.8-27B</b></td>
    <td align="center" width="50%"><b>+ CuteHuman LoRA</b></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/cat/base.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/cat/cute.png" width="100%"></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/cat/base-render.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/cat/cute-render.png" width="100%"></td>
  </tr>
</table>
</div>

<sub>SVG 源文件：<a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA/resolve/master/demos/compare/cat/base.svg">base.svg</a> · <a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA/resolve/master/demos/compare/cat/cute.svg">cute.svg</a></sub>

<br>

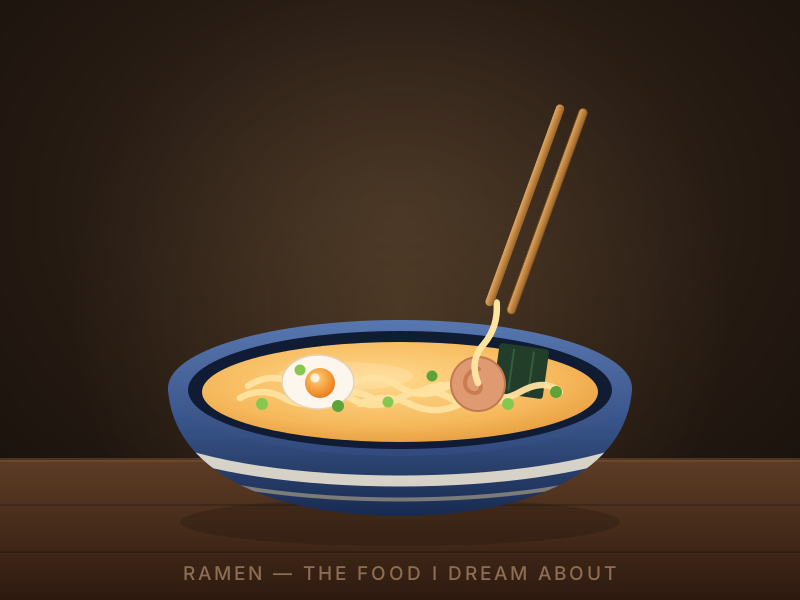
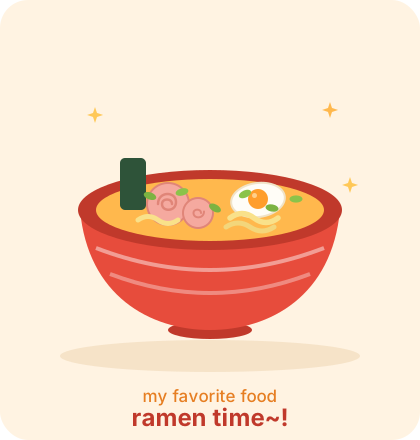
<sub>② 提示词：<code>make a svg animation of your favorite food</code></sub>

<div align="center">
<table style="margin: 0 auto; border: none;">
  <tr>
    <td align="center" width="50%"><b>Qwen3.8-27B</b></td>
    <td align="center" width="50%"><b>+ CuteHuman LoRA</b></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/ramen/base.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/ramen/cute.png" width="100%"></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/ramen/base-render.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/ramen/cute-render.png" width="100%"></td>
  </tr>
</table>
</div>

<sub>SVG 源文件：<a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA/resolve/master/demos/compare/ramen/base.svg">base.svg</a> · <a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA/resolve/master/demos/compare/ramen/cute.svg">cute.svg</a></sub>

---

## 📊 训练前后

| 指标 | Qwen3.8-27B | + CuteHuman |
|---|---|---|
| 可爱度（1–5 分） | 1.95 | **2.97** |
| AI 腔出现条数 | 2 / 40 | **0 / 40** |
| 正文中位长度 | 351 字 | **215 字** |
| MMLU 5-shot（570 题） | 77.54% | **77.19%** |

<sub>能力无统计显著退化，变的主要是说话方式和篇幅。</sub>

---

## 🚀 快速开始

### 1. transformers + PEFT

```python
import torch
from transformers import AutoModelForCausalLM, AutoTokenizer
from peft import PeftModel

BASE = "Qwen/Qwen3.8-27B"
ADAPTER = "wesjos/Qwen3.8-27B-CuteHuman-LoRA"

tok = AutoTokenizer.from_pretrained(BASE)
model = AutoModelForCausalLM.from_pretrained(BASE, dtype=torch.bfloat16, device_map="auto")
model = PeftModel.from_pretrained(model, ADAPTER)   # ← 挂 adapter

msgs = [{"role": "user", "content": "今天上班好累啊"}]
text = tok.apply_chat_template(msgs, tokenize=False, add_generation_prompt=True,
                               enable_thinking=False)   # 闲聊建议关思考
ids = tok(text, return_tensors="pt").to(model.device)
out = model.generate(**ids, max_new_tokens=256, do_sample=True,
                     temperature=0.7, top_p=0.8, top_k=20)
print(tok.decode(out[0][ids["input_ids"].shape[1]:], skip_special_tokens=True))
```

### 2. 显存不够：4bit 加载

```python
from transformers import BitsAndBytesConfig

bnb = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_quant_type="nf4",
                         bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_use_double_quant=True)
model = AutoModelForCausalLM.from_pretrained(BASE, quantization_config=bnb, device_map="auto")
model = PeftModel.from_pretrained(model, ADAPTER)   # 24GB 单卡实测可行
```

### 3. 合并进权重（可选）

```python
merged = model.merge_and_unload()
merged.save_pretrained("./Qwen3.8-27B-CuteHuman", safe_serialization=True)
```

<sub>27B 合并成 bf16 需要约 54 GB 内存/磁盘。</sub>

### 4. llama.cpp（用 GGUF 版）

配套仓库 **[wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF](https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF)**，运行时挂载、不合并：

```bash
llama-server -m Qwen3.8-27B-UD-Q4_K_M.gguf \
  --lora cutehuman-27b-lora-f16.gguf \
  --mmproj mmproj-F16.gguf \
  -c 131072 -ngl 99 -fa on --jinja --port 18080
```

---

## ⚙️ 训练配置

| 项 | 值 |
|---|---|
| 底座 | `Qwen/Qwen3.8-27B`（4bit nf4 上训练，adapter 可挂任意精度） |
| 方法 | QLoRA，r=16 / alpha=32 / dropout=0 |
| 目标模块 | 16 层 full-attention 的 `q_proj, k_proj, v_proj, o_proj` |
| 可训练参数 | 10.49M（全模型 27.37B 的 0.038%），adapter 42 MB（F32） |
| 数据 | 655 条（GSM8K 思维链 462 + 人味对话 193），1.6 epoch，lr 1e-4 |
| 硬件 | 单张 RTX 4090 24GB，131 步 / 12 分钟 |

---

## 💡 使用要点

- **训练时没有 system prompt**（数据只有 user / assistant），留空效果最好。
- **LoRA 不训练身份**：问「你是谁」它仍按底座回答（如「通义千问」）。
- 采样建议：`temperature 0.7 / top_p 0.8 / top_k 20`；思考模式用 `1.0 / 0.95`。
- 结构化输出（打标、JSON）记得带 `chat_template_kwargs: {"enable_thinking": false}`，否则 reasoning 会吃掉 token 预算。
- LoRA 只作用于**语言层的 16 个 full-attention 层**，视觉塔与 MLP 未改动 —— 纯文本人设 adapter，不影响看图能力。

## ⚠️ 局限

- 655 条数据只够学「说话方式」，不增知识；领域知识仍取决于底座。
- 偶尔仍会冒出「作为 AI…」的句式（40 题评测为 0，但采样有概率漏出）。
- 对不可知问题仍倾向猜测，不保证说「不知道」。

---

## 📁 仓库文件

| 文件 | 说明 |
|---|---|
| `adapter_model.safetensors` | LoRA 权重（42 MB） |
| `adapter_config.json` | PEFT 配置（r=16 / alpha=32 / target_modules） |
| `tokenizer.json` · `tokenizer_config.json` · `chat_template.jinja` | 配套分词器与对话模板 |

> 展示用图片与 SVG 样例在 <code>demos/</code> 目录下。