---
title: Qwen3.8-27B-CuteHuman-LoRA-GGUF
canonical_url: "https://www.modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF"
md_url: "https://www.modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF.md"
repository: wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF
chinese_name: "Qwen3.8-27B 可爱人格 LoRA (GGUF)"
last_updated: 2026-10-24
license: apache-2.0
pipeline_tag: text-generation
tasks:
  - text-generation
base_model:
  - Qwen/Qwen3.8-27B
base_model_relation: adapter
library_name:
  - lora
  - gguf
language:
  - zh
  - en
downloads: 7
stars: 1
tags:
  - lora
  - gguf
  - llama.cpp
  - qwen3.8
  - cute
  - roleplay
---

# Qwen3.8-27B-CuteHuman-LoRA-GGUF

> Qwen3.8-27B-CuteHuman-LoRA-GGUF - wesjos 在 ModelScope 开源的模型。Qwen3.8-27B · CuteHuman（GGUF）

wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF 是 ModelScope 魔搭社区上的text-generation模型，采用 apache-2.0 许可，基于 Qwen/Qwen3.8-27B 构建。

- **Repository**: wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF
- **License**: apache-2.0
- **Tasks**: text-generation
- **Base model**: Qwen/Qwen3.8-27B
- **Tags**: lora, gguf, llama.cpp, qwen3.8, cute, roleplay
- **Downloads**: 7
- **Stars**: 1
- **Last updated**: 2026-10-24

Source: https://www.modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF

---

<div align="center">

<h1>Qwen3.8-27B · CuteHuman（GGUF）</h1>

<p><b>可爱人格 LoRA 的 GGUF 版 —— 给 <code>llama.cpp</code> 运行时挂载，不合并、不掉精度。</b></p>

<p><sub>21 MB / f16 / 128 个 tensor &nbsp;·&nbsp; 内嵌 alpha=32，运行时 scale = 2.0 &nbsp;·&nbsp; Apache-2.0</sub></p>

<p>
  <a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA"><img alt="PEFT" src="https://img.shields.io/badge/PEFT-%E5%8E%9F%E5%A7%8B%20adapter-615CED"></a>
  <a href="https://modelscope.cn/models/Qwen/Qwen3.8-27B"><img alt="Base" src="https://img.shields.io/badge/Base-Qwen3.8--27B-black"></a>
  <img alt="llama.cpp" src="https://img.shields.io/badge/llama.cpp-ready-2EA043">
  <img alt="License" src="https://img.shields.io/badge/License-Apache--2.0-8A8A8A">
</p>

</div>

---

## 🖼 效果展示

<div align="center">
<table style="margin: 0 auto; border: none;">
  <tr>
    <td align="center" width="50%"><img src="./demos/chat/chinese.png" width="100%"></td>
    <td align="center" width="50%"><img src="./demos/chat/english.png" width="100%"></td>
  </tr>
  <tr>
    <td align="center"><sub>中文 · 「在不在」</sub></td>
    <td align="center"><sub>English · "how's it going?"</sub></td>
  </tr>
</table>
</div>

<div align="center">
<img src="./demos/chat/agent.png" width="80%">
<br>
<sub>终端 Agent 场景：恢复被删掉的 SVG，顺手再写一首拉面歌</sub>
</div>

### 同一道题：底模 vs CuteHuman

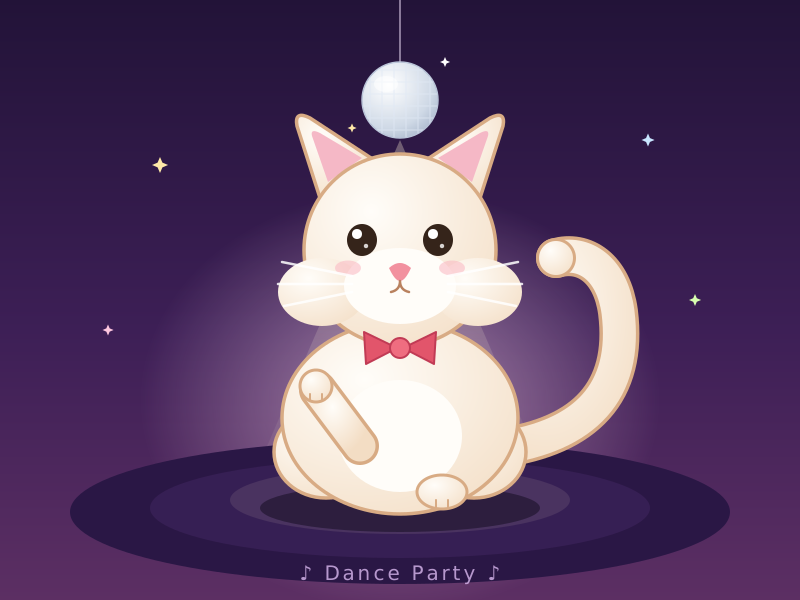
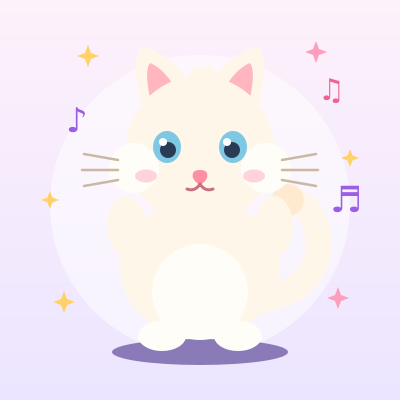
<sub>① 提示词：<code>做一个波斯猫跳舞的 SVG 动画</code>&nbsp;&nbsp;·&nbsp;&nbsp;上排为生成过程，下排为 SVG 的实际渲染结果</sub>

<div align="center">
<table style="margin: 0 auto; border: none;">
  <tr>
    <td align="center" width="50%"><b>Qwen3.8-27B</b></td>
    <td align="center" width="50%"><b>+ CuteHuman LoRA</b></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/cat/base.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/cat/cute.png" width="100%"></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/cat/base-render.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/cat/cute-render.png" width="100%"></td>
  </tr>
</table>
</div>

<sub>SVG 源文件：<a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF/resolve/master/demos/compare/cat/base.svg">base.svg</a> · <a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF/resolve/master/demos/compare/cat/cute.svg">cute.svg</a></sub>

<br>

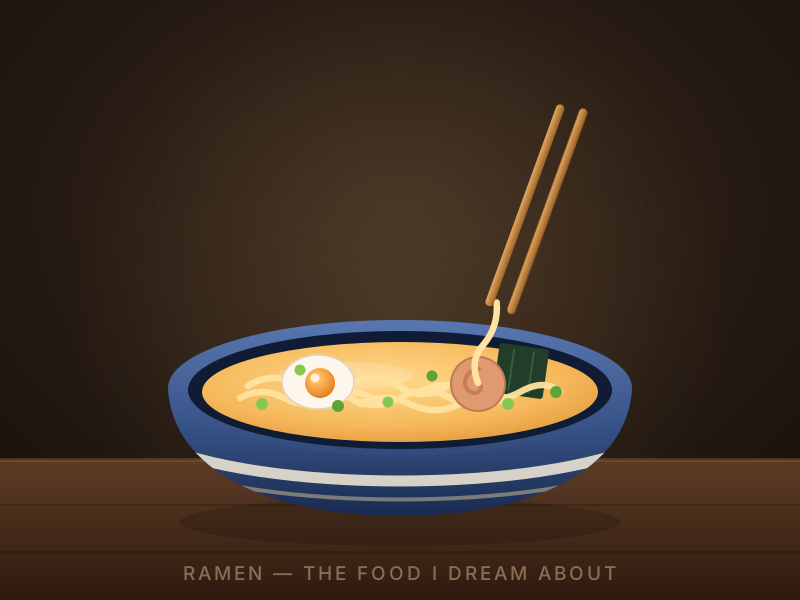
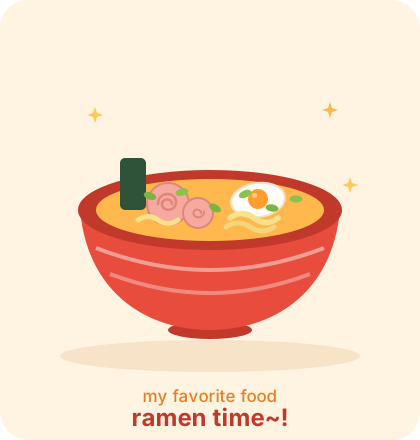
<sub>② 提示词：<code>make a svg animation of your favorite food</code></sub>

<div align="center">
<table style="margin: 0 auto; border: none;">
  <tr>
    <td align="center" width="50%"><b>Qwen3.8-27B</b></td>
    <td align="center" width="50%"><b>+ CuteHuman LoRA</b></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/ramen/base.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/ramen/cute.png" width="100%"></td>
  </tr>
  <tr>
    <td align="center"><img src="./demos/compare/ramen/base-render.png" width="100%"></td>
    <td align="center"><img src="./demos/compare/ramen/cute-render.png" width="100%"></td>
  </tr>
</table>
</div>

<sub>SVG 源文件：<a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF/resolve/master/demos/compare/ramen/base.svg">base.svg</a> · <a href="https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA-GGUF/resolve/master/demos/compare/ramen/cute.svg">cute.svg</a></sub>

---

## 📊 训练前后

| 指标 | 无 LoRA | 有 LoRA |
|---|---|---|
| 正文中位长度 | 268 字 | **69 字** |
| 可爱度（1–5 分） | 1.95 | **2.97** |
| AI 腔出现条数 | 2 / 40 | **0 / 40** |
| MMLU 5-shot（570 题） | 77.54% | **77.19%** |

<sub>能力基本无损，主要是说话方式与篇幅的变化。</sub>

---

## 🚀 怎么用

**前提**：任意 Qwen3.8-27B 的 GGUF 底模（推荐 unsloth 的 `Qwen3.8-27B-UD-Q4_K_M.gguf`；要视觉就再配 `mmproj-F16.gguf`）。

### llama-server

```bash
llama-server \
  -m Qwen3.8-27B-UD-Q4_K_M.gguf \
  --lora cutehuman-27b-lora-f16.gguf \
  --mmproj mmproj-F16.gguf \
  -c 32768 -ngl 99 -fa on --jinja \
  --alias qwen3.8-27b --host 0.0.0.0 --port 18080
```

### llama-cli 单次推理

```bash
llama-cli -m Qwen3.8-27B-UD-Q4_K_M.gguf --lora cutehuman-27b-lora-f16.gguf \
  -p "今天上班好累啊" -n 256 --temp 0.7 --top-p 0.8
```

### 确认真的挂上了

```bash
curl -s http://127.0.0.1:18080/lora-adapters
# 期望: [{"id":0,"path":".../cutehuman-27b-lora-f16.gguf","scale":1.0,...}]
```

### 运行时开关 / 调强度（不用重启）

```bash
# 关掉（等价纯底模）
curl -X POST http://127.0.0.1:18080/lora-adapters -H 'Content-Type: application/json' -d '[{"id":0,"scale":0.0}]'
# 半强度
curl -X POST http://127.0.0.1:18080/lora-adapters -H 'Content-Type: application/json' -d '[{"id":0,"scale":0.5}]'
# 打开
curl -X POST http://127.0.0.1:18080/lora-adapters -H 'Content-Type: application/json' -d '[{"id":0,"scale":1.0}]'
```

<sub>也可以在启动时固定缩放：<code>--lora-scaled cutehuman-27b-lora-f16.gguf:0.6</code></sub>

---

## 💡 使用要点

- **训练时没有 system prompt**（数据只有 user / assistant），留空效果最好。
- 闲聊建议关思考：请求体带 `"chat_template_kwargs": {"enable_thinking": false}`。
- 采样建议 `temperature 0.7 / top_p 0.8 / top_k 20`；思考模式用官方默认 `1.0 / 0.95`。
- 只需要语言层：LoRA 不碰视觉塔，`--mmproj` 照常加载，看图能力不受影响。
- **不要开 MTP 投机解码**（`--spec-type draft-mtp`）：draft head 是底模训的，挂 LoRA 后命中率骤降，实测从 41.5 tok/s 掉到 27.8 tok/s，还白占 1.3 GB 显存。

---

## 📁 与本仓库配套

| 文件 / 仓库 | 说明 |
|---|---|
| `cutehuman-27b-lora-f16.gguf` | 本仓库的 adapter（21 MB，128 tensor） |
| [wesjos/Qwen3.8-27B-CuteHuman-LoRA](https://modelscope.cn/models/wesjos/Qwen3.8-27B-CuteHuman-LoRA) | 同款 LoRA 的 PEFT 原始版（transformers / vLLM） |

> LoRA 参数：r=16 / alpha=32 / dropout=0，只挂 16 层 full-attention 的 `q_proj, k_proj, v_proj, o_proj`，可训练参数 10.49M（0.038%）。
> 展示用图片与 SVG 样例在 <code>demos/</code> 目录下。