---
title: Qwen2.5-Math-72B-Instruct
canonical_url: "https://www.modelscope.cn/models/unsloth/Qwen2.5-Math-72B-Instruct"
md_url: "https://www.modelscope.cn/models/unsloth/Qwen2.5-Math-72B-Instruct.md"
repository: unsloth/Qwen2.5-Math-72B-Instruct
last_updated: 2024-11-13
license: other
pipeline_tag: text-generation
tasks:
- text-generation
model_type:
- qwen2
architectures:
- Qwen2ForCausalLM
base_model:
- Qwen/Qwen2.5-Math-72B-Instruct
base_model_relation: finetune
parameters: 72.7B
tensor_type:
- BF16
library_name:
- transformer
- safetensors
- pytorch
frameworks:
- pytorch
language:
- en
inference_backends:
- "deploy_task text/emb"
- "lmdeploy 0.9.1"
- "lmdeploy_turbomind 0.9.1"
- "sglang 0.5.2"
- "vllm 0.9.2"
downloads: 1832
stars: 0
tags:
- unsloth
- transformers
---
# Qwen2.5-Math-72B-Instruct
> Qwen2.5-Math-72B-Instruct - unsloth 在 ModelScope 开源的模型。Finetune Llama 3.1, Gemma 2, Mistral 2-5x faster with 70% less memory via Unsloth!
unsloth/Qwen2.5-Math-72B-Instruct 是 ModelScope 魔搭社区上的 72.7B 参数text-generation模型,采用 other 许可,基于 Qwen/Qwen2.5-Math-72B-Instruct 构建,可用 deploy_task text/emb、lmdeploy 0.9.1、lmdeploy_turbomind 0.9.1 部署。
- **Repository**: unsloth/Qwen2.5-Math-72B-Instruct
- **License**: other
- **Tasks**: text-generation
- **Parameters**: 72.7B
- **Base model**: Qwen/Qwen2.5-Math-72B-Instruct
- **Inference backends**: deploy_task text/emb, lmdeploy 0.9.1, lmdeploy_turbomind 0.9.1, sglang 0.5.2, vllm 0.9.2
- **Tags**: unsloth, transformers
- **Downloads**: 1832
- **Stars**: 0
- **Last updated**: 2024-11-13
Source: https://www.modelscope.cn/models/unsloth/Qwen2.5-Math-72B-Instruct
---
# Finetune Llama 3.1, Gemma 2, Mistral 2-5x faster with 70% less memory via Unsloth!
We have a Qwen 2.5 (all model sizes) [free Google Colab Tesla T4 notebook](https://colab.research.google.com/drive/1Kose-ucXO1IBaZq5BvbwWieuubP7hxvQ?usp=sharing).
Also a [Qwen 2.5 conversational style notebook](https://colab.research.google.com/drive/1qN1CEalC70EO1wGKhNxs1go1W9So61R5?usp=sharing).
[ ](https://discord.gg/unsloth)
[
 ](https://github.com/unslothai/unsloth)
## ✨ Finetune for Free
All notebooks are **beginner friendly**! Add your dataset, click "Run All", and you'll get a 2x faster finetuned model which can be exported to GGUF, vLLM or uploaded to Hugging Face.
| Unsloth supports | Free Notebooks | Performance | Memory use |
|-----------------|--------------------------------------------------------------------------------------------------------------------------|-------------|----------|
| **Llama-3.1 8b** | [▶️ Start on Colab](https://colab.research.google.com/drive/1Ys44kVvmeZtnICzWz0xgpRnrIOjZAuxp?usp=sharing) | 2.4x faster | 58% less |
| **Phi-3.5 (mini)** | [▶️ Start on Colab](https://colab.research.google.com/drive/1lN6hPQveB_mHSnTOYifygFcrO8C1bxq4?usp=sharing) | 2x faster | 50% less |
| **Gemma-2 9b** | [▶️ Start on Colab](https://colab.research.google.com/drive/1vIrqH5uYDQwsJ4-OO3DErvuv4pBgVwk4?usp=sharing) | 2.4x faster | 58% less |
| **Mistral 7b** | [▶️ Start on Colab](https://colab.research.google.com/drive/1Dyauq4kTZoLewQ1cApceUQVNcnnNTzg_?usp=sharing) | 2.2x faster | 62% less |
| **TinyLlama** | [▶️ Start on Colab](https://colab.research.google.com/drive/1AZghoNBQaMDgWJpi4RbffGM1h6raLUj9?usp=sharing) | 3.9x faster | 74% less |
| **DPO - Zephyr** | [▶️ Start on Colab](https://colab.research.google.com/drive/15vttTpzzVXv_tJwEk-hIcQ0S9FcEWvwP?usp=sharing) | 1.9x faster | 19% less |
- This [conversational notebook](https://colab.research.google.com/drive/1Aau3lgPzeZKQ-98h69CCu1UJcvIBLmy2?usp=sharing) is useful for ShareGPT ChatML / Vicuna templates.
- This [text completion notebook](https://colab.research.google.com/drive/1ef-tab5bhkvWmBOObepl1WgJvfvSzn5Q?usp=sharing) is for raw text. This [DPO notebook](https://colab.research.google.com/drive/15vttTpzzVXv_tJwEk-hIcQ0S9FcEWvwP?usp=sharing) replicates Zephyr.
- \* Kaggle has 2x T4s, but we use 1. Due to overhead, 1x T4 is 5x faster.
# Qwen2.5-Math-72B-Instruct
> [!Warning]
>
>
> 🚨 Qwen2.5-Math mainly supports solving English and Chinese math problems through CoT and TIR. We do not recommend using this series of models for other tasks.
>
>
## Introduction
In August 2024, we released the first series of mathematical LLMs - [Qwen2-Math](https://qwenlm.github.io/blog/qwen2-math/) - of our Qwen family. A month later, we have upgraded it and open-sourced **Qwen2.5-Math** series, including base models **Qwen2.5-Math-1.5B/7B/72B**, instruction-tuned models **Qwen2.5-Math-1.5B/7B/72B-Instruct**, and mathematical reward model **Qwen2.5-Math-RM-72B**.
Unlike Qwen2-Math series which only supports using Chain-of-Thught (CoT) to solve English math problems, Qwen2.5-Math series is expanded to support using both CoT and Tool-integrated Reasoning (TIR) to solve math problems in both Chinese and English. The Qwen2.5-Math series models have achieved significant performance improvements compared to the Qwen2-Math series models on the Chinese and English mathematics benchmarks with CoT.
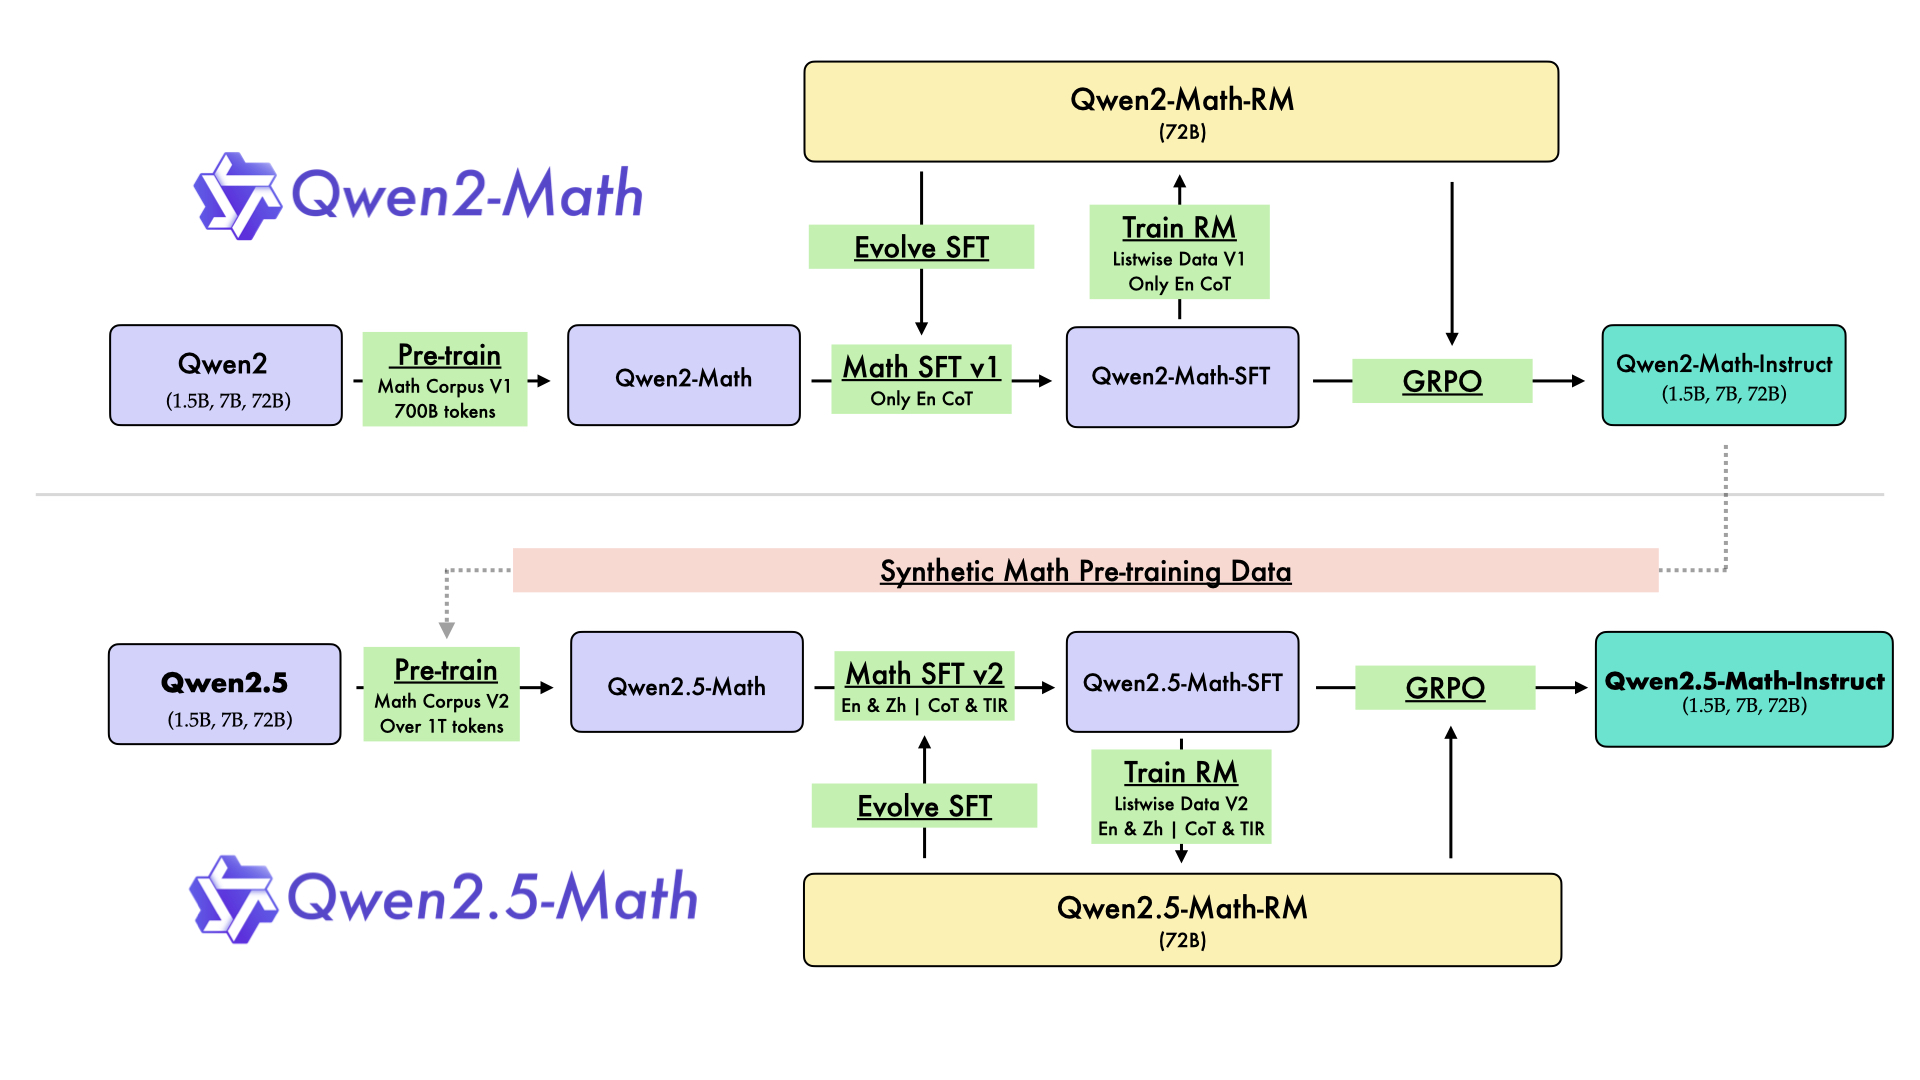
While CoT plays a vital role in enhancing the reasoning capabilities of LLMs, it faces challenges in achieving computational accuracy and handling complex mathematical or algorithmic reasoning tasks, such as finding the roots of a quadratic equation or computing the eigenvalues of a matrix. TIR can further improve the model's proficiency in precise computation, symbolic manipulation, and algorithmic manipulation. Qwen2.5-Math-1.5B/7B/72B-Instruct achieve 79.7, 85.3, and 87.8 respectively on the MATH benchmark using TIR.
## Model Details
For more details, please refer to our [blog post](https://qwenlm.github.io/blog/qwen2.5-math/) and [GitHub repo](https://github.com/QwenLM/Qwen2.5-Math).
## Requirements
* `transformers>=4.37.0` for Qwen2.5-Math models. The latest version is recommended.
> [!Warning]
>
>
> 🚨 This is a must because transformers integrated Qwen2 codes since 4.37.0.
>
>
For requirements on GPU memory and the respective throughput, see similar results of Qwen2 [here](https://qwen.readthedocs.io/en/latest/benchmark/speed_benchmark.html).
## Quick Start
> [!Important]
>
> **Qwen2.5-Math-72B-Instruct** is an instruction model for chatting;
>
> **Qwen2.5-Math-72B** is a base model typically used for completion and few-shot inference, serving as a better starting point for fine-tuning.
>
### 🤗 Hugging Face Transformers
Qwen2.5-Math can be deployed and infered in the same way as [Qwen2.5](https://github.com/QwenLM/Qwen2.5). Here we show a code snippet to show you how to use the chat model with `transformers`:
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
model_name = "Qwen/Qwen2.5-Math-72B-Instruct"
device = "cuda" # the device to load the model onto
model = AutoModelForCausalLM.from_pretrained(
model_name,
torch_dtype="auto",
device_map="auto"
)
tokenizer = AutoTokenizer.from_pretrained(model_name)
prompt = "Find the value of $x$ that satisfies the equation $4x+5 = 6x+7$."
# CoT
messages = [
{"role": "system", "content": "Please reason step by step, and put your final answer within \\boxed{}."},
{"role": "user", "content": prompt}
]
# TIR
messages = [
{"role": "system", "content": "Please integrate natural language reasoning with programs to solve the problem above, and put your final answer within \\boxed{}."},
{"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
messages,
tokenize=False,
add_generation_prompt=True
)
model_inputs = tokenizer([text], return_tensors="pt").to(device)
generated_ids = model.generate(
**model_inputs,
max_new_tokens=512
)
generated_ids = [
output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)
]
response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
```
## Citation
If you find our work helpful, feel free to give us a citation.
```
@article{yang2024qwen25mathtechnicalreportmathematical,
title={Qwen2.5-Math Technical Report: Toward Mathematical Expert Model via Self-Improvement},
author={An Yang and Beichen Zhang and Binyuan Hui and Bofei Gao and Bowen Yu and Chengpeng Li and Dayiheng Liu and Jianhong Tu and Jingren Zhou and Junyang Lin and Keming Lu and Mingfeng Xue and Runji Lin and Tianyu Liu and Xingzhang Ren and Zhenru Zhang},
journal={arXiv preprint arXiv:2409.12122},
year={2024}
}
```