---
title: Qwen-Image-2.1-GGUF
canonical_url: "https://www.modelscope.cn/models/unsloth/Qwen-Image-2.1-GGUF"
md_url: "https://www.modelscope.cn/models/unsloth/Qwen-Image-2.1-GGUF.md"
repository: unsloth/Qwen-Image-2.1-GGUF
last_updated: 2026-09-23
license: other
pipeline_tag: text-to-image-synthesis
tasks:
- text-to-image-synthesis
base_model:
- Qwen/Qwen-Image-2.1
base_model_relation: quantized
library_name:
- pytorch
- gguf
frameworks:
- pytorch
language:
- en
- zh
downloads: 1640
stars: 7
tags:
- gguf
- quantized
- unsloth
- qwen
- image-generation
---
# Qwen-Image-2.1-GGUF
> Qwen-Image-2.1-GGUF - unsloth 在 ModelScope 开源的模型。Read our How to Run Qwen-Image-2.1 Guide! 💜
unsloth/Qwen-Image-2.1-GGUF 是 ModelScope 魔搭社区上的text-to-image-synthesis模型,采用 other 许可,基于 Qwen/Qwen-Image-2.1 构建。
- **Repository**: unsloth/Qwen-Image-2.1-GGUF
- **License**: other
- **Tasks**: text-to-image-synthesis
- **Base model**: Qwen/Qwen-Image-2.1
- **Tags**: gguf, quantized, unsloth, qwen, image-generation
- **Downloads**: 1640
- **Stars**: 7
- **Last updated**: 2026-09-23
Source: https://www.modelscope.cn/models/unsloth/Qwen-Image-2.1-GGUF
---
# Read our How to [Run Qwen-Image-2.1 Guide!](https://unsloth.ai/docs/models/qwen-image-2.1) 💜
This is a GGUF quantized version of [Qwen-Image-2.1](https://huggingface.co/Qwen/Qwen-Image-2.1).
unsloth/Qwen-Image-2.1-GGUF uses [Unsloth Dynamic 2.0](https://docs.unsloth.ai/basics/unsloth-dynamic-2.0-ggufs) methodology for SOTA performance.
- Important layers are upcasted to higher precision, per tensor, from a measured sensitivity scan.
- Run these with [Unsloth Desktop](https://github.com/unslothai/unsloth), stable-diffusion.cpp and more. A GGUF is the denoiser only, so it needs the VAE and the Qwen3-VL text encoder alongside it.
- VAE: [unsloth/Qwen-Image-2.1-FP8](https://huggingface.co/unsloth/Qwen-Image-2.1-FP8) `vae/qwen_image_2.1_vae_bf16.safetensors`. Text encoder: [unsloth/Qwen3-VL-8B-Instruct-GGUF](https://huggingface.co/unsloth/Qwen3-VL-8B-Instruct-GGUF) `Qwen3-VL-8B-Instruct-UD-Q4_K_XL.gguf`, the Dynamic 2.0 4-bit rung rather than the uniform `Q4_K_M`. Measured against the `Q4_K_M` encoder at a shared seed, with the denoiser and VAE held fixed: LPIPS 0.029, SSIM 0.959, 5.15 GB vs 5.03 GB, 36.5 s vs 39.0 s.
See below for image editing operating inside of Unsloth Desktop:
 ```bash
sd-cli --diffusion-model qwen-image-2.1-Q4_K_M.gguf \
--vae qwen_image_2.1_vae_bf16.safetensors \
--llm Qwen3-VL-8B-Instruct-UD-Q4_K_XL.gguf \
-p "a cartoon sloth mascot waving, flat vector illustration, bright colours" \
--steps 20 --cfg-scale 6.0 --sampling-method euler -W 1024 -H 1024 --diffusion-fa \
-o out.png
```
### Samples
Rendered with the Q4_K_M denoiser and the Q4_K_M text encoder, 1024x1024, 20 steps, cfg 6.0, euler.
---
🤖 ModelScope |
🤗 HuggingFace |
📑 Blog |
🖥️ Demo |
🫨 Discord |
💬 WeChat
## Introduction
We are excited to open-source **Qwen-Image-2.1**, a unified text-to-image generation and image editing model in the Qwen family. With just **7B parameters in its visual generation component** (32 Single-Stream DiT layers), Qwen-Image-2.1 balances generation quality, inference efficiency, and versatility.
Four key improvements define this release:
- **Compact and Efficient**: a lightweight architecture with mixed-granularity attention and prefix KV cache reuse delivers strong image quality at low computational cost.
- **Native Transparency, Unified Creation and Editing**: generate regular or transparent (RGBA) images from text, edit transparent layers, and extract subjects from photographs, all in one model.
- **Versatile Editing**: support up to **10 reference images**, specify local edits via circles, painted annotations, or separate masks, and preserve identity for people and products.
- **Realistic Textures and Refined Aesthetics**: improved typography, portrait lighting, and fine details for more visually compelling results.
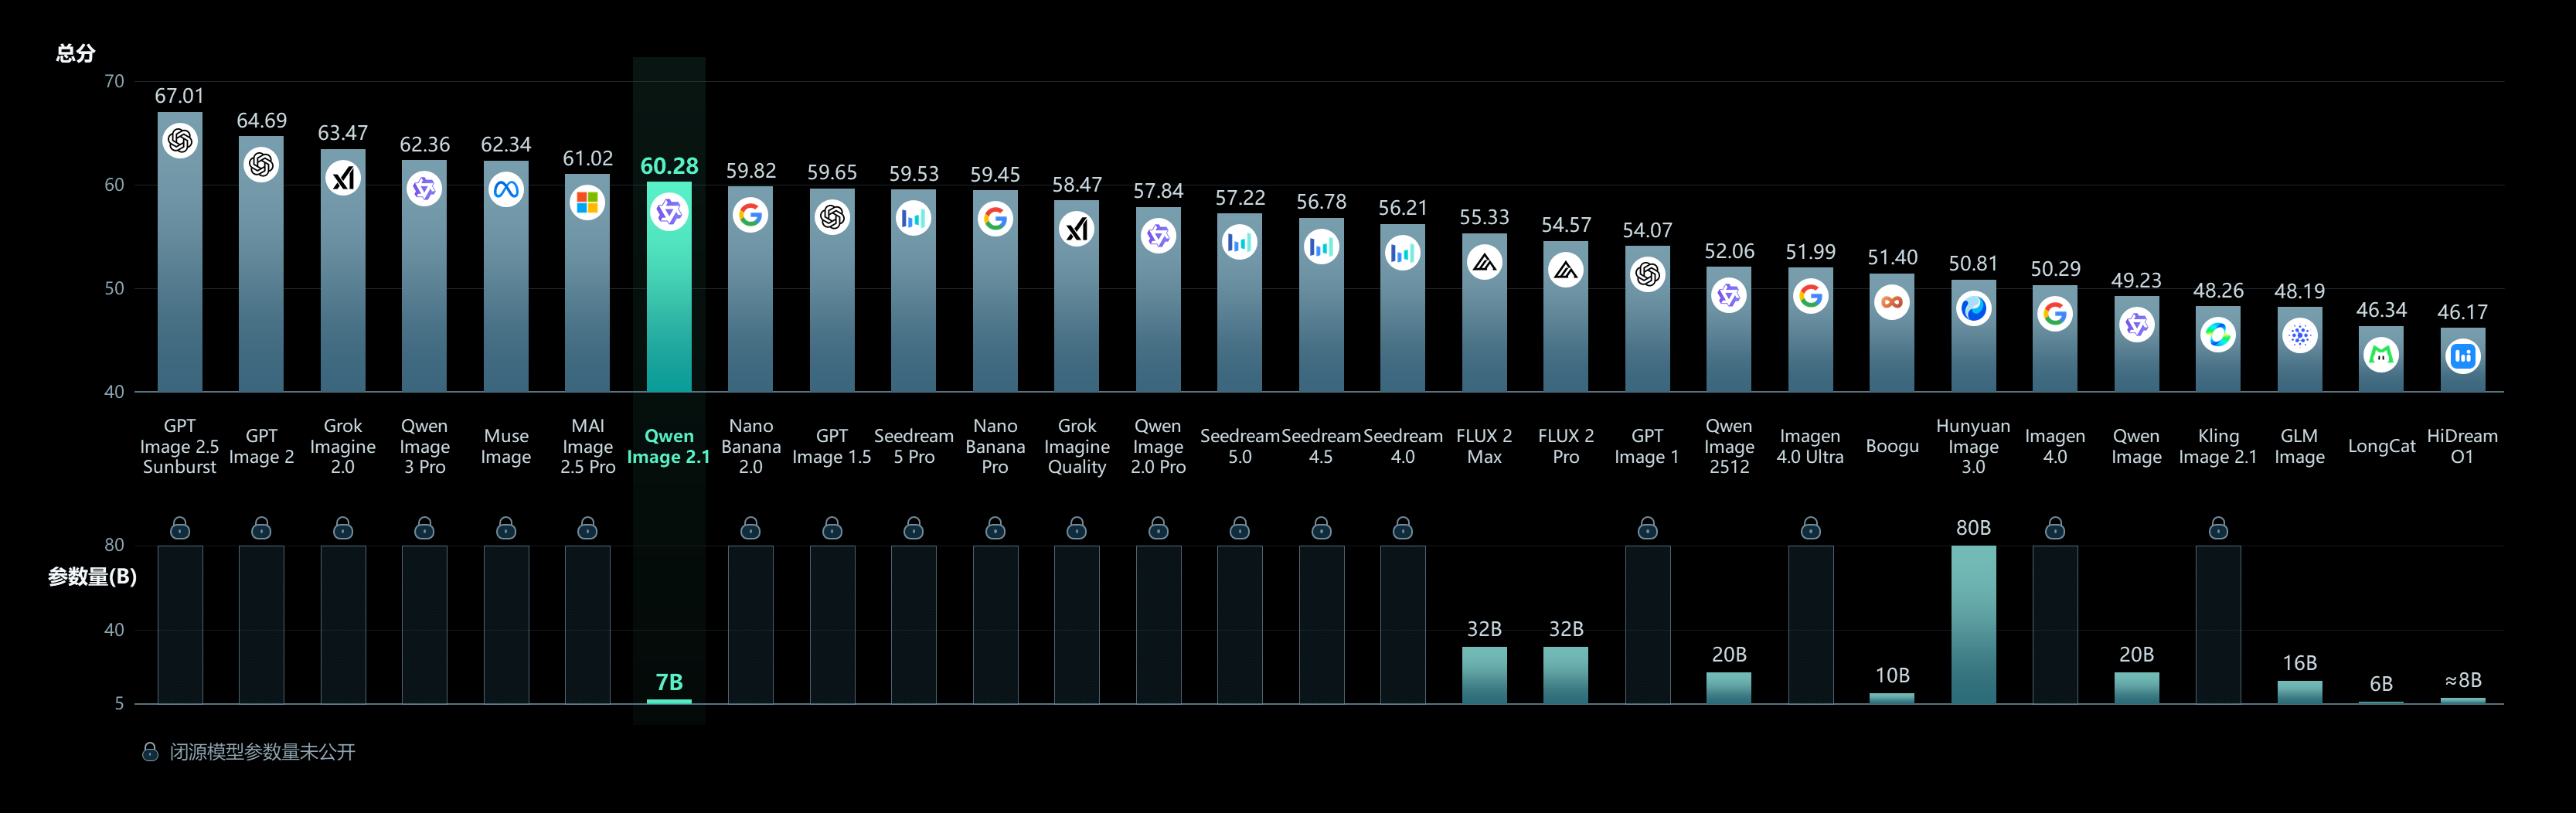
For more details, see the [GitHub repo](https://github.com/QwenLM/Qwen-Image-2.1) and [Blog](https://qwen.ai/blog?id=qwen-image-2.1).
## Quick Start
### Installation
```bash
pip install torch>=2.4.0
pip install transformers>=5.17
pip install git+https://github.com/huggingface/diffusers
pip install accelerate pillow
```
### Text-to-Image
```python
import torch
from diffusers import QwenImage21Pipeline
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")
image = pipe(
prompt="A neon shop sign that reads \"QWEN IMAGE 2.1\", rainy night, reflections on wet pavement",
width=2048, height=2048,
num_inference_steps=40,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("t2i_example.png")
```
### Image Editing
```python
import torch
from PIL import Image
from diffusers import QwenImage21Pipeline
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
).to("cuda")
input_image = Image.open("input.png")
image = pipe(
prompt="Change the background to a sunset beach",
image=input_image,
num_inference_steps=40,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("edit_example.png")
```
### Transparent Image Generation (RGBA)
Use the recommended prompt format for transparent images:
```python
image = pipe(
prompt="This is an RGBA image with transparency. A cute cartoon dragon sticker. The image has alpha channel and the background is transparent.",
width=2048, height=2048,
num_inference_steps=40,
generator=torch.Generator("cuda").manual_seed(42),
).images[0]
image.save("transparent_example.png")
```
### Supported Aspect Ratios
```python
aspect_ratios = {
"1:1": (2048, 2048),
"4:3": (2400, 1792),
"3:4": (1792, 2400),
"3:2": (2528, 1696),
"2:3": (1696, 2528),
"16:9": (2752, 1536),
"9:16": (1536, 2752),
}
```
### Memory Optimization
```python
pipe = QwenImage21Pipeline.from_pretrained(
"Qwen/Qwen-Image-2.1", torch_dtype=torch.bfloat16
)
pipe.enable_model_cpu_offload()
```
## Showcase
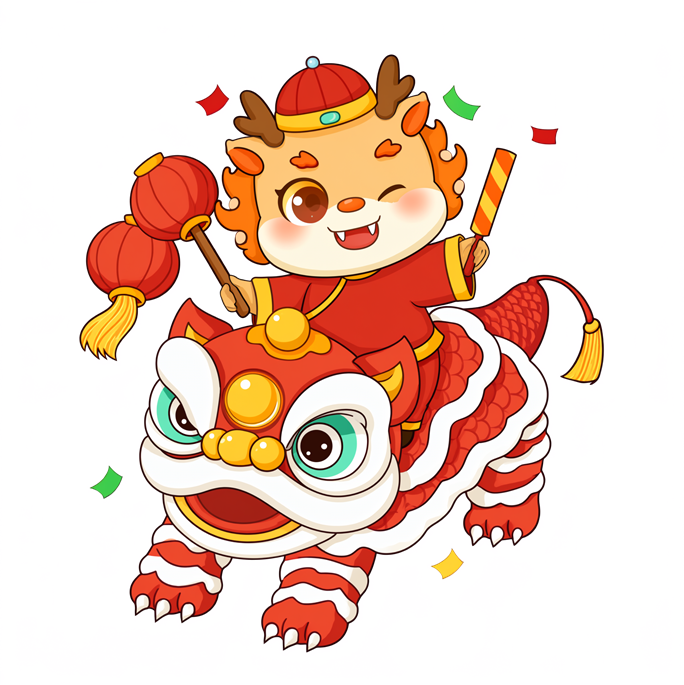
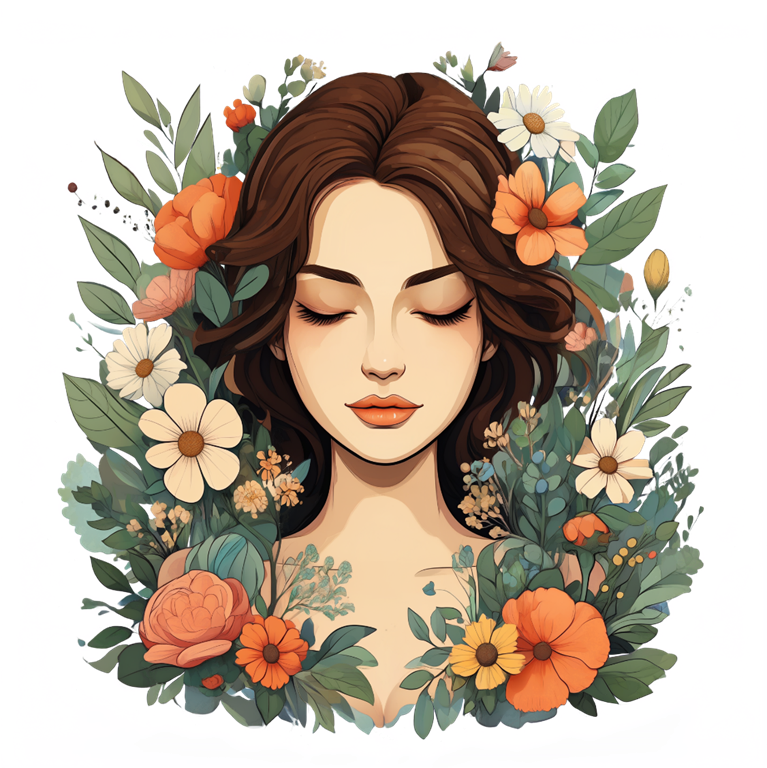
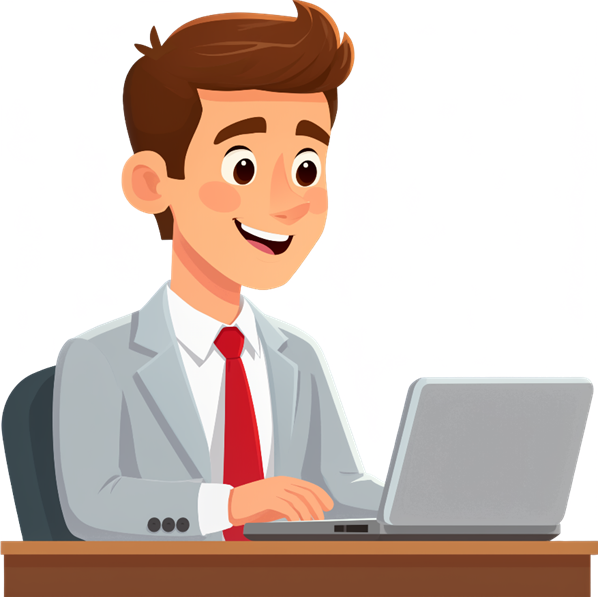
Native transparent image generation
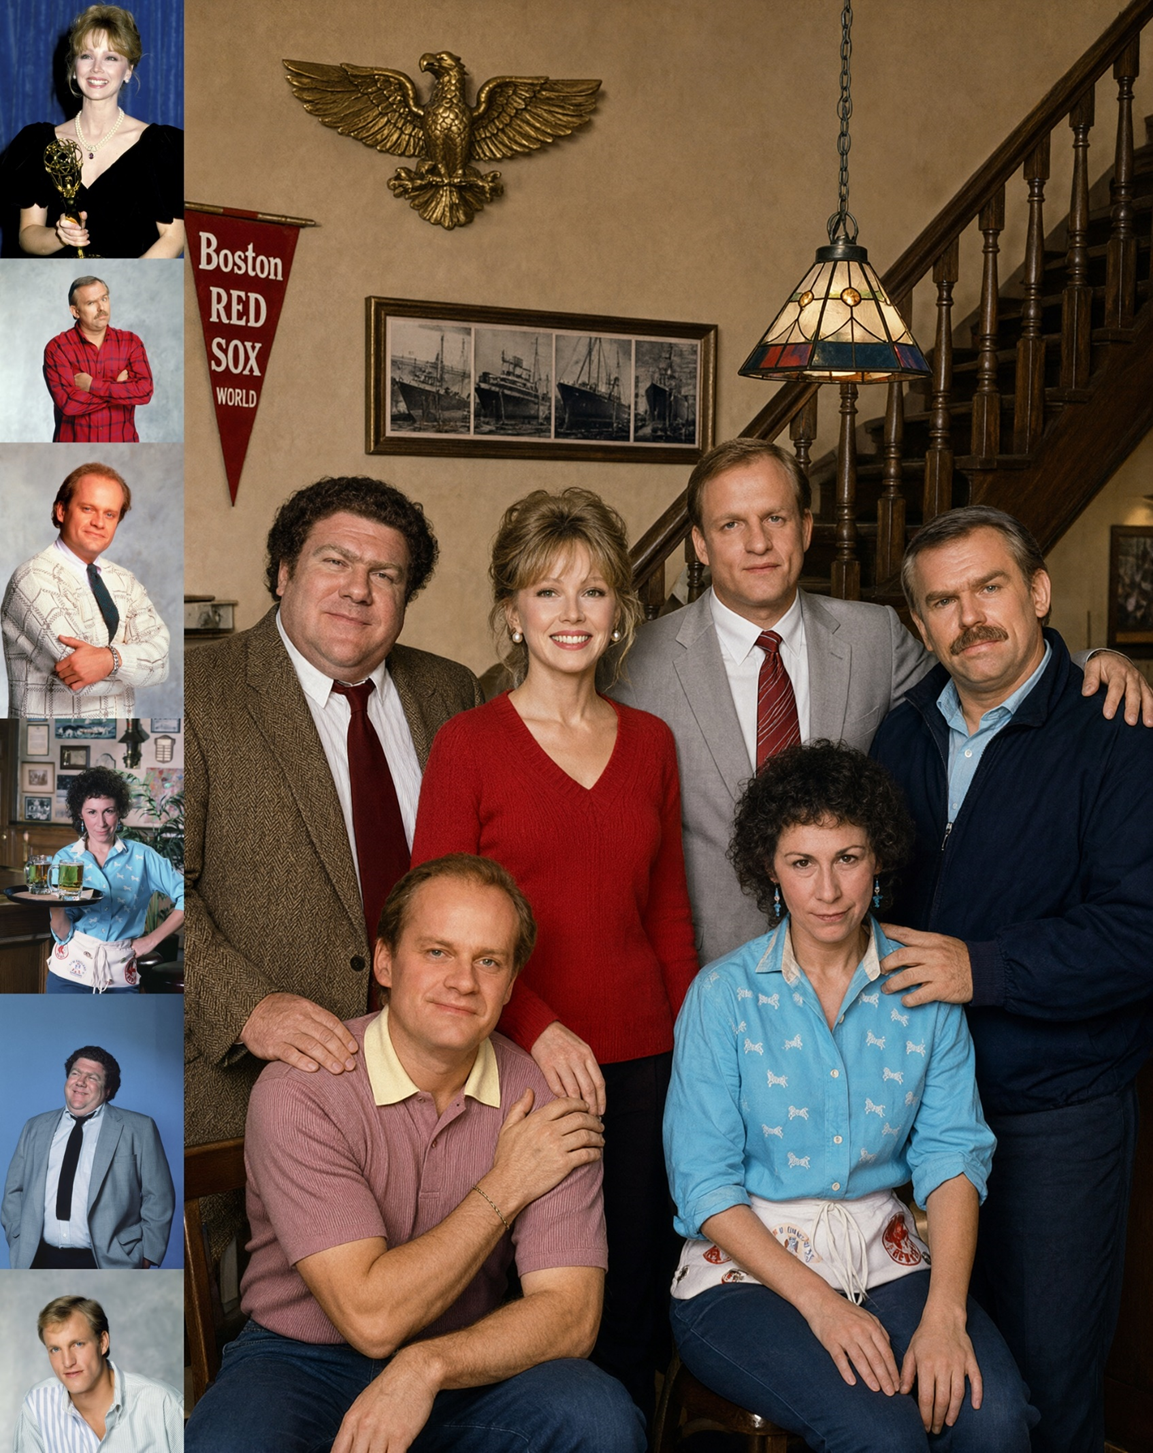
Group photograph generated from six portrait references
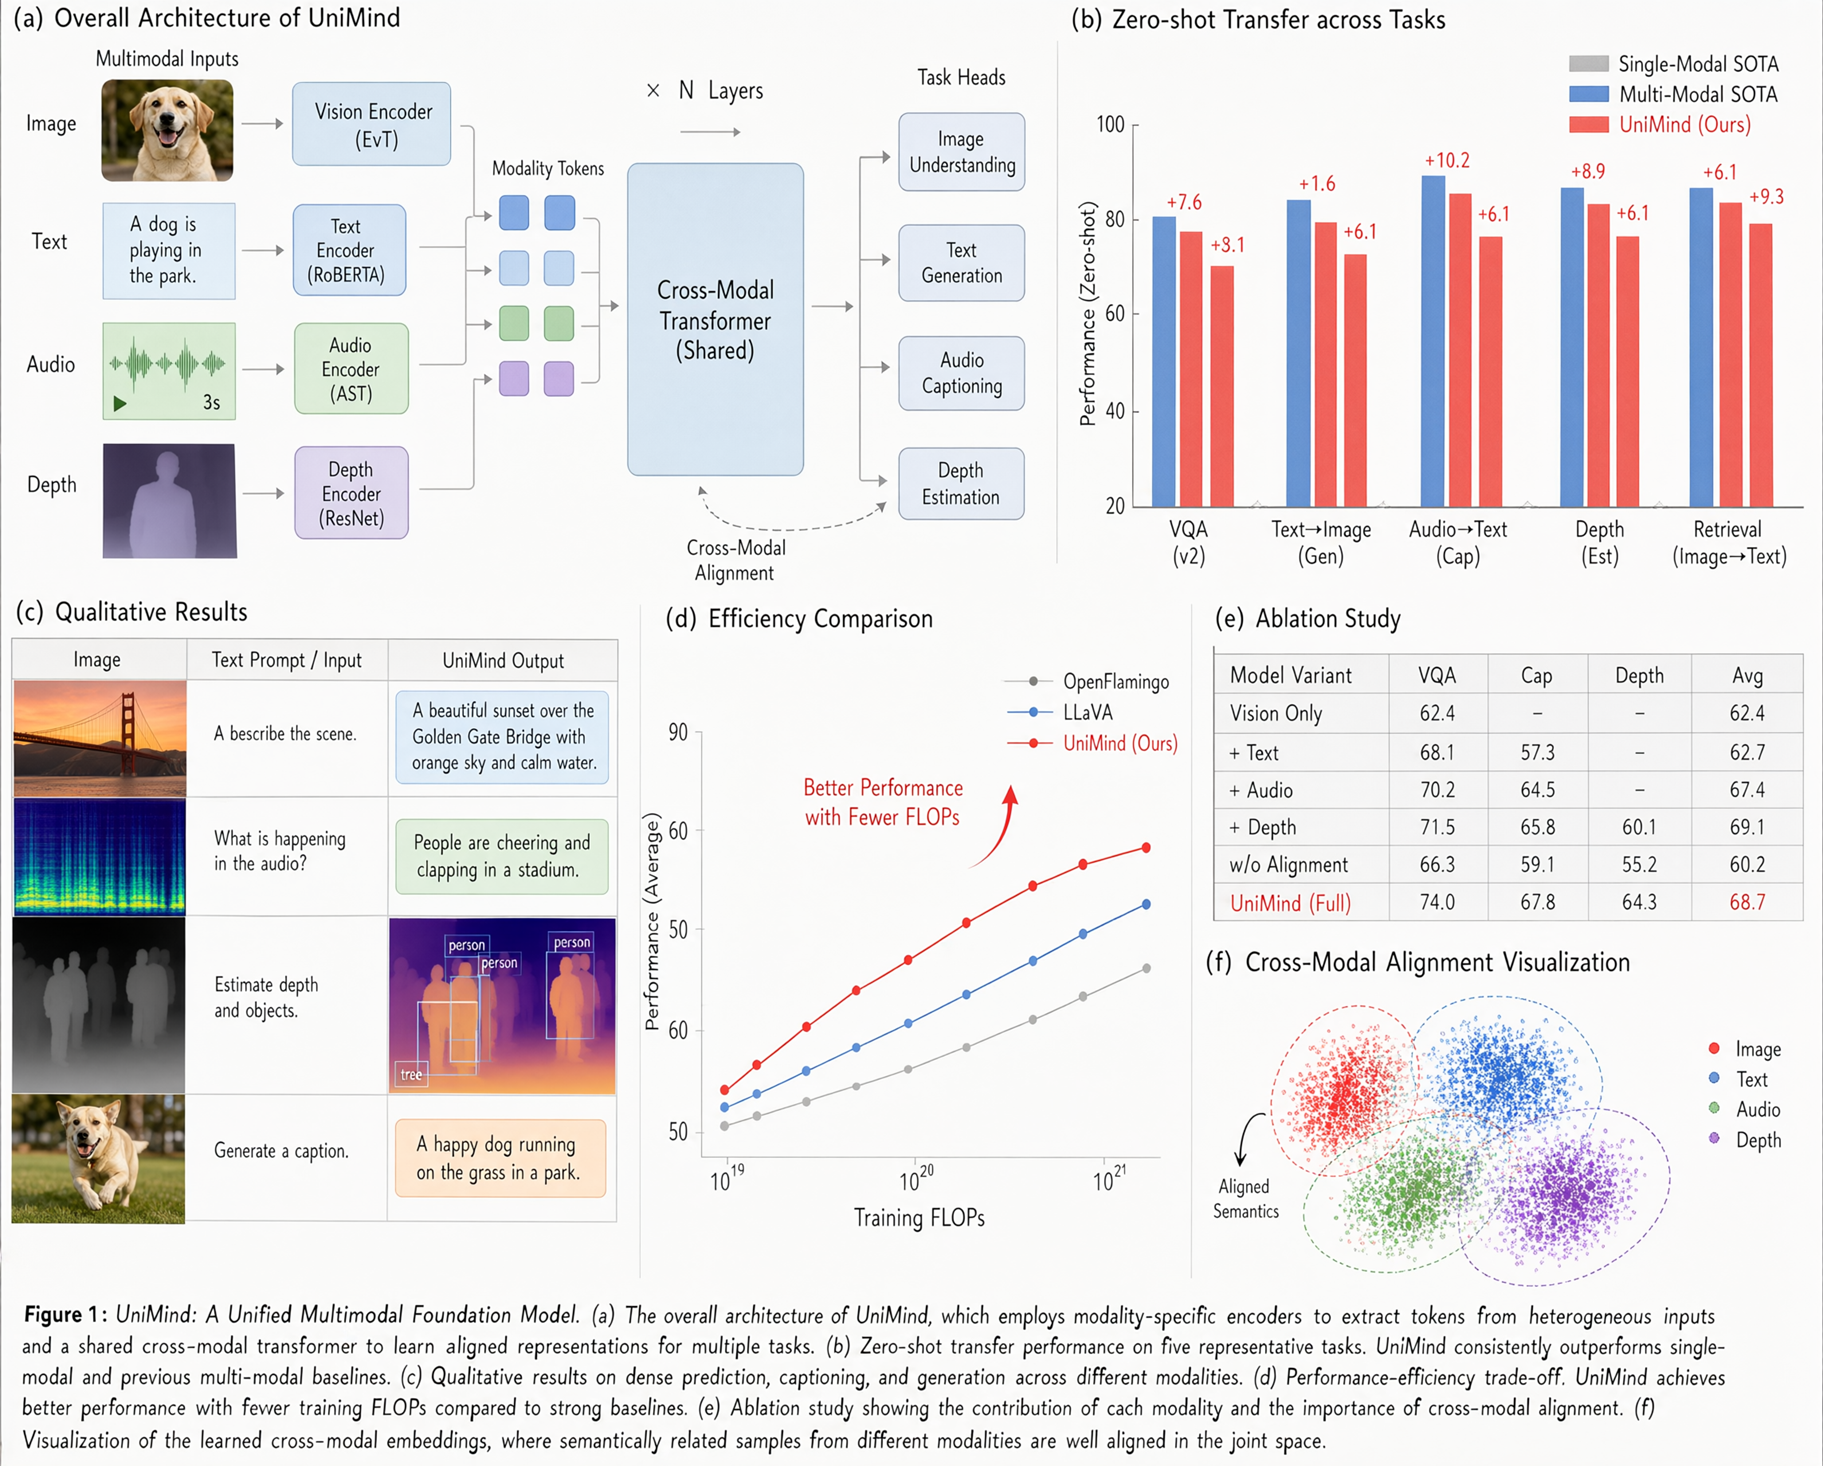
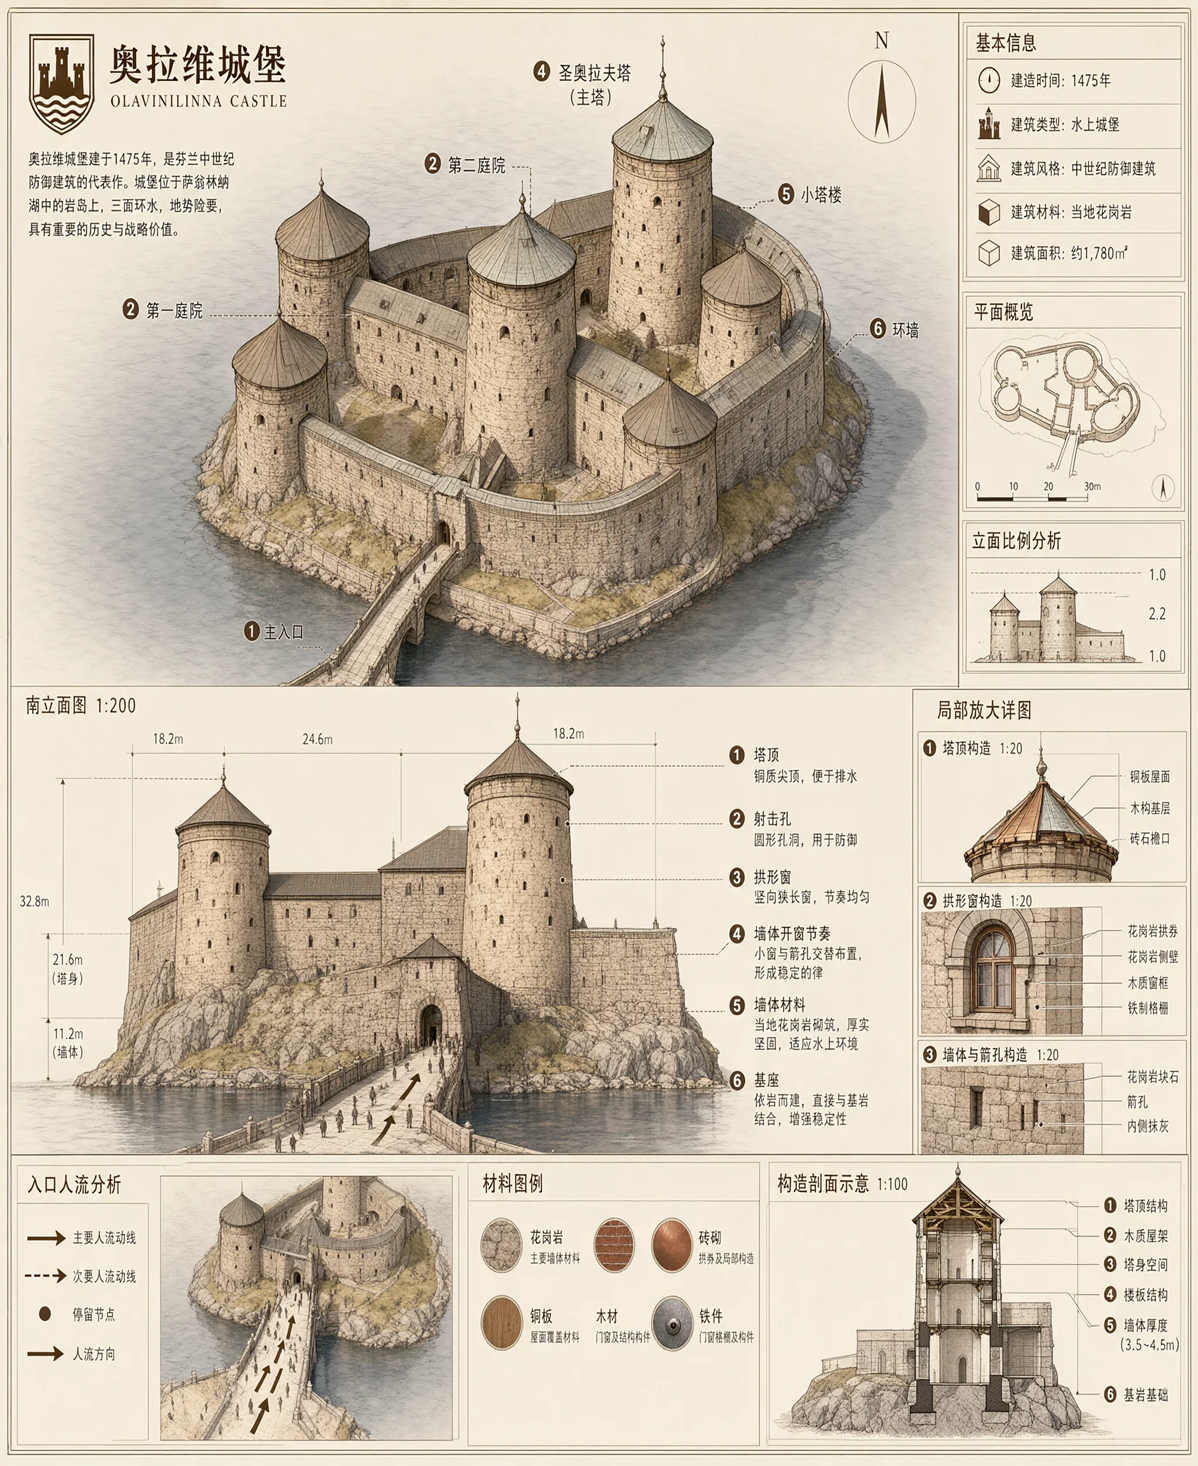
Text rendering
## License
This model is licensed under the [Qwen Research License Agreement](https://huggingface.co/Qwen/Qwen-Image-2.1/blob/main/LICENSE).