---
title: UnifoLM-VLA-Base
canonical_url: "https://www.modelscope.cn/models/unitreerobotics/UnifoLM-VLA-Base"
md_url: "https://www.modelscope.cn/models/unitreerobotics/UnifoLM-VLA-Base.md"
repository: unitreerobotics/UnifoLM-VLA-Base
last_updated: 2026-03-07
library_name:
  - pytorch
frameworks:
  - pytorch
downloads: 69
stars: 0
tags:
  - robotics
---

# UnifoLM-VLA-Base

> UnifoLM-VLA-Base - unitreerobotics 在 ModelScope 开源的模型。UnifoLM-VLA-0: A Vision-Language-Action (VLA) Framework under UnifoLM Family Project Page | Models | Datasets 🌎English | 🇨🇳中文

- **Repository**: unitreerobotics/UnifoLM-VLA-Base
- **Tags**: robotics
- **Downloads**: 69
- **Stars**: 0
- **Last updated**: 2026-03-07

Source: https://www.modelscope.cn/models/unitreerobotics/UnifoLM-VLA-Base

---

# UnifoLM-VLA-0: A Vision-Language-Action (VLA) Framework under UnifoLM Family
 <p style="font-size: 1.2em;">
    <a href="https://unigen-x.github.io/unifolm-vla.github.io"><strong>Project Page</strong></a> | 
    <a href="https://huggingface.co/unitreerobotics/models"><strong>Models</strong></a> |
    <a href="https://huggingface.co/unitreerobotics/datasets"><strong>Datasets</strong></a> 
  </p>
<div align="center">
  <p align="right">
    <span> 🌎English </span> | <a href="https://github.com/unitreerobotics/unifolm-vla/blob/main/README_cn.md"> 🇨🇳中文 </a>
  </p>
</div>


**UnifoLM-VLA-0** is a Vision–Language–Action (VLA) large model in the UnifoLM series, designed for general-purpose humanoid robot manipulation. It goes beyond the limitations of conventional Vision–Language Models (VLMs) in physical interaction. Through continued pre-training on robot manipulation data, the model evolves from "vision-language understanding" to an "embodied brain" equipped with physical common sense.

<table width="100%">
  <tr>
    <th width="50%">Spatial Semantic Enhancement</th>
    <th width="50%">Manipulation Generalization</th>
  </tr>
  <tr>
    <td valign="top">
      To address the requirements for instruction comprehension and spatial understanding in manipulation tasks, the model deeply integrates textual instructions with 2D/3D spatial details through continued pre-training, <strong>substantially strengthening its spatial perception and geometric understanding capabilities.</strong>
    </td>
    <td valign="top">
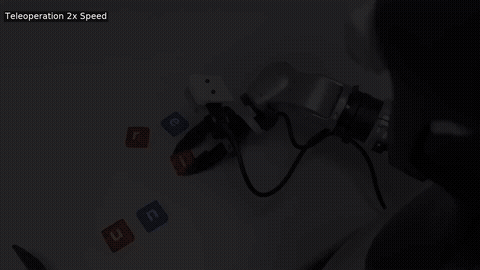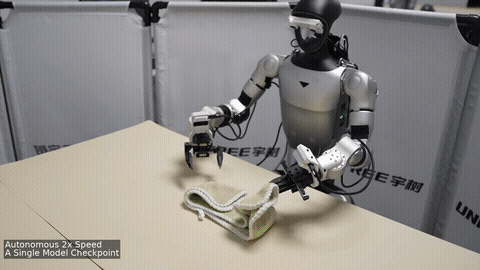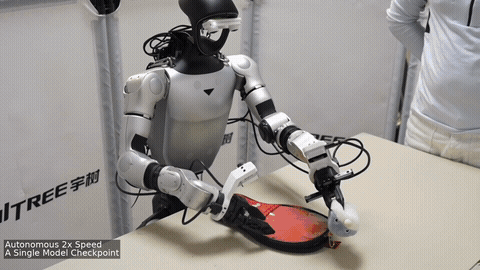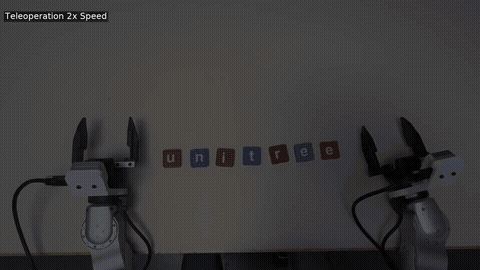
      By leveraging full dynamics prediction data, the model achieves strong generalization across diverse manipulation tasks. In real-robot validation, <strong>it can complete 12 categories of complex manipulation tasks with high quality using only a single policy.</strong>
    </td>
  </tr>
</table>


<div align="center">
  <img 
    src="https://raw.githubusercontent.com/unitreerobotics/unifolm-vla/main/assets/gif/UnifoLM-VLA-0.gif"
    style="width:100%; max-width:1000px; height:auto;"
    alt="UnifoLM-VLA Demo"
  />
</div>

## 📝 Citation
```
@misc{unifolm-vla-0,
  author       = {Unitree},
  title        = {UnifoLM-VLA-0: A Vision-Language-Action (VLA) Framework under UnifoLM Family},
  year         = {2026},
}
```

## License
The model is released under the CC BY-NC-SA 4.0 license as found in the [LICENSE](https://huggingface.co/unitreerobotics/UnifoLM-VLA-Base/blob/main/LICENSE). You are responsible for ensuring that your use of Unitree AI Models complies with all applicable laws.
