---
title: Qwen3-Coder-480B-A35B-Instruct-AWQ
canonical_url: "https://www.modelscope.cn/models/tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ"
md_url: "https://www.modelscope.cn/models/tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ.md"
repository: tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ
chinese_name: "通义千问3-Coder-480B-A35B-Instruct-AWQ"
last_updated: 2025-08-19
license: apache-2.0
pipeline_tag: text-generation
tasks:
- text-generation
model_type:
- qwen3_moe
architectures:
- Qwen3MoeForCausalLM
base_model:
- Qwen/Qwen3-Coder-480B-A35B-Instruct
base_model_relation: quantized
parameters: 65.9B
tensor_type:
- I32
- F16
library_name:
- transformer
- safetensors
- pytorch
frameworks:
- Pytorch
inference_backends:
- "deploy_task text/emb"
- "lmdeploy_turbomind 0.9.1"
- "sglang 0.5.2"
- "vllm 0.9.2"
downloads: 8211
stars: 3
tags:
- Qwen3
- AWQ
- "量化修复"
- vLLM
---
# Qwen3-Coder-480B-A35B-Instruct-AWQ
> Qwen3-Coder-480B-A35B-Instruct-AWQ - tclf90 在 ModelScope 开源的模型。通义千问3-Coder-480B-A35B-Instruct-AWQ 基础型 Qwen/Qwen3-Coder-480B-A35B-Instruct
tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ 是 ModelScope 魔搭社区上的 65.9B 参数text-generation模型,采用 apache-2.0 许可,基于 Qwen/Qwen3-Coder-480B-A35B-Instruct 构建,可用 deploy_task text/emb、lmdeploy_turbomind 0.9.1、sglang 0.5.2 部署。
- **Repository**: tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ
- **License**: apache-2.0
- **Tasks**: text-generation
- **Parameters**: 65.9B
- **Base model**: Qwen/Qwen3-Coder-480B-A35B-Instruct
- **Inference backends**: deploy_task text/emb, lmdeploy_turbomind 0.9.1, sglang 0.5.2, vllm 0.9.2
- **Tags**: Qwen3, AWQ, 量化修复, vLLM
- **Downloads**: 8211
- **Stars**: 3
- **Last updated**: 2025-08-19
Source: https://www.modelscope.cn/models/tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ
---
# 通义千问3-Coder-480B-A35B-Instruct-AWQ
基础型 [Qwen/Qwen3-Coder-480B-A35B-Instruct](https://www.modelscope.cn/models/Qwen/Qwen3-Coder-480B-A35B-Instruct)
### 【Vllm 单机8卡启动命令】
注: 8卡启动一定要跟`--enable-expert-parallel` 否则该模型专家张量TP整除除不尽;4卡则不需要。
```
CONTEXT_LENGTH=32768 # 262144
vllm serve \
tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ \
--served-model-name Qwen3-Coder-480B-A35B-Instruct-AWQ \
--enable-expert-parallel \
--swap-space 16 \
--max-num-seqs 512 \
--max-model-len $CONTEXT_LENGTH \
--max-seq-len-to-capture $CONTEXT_LENGTH \
--gpu-memory-utilization 0.9 \
--tensor-parallel-size 8 \
--trust-remote-code \
--disable-log-requests \
--host 0.0.0.0 \
--port 8000
```
### 【依赖】
```
vllm>=0.9.2
```
### 【模型更新日期】
```
2025-07-23
1. 首次commit
```
### 【模型列表】
| 文件大小 | 最近更新时间 |
|---------|--------------|
| `236GB` | `2025-07-23` |
### 【模型下载】
```python
from modelscope import snapshot_download
snapshot_download('tclf90/Qwen3-Coder-480B-A35B-Instruct-AWQ', cache_dir="本地路径")
```
### 【介绍】
# Qwen3-Coder-480B-A35B-Instruct
 ## Highlights
Today, we're announcing **Qwen3-Coder**, our most agentic code model to date. **Qwen3-Coder** is available in multiple sizes, but we're excited to introduce its most powerful variant first: **Qwen3-Coder-480B-A35B-Instruct**. featuring the following key enhancements:
- **Significant Performance** among open models on **Agentic Coding**, **Agentic Browser-Use**, and other foundational coding tasks, achieving results comparable to Claude Sonnet.
- **Long-context Capabilities** with native support for **256K** tokens, extendable up to **1M** tokens using Yarn, optimized for repository-scale understanding.
- **Agentic Coding** supporting for most platfrom such as **Qwen Code**, **CLINE**, featuring a specially designed function call format.
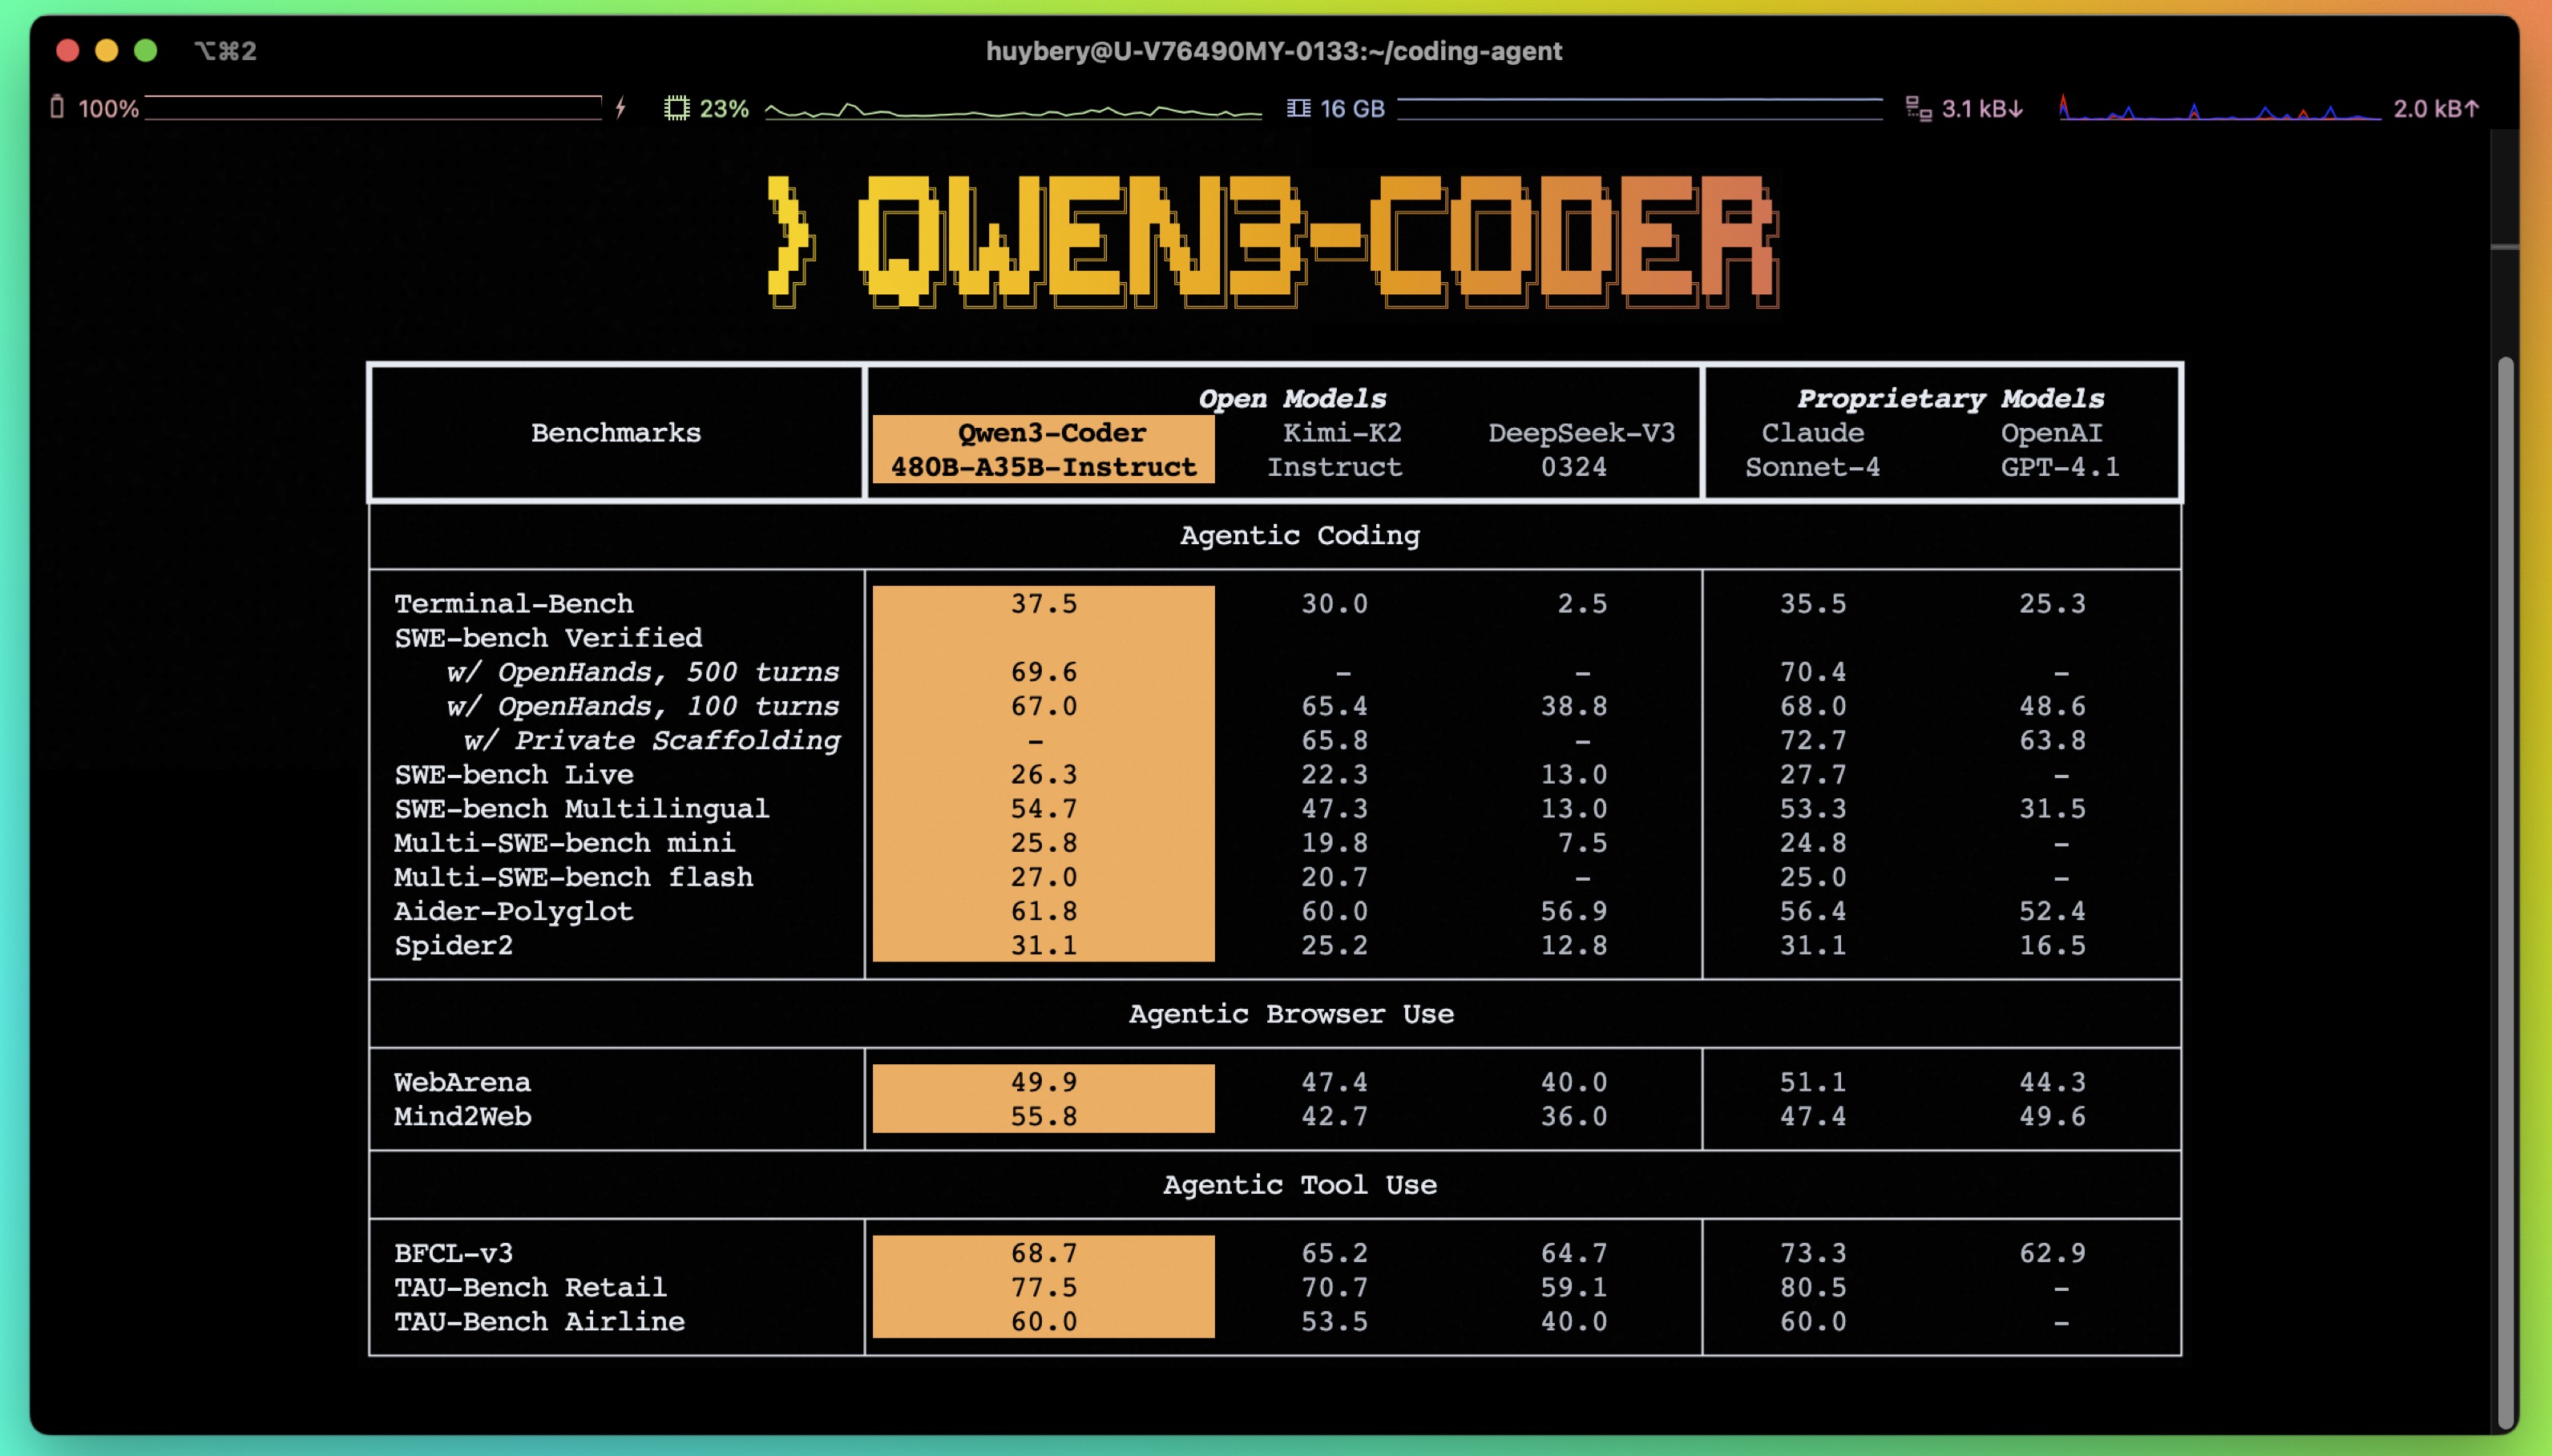
## Model Overview
**Qwen3-480B-A35B-Instruct** has the following features:
- Type: Causal Language Models
- Training Stage: Pretraining & Post-training
- Number of Parameters: 480B in total and 35B activated
- Number of Layers: 62
- Number of Attention Heads (GQA): 96 for Q and 8 for KV
- Number of Experts: 160
- Number of Activated Experts: 8
- Context Length: **262,144 natively**.
**NOTE: This model supports only non-thinking mode and does not generate ```` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3-coder/), [GitHub](https://github.com/QwenLM/Qwen3-Coder), and [Documentation](https://qwen.readthedocs.io/en/latest/).
## Quickstart
We advise you to use the latest version of `transformers`.
With `transformers<4.51.0`, you will encounter the following error:
```
KeyError: 'qwen3_moe'
```
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
model_name = "Qwen/Qwen3-480B-A35B-Instruct"
# load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
model_name,
torch_dtype="auto",
device_map="auto"
)
# prepare the model input
prompt = "Write a quick sort algorithm."
messages = [
{"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
messages,
tokenize=False,
add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
# conduct text completion
generated_ids = model.generate(
**model_inputs,
max_new_tokens=65536
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
content = tokenizer.decode(output_ids, skip_special_tokens=True)
print("content:", content)
```
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
## Agentic Coding
Qwen3-Coder excels in tool calling capabilities.
You can simply define or use any tools as following example.
```python
# Your tool implementation
def square_the_number(num: float) -> dict:
return num ** 2
# Define Tools
tools=[
{
"type":"function",
"function":{
"name": "square_the_number",
"description": "output the square of the number.",
"parameters": {
"type": "object",
"required": ["input_num"],
"properties": {
'input_num': {
'type': 'number',
'description': 'input_num is a number that will be squared'
}
},
}
}
}
]
import OpenAI
# Define LLM
client = OpenAI(
# Use a custom endpoint compatible with OpenAI API
base_url='http://localhost:8000/v1', # api_base
api_key="EMPTY"
)
messages = [{'role': 'user', 'content': 'square the number 1024'}]
completion = client.chat.completions.create(
messages=messages,
model="Qwen3-480B-A35B-Instruct",
max_tokens=65536,
tools=tools,
)
print(completion.choice[0])
```
## Best Practices
To achieve optimal performance, we recommend the following settings:
1. **Sampling Parameters**:
- We suggest using `temperature=0.7`, `top_p=0.8`, `top_k=20`, `repetition_penalty=1.05`.
2. **Adequate Output Length**: We recommend using an output length of 65,536 tokens for most queries, which is adequate for instruct models.
### Citation
If you find our work helpful, feel free to give us a cite.
```
@misc{qwen3technicalreport,
title={Qwen3 Technical Report},
author={Qwen Team},
year={2025},
eprint={2505.09388},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2505.09388},
}
```