---
title: GLM-4.6-AWQ
canonical_url: "https://www.modelscope.cn/models/tclf90/GLM-4.6-AWQ"
md_url: "https://www.modelscope.cn/models/tclf90/GLM-4.6-AWQ.md"
repository: tclf90/GLM-4.6-AWQ
last_updated: 2025-10-03
license: mit
pipeline_tag: text-generation
tasks:
- text-generation
model_type:
- glm4_moe
architectures:
- Glm4MoeForCausalLM
base_model:
- ZhipuAI/GLM-4.6
base_model_relation: quantized
parameters: 50.4B
tensor_type:
- F32
- F16
- I32
library_name:
- safetensors
- pytorch
frameworks:
- Pytorch
inference_backends:
- "deploy_task text"
- "sglang 0.5.2"
downloads: 121801
stars: 3
tags:
- AWQ
- vLLM
---
# GLM-4.6-AWQ
> GLM-4.6-AWQ - tclf90 在 ModelScope 开源的模型。GLM-4.6-AWQ Base Model: ZhipuAI/GLM-4.6
tclf90/GLM-4.6-AWQ 是 ModelScope 魔搭社区上的 50.4B 参数text-generation模型,采用 mit 许可,基于 ZhipuAI/GLM-4.6 构建,可用 deploy_task text、sglang 0.5.2 部署。
- **Repository**: tclf90/GLM-4.6-AWQ
- **License**: mit
- **Tasks**: text-generation
- **Parameters**: 50.4B
- **Base model**: ZhipuAI/GLM-4.6
- **Inference backends**: deploy_task text, sglang 0.5.2
- **Tags**: AWQ, vLLM
- **Downloads**: 121801
- **Stars**: 3
- **Last updated**: 2025-10-03
Source: https://www.modelscope.cn/models/tclf90/GLM-4.6-AWQ
---
# GLM-4.6-AWQ
Base Model: [ZhipuAI/GLM-4.6](https://www.modelscope.cn/models/ZhipuAI/GLM-4.6)
### 【Dependencies / Installation】
As of **2025-10-01**, create a fresh Python environment and run:
```bash
pip install -U pip
pip install vllm==0.10.2
```
### 【vLLM Startup Command】
Note: When launching with TP=8, include `--enable-expert-parallel`;
otherwise the expert tensors couldn’t be evenly sharded across GPU devices.
```
CONTEXT_LENGTH=32768
vllm serve \
tclf90/GLM-4.6-AWQ \
--served-model-name My_Model \
--enable-auto-tool-choice \
--tool-call-parser glm45 \
--reasoning-parser glm45 \
--swap-space 16 \
--max-num-seqs 64 \
--max-model-len $CONTEXT_LENGTH \
--gpu-memory-utilization 0.9 \
--tensor-parallel-size 8 \
--enable-expert-parallel \
--trust-remote-code \
--disable-log-requests \
--host 0.0.0.0 \
--port 8000
```
### 【Logs】
```
2025-10-01
1. Initial commit
```
### 【Model Files】
| File Size | Last Updated |
|-----------|--------------|
| `184GB` | `2025-10-01` |
### 【Model Download】
```python
from modelscope import snapshot_download
snapshot_download('tclf90/GLM-4.6-AWQ', cache_dir="your_local_path")
```
### 【Overview】
# GLM-4.6
👋 Join our Discord community.
📖 Check out the GLM-4.6 technical blog, technical report(GLM-4.5), and Zhipu AI technical documentation.
📍 Use GLM-4.6 API services on Z.ai API Platform.
👉 One click to GLM-4.6.
## Model Introduction
Compared with GLM-4.5, **GLM-4.6** brings several key improvements:
* **Longer context window:** The context window has been expanded from 128K to 200K tokens, enabling the model to handle more complex agentic tasks.
* **Superior coding performance:** The model achieves higher scores on code benchmarks and demonstrates better real-world performance in applications such as Claude Code、Cline、Roo Code and Kilo Code, including improvements in generating visually polished front-end pages.
* **Advanced reasoning:** GLM-4.6 shows a clear improvement in reasoning performance and supports tool use during inference, leading to stronger overall capability.
* **More capable agents:** GLM-4.6 exhibits stronger performance in tool using and search-based agents, and integrates more effectively within agent frameworks.
* **Refined writing:** Better aligns with human preferences in style and readability, and performs more naturally in role-playing scenarios.
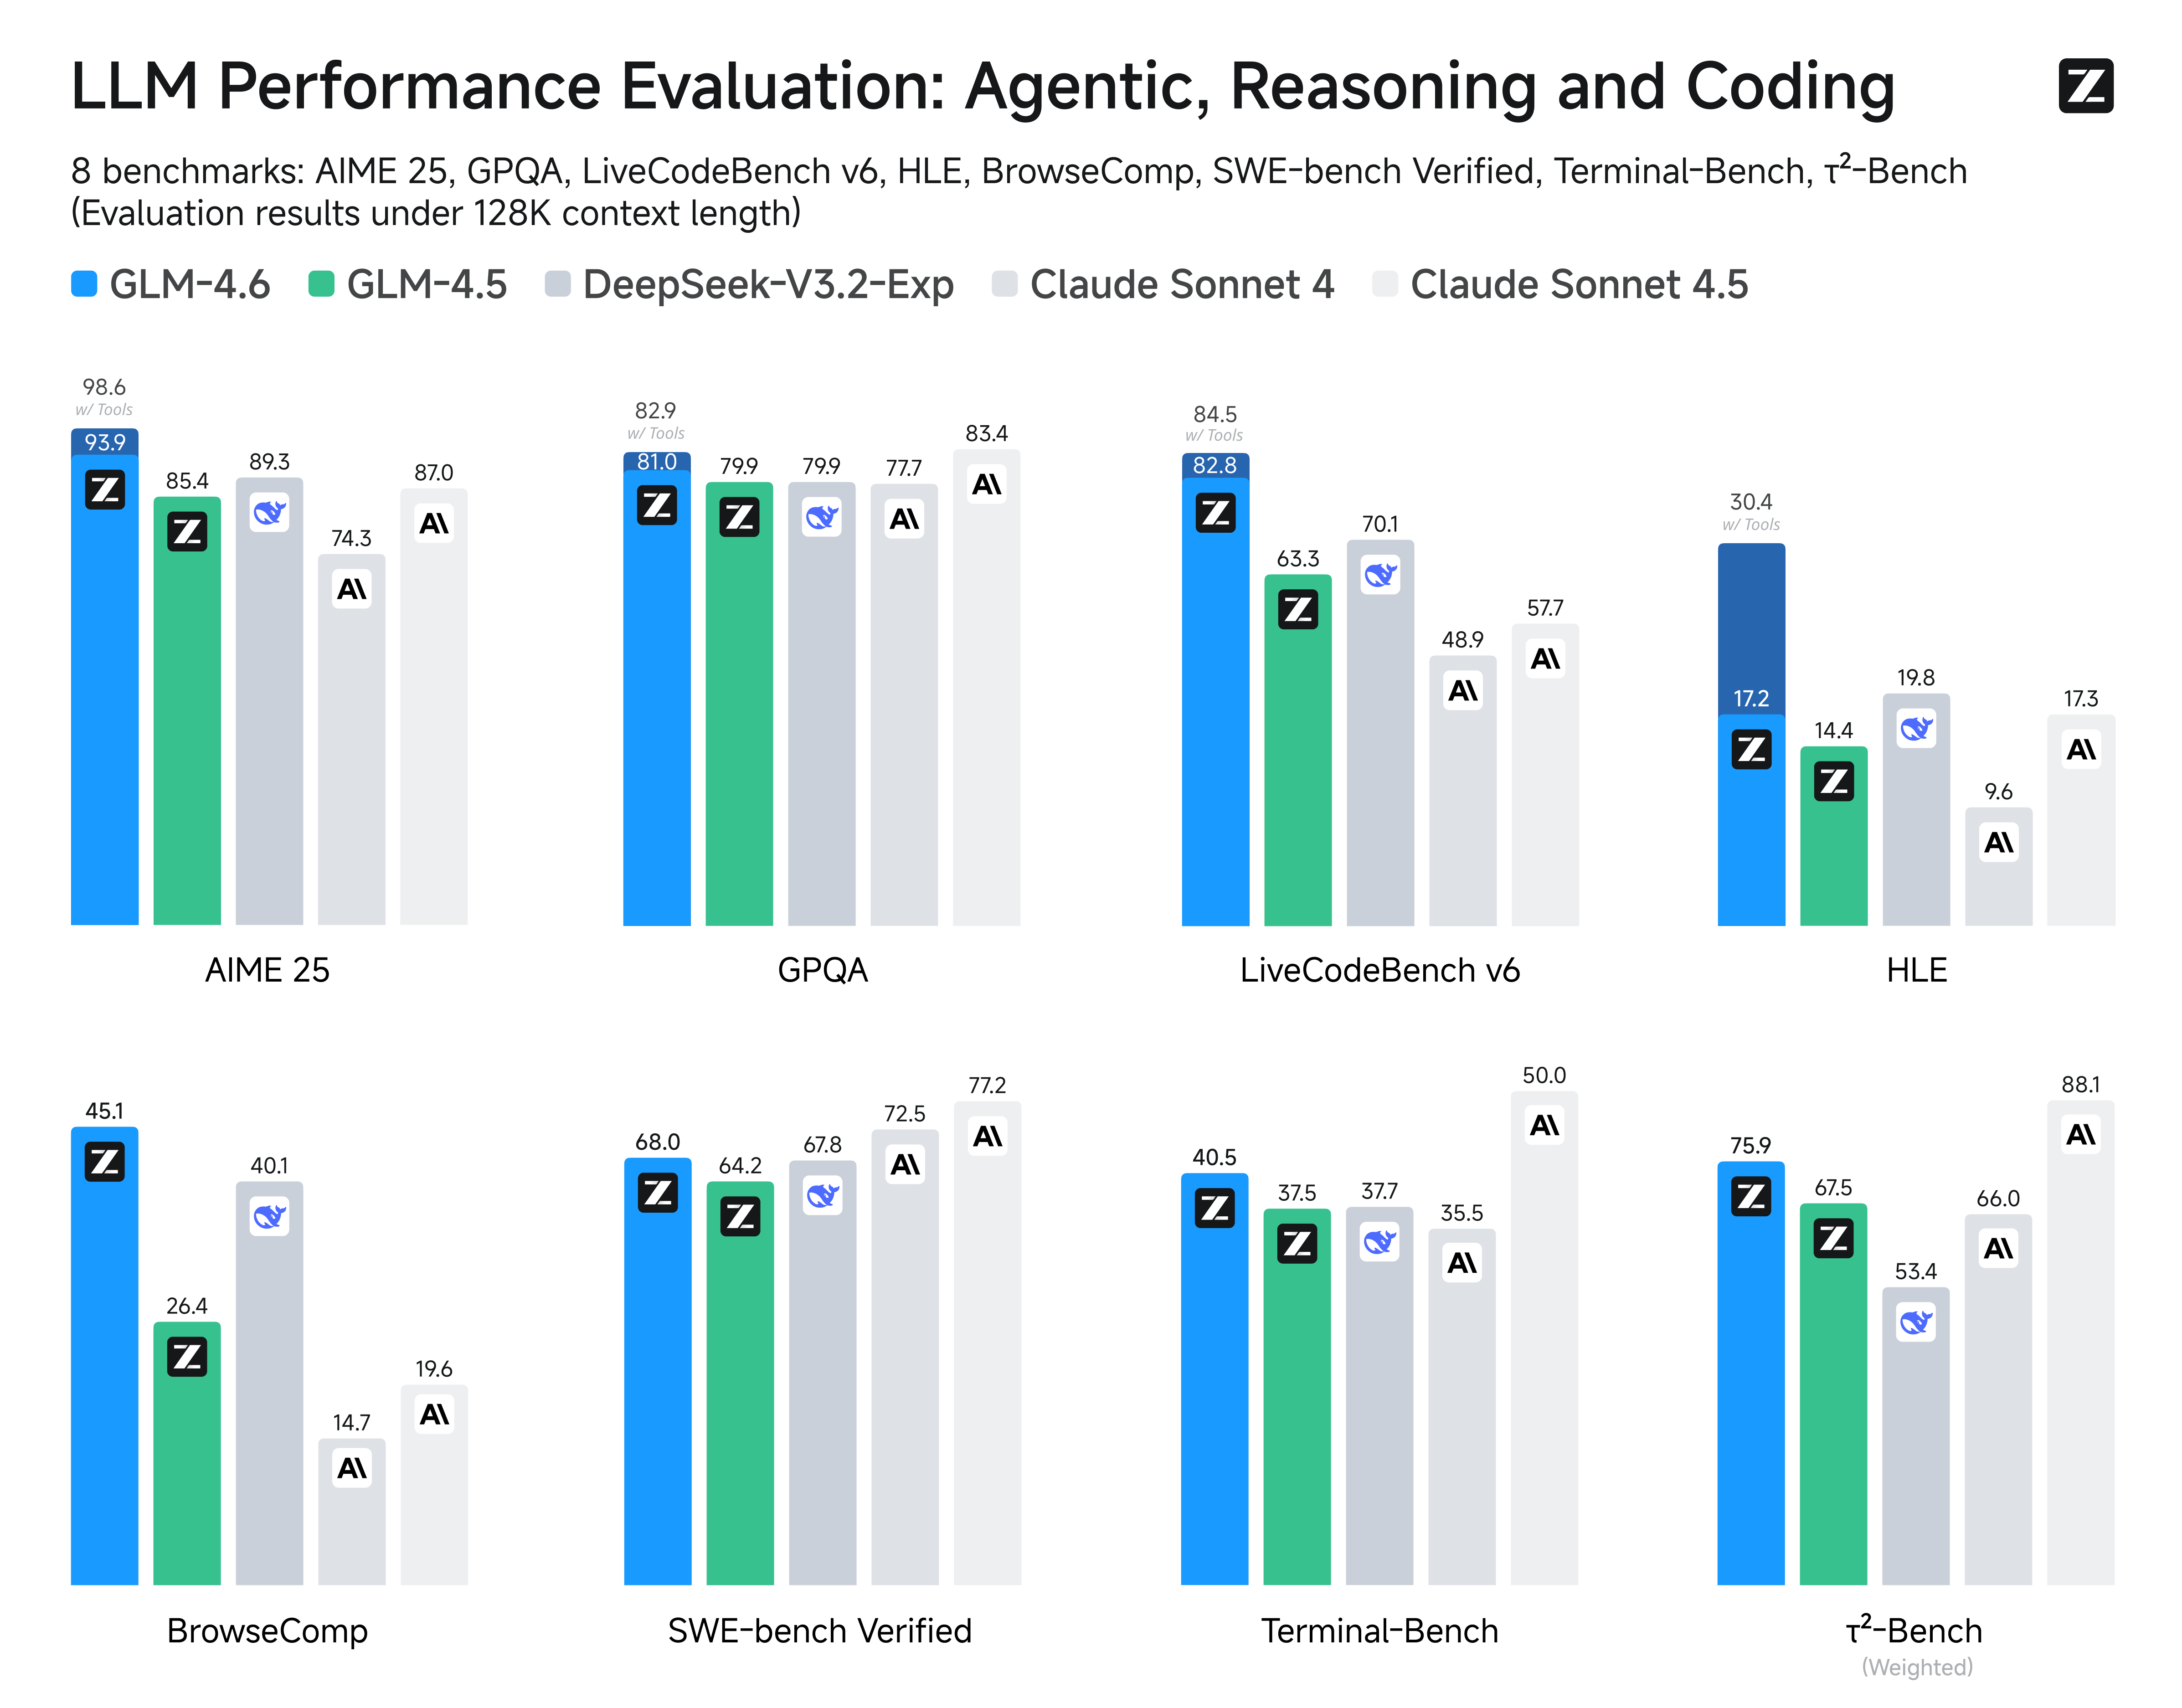
We evaluated GLM-4.6 across eight public benchmarks covering agents, reasoning, and coding. Results show clear gains over GLM-4.5, with GLM-4.6 also holding competitive advantages over leading domestic and international models such as **DeepSeek-V3.1-Terminus** and **Claude Sonnet 4**.
## Inference
**Both GLM-4.5 and GLM-4.6 use the same inference method.**
you can check our [github](https://github.com/zai-org/GLM-4.5) for more detail.
## Recommended Evaluation Parameters
For general evaluations, we recommend using a **sampling temperature of 1.0**.
For **code-related evaluation tasks** (such as LCB), it is further recommended to set:
- `top_p = 0.95`
- `top_k = 40`
## Evaluation
- For tool-integrated reasoning, please refer to [this doc](https://github.com/zai-org/GLM-4.5/blob/main/resources/glm_4.6_tir_guide.md).
- For search benchmark, we design a specific format for searching toolcall in thinking mode to support search agent, please refer to [this](https://github.com/zai-org/GLM-4.5/blob/main/resources/trajectory_search.json). for the detailed template.
