---
title: Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16
canonical_url: "https://www.modelscope.cn/models/okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16"
md_url: "https://www.modelscope.cn/models/okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16.md"
repository: okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16
chinese_name: "通义千问 Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16 量化高精校准"
last_updated: 2025-08-07
license: apache-2.0
pipeline_tag: text-generation
tasks:
- text-generation
model_type:
- qwen3_moe
architectures:
- Qwen3MoeForCausalLM
base_model:
- Qwen/Qwen3-Coder-30B-A3B-Instruct
base_model_relation: quantized
parameters: 8.1B
tensor_type:
- BF16
- I64
- I32
library_name:
- transformer
- safetensors
- pytorch
frameworks:
- Pytorch
language:
- en
- zh
inference_backends:
- "deploy_task text/emb"
- "lmdeploy_turbomind 0.9.1"
- "sglang 0.5.2"
- "vllm 0.9.2"
downloads: 1138
stars: 5
tags:
- Thinking
- Chat
- "Reason Model"
- Quantization
---
# Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16
> Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16 - okwinds 在 ModelScope 开源的模型。重要:友情提醒,推理本模型时,请按照如下官方最佳实践:
okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16 是 ModelScope 魔搭社区上的 8.1B 参数text-generation模型,采用 apache-2.0 许可,基于 Qwen/Qwen3-Coder-30B-A3B-Instruct 构建,可用 deploy_task text/emb、lmdeploy_turbomind 0.9.1、sglang 0.5.2 部署。
- **Repository**: okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16
- **License**: apache-2.0
- **Tasks**: text-generation
- **Parameters**: 8.1B
- **Base model**: Qwen/Qwen3-Coder-30B-A3B-Instruct
- **Inference backends**: deploy_task text/emb, lmdeploy_turbomind 0.9.1, sglang 0.5.2, vllm 0.9.2
- **Tags**: Thinking, Chat, Reason Model, Quantization
- **Downloads**: 1138
- **Stars**: 5
- **Last updated**: 2025-08-07
Source: https://www.modelscope.cn/models/okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16
---
### 重要:友情提醒,推理本模型时,请按照如下官方最佳实践:
为了达到最佳性能,建议以下设置:
1. **采样参数**:
- 建议使用 `Temperature=0.7`, `TopP=0.8`, `TopK=20`, 以及 `presence_penalty=1.05`.
2. **足够的输出长度**: 对于大多数查询,建议使用 65,536 个 tokens 的输出长度,这对于指令模型是足够的。
#### 📖 关于量化损失方面的研究,可阅读公众号“觉察流”文章👇
《[Reason Model 的“瘦身计划”:量化技术的得与失](https://mp.weixin.qq.com/s/NMGq4UUkfo8GMix5LHnWCg)》
# 通义千问 Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16 量化高精校准
原模型 [Qwen/Qwen3-Coder-30B-A3B-Instruct](https://www.modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct)
---
#### _作者在此 👇🏻 扫一扫_
 ---
## 下载
SDK下载
```bash
#安装ModelScope
pip install modelscope
```
```python
#SDK模型下载
from modelscope import snapshot_download
model_dir = snapshot_download('okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16')
```
Git下载
```
#Git模型下载
git clone https://www.modelscope.cn/okwinds/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16.git
```
## 模型概述
Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16 是一个基于 通义千问 Qwen3-Coder-30B-A3B-Instruct 的 INT8 量化并校准的模型。
- **模型名称:** Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16
- **模型架构:** Qwen3 MoE
- **权重量化:** INT8
该模型通过将 [qwen/Qwen3-Coder-30B-A3B-Instruct](https://www.modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct) 的权重量化为 INT8 数据类型而实现。
量化过程将每个参数从 16bit 减少到 8bit,将模型占用磁盘空间大小,以及推理时加载模型需要的GPU显存空间,减少到了大约为原模型的1/2。
量化过程中,只有 transformer 中的 Linear 层权重是量化的,其他层均保持为原模型数据类型,采用混合精度的计算方式,尽可能减少模型量化后所带来的精度损失。
在量化过程中,使用了[AutoGPTQ](https://github.com/AutoGPTQ/AutoGPTQ),采用 Symmetric group-wise 方式量化。并在此次量化过程中,进行了数据校准,以提升模型生成精度。(相对比 BF16 做到几乎无损)
> 注意:本模型需要 compute capability > 8.0(Ampere、Ada Lovelace、Hopper 架构)的 Nvidia GPU 来支持 INT8 **混合精度**计算。
## 部署推理
#### 推荐使用 vLLM>=0.8.4 ( transformers>=4.51.0 )
Openai api 兼容模式
```bash
>>> vllm serve "/home/gavin/llm/Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16" --host 0.0.0.0 --port 8000 --gpu-memory-utilization 0.9 --served-model-name "Qwen3-Coder-30B-A3B-Instruct-Int8-W8A16"
```
# 附录 Qwen3-Coder-30B-A3B-Instruct 介绍
 ## Highlights
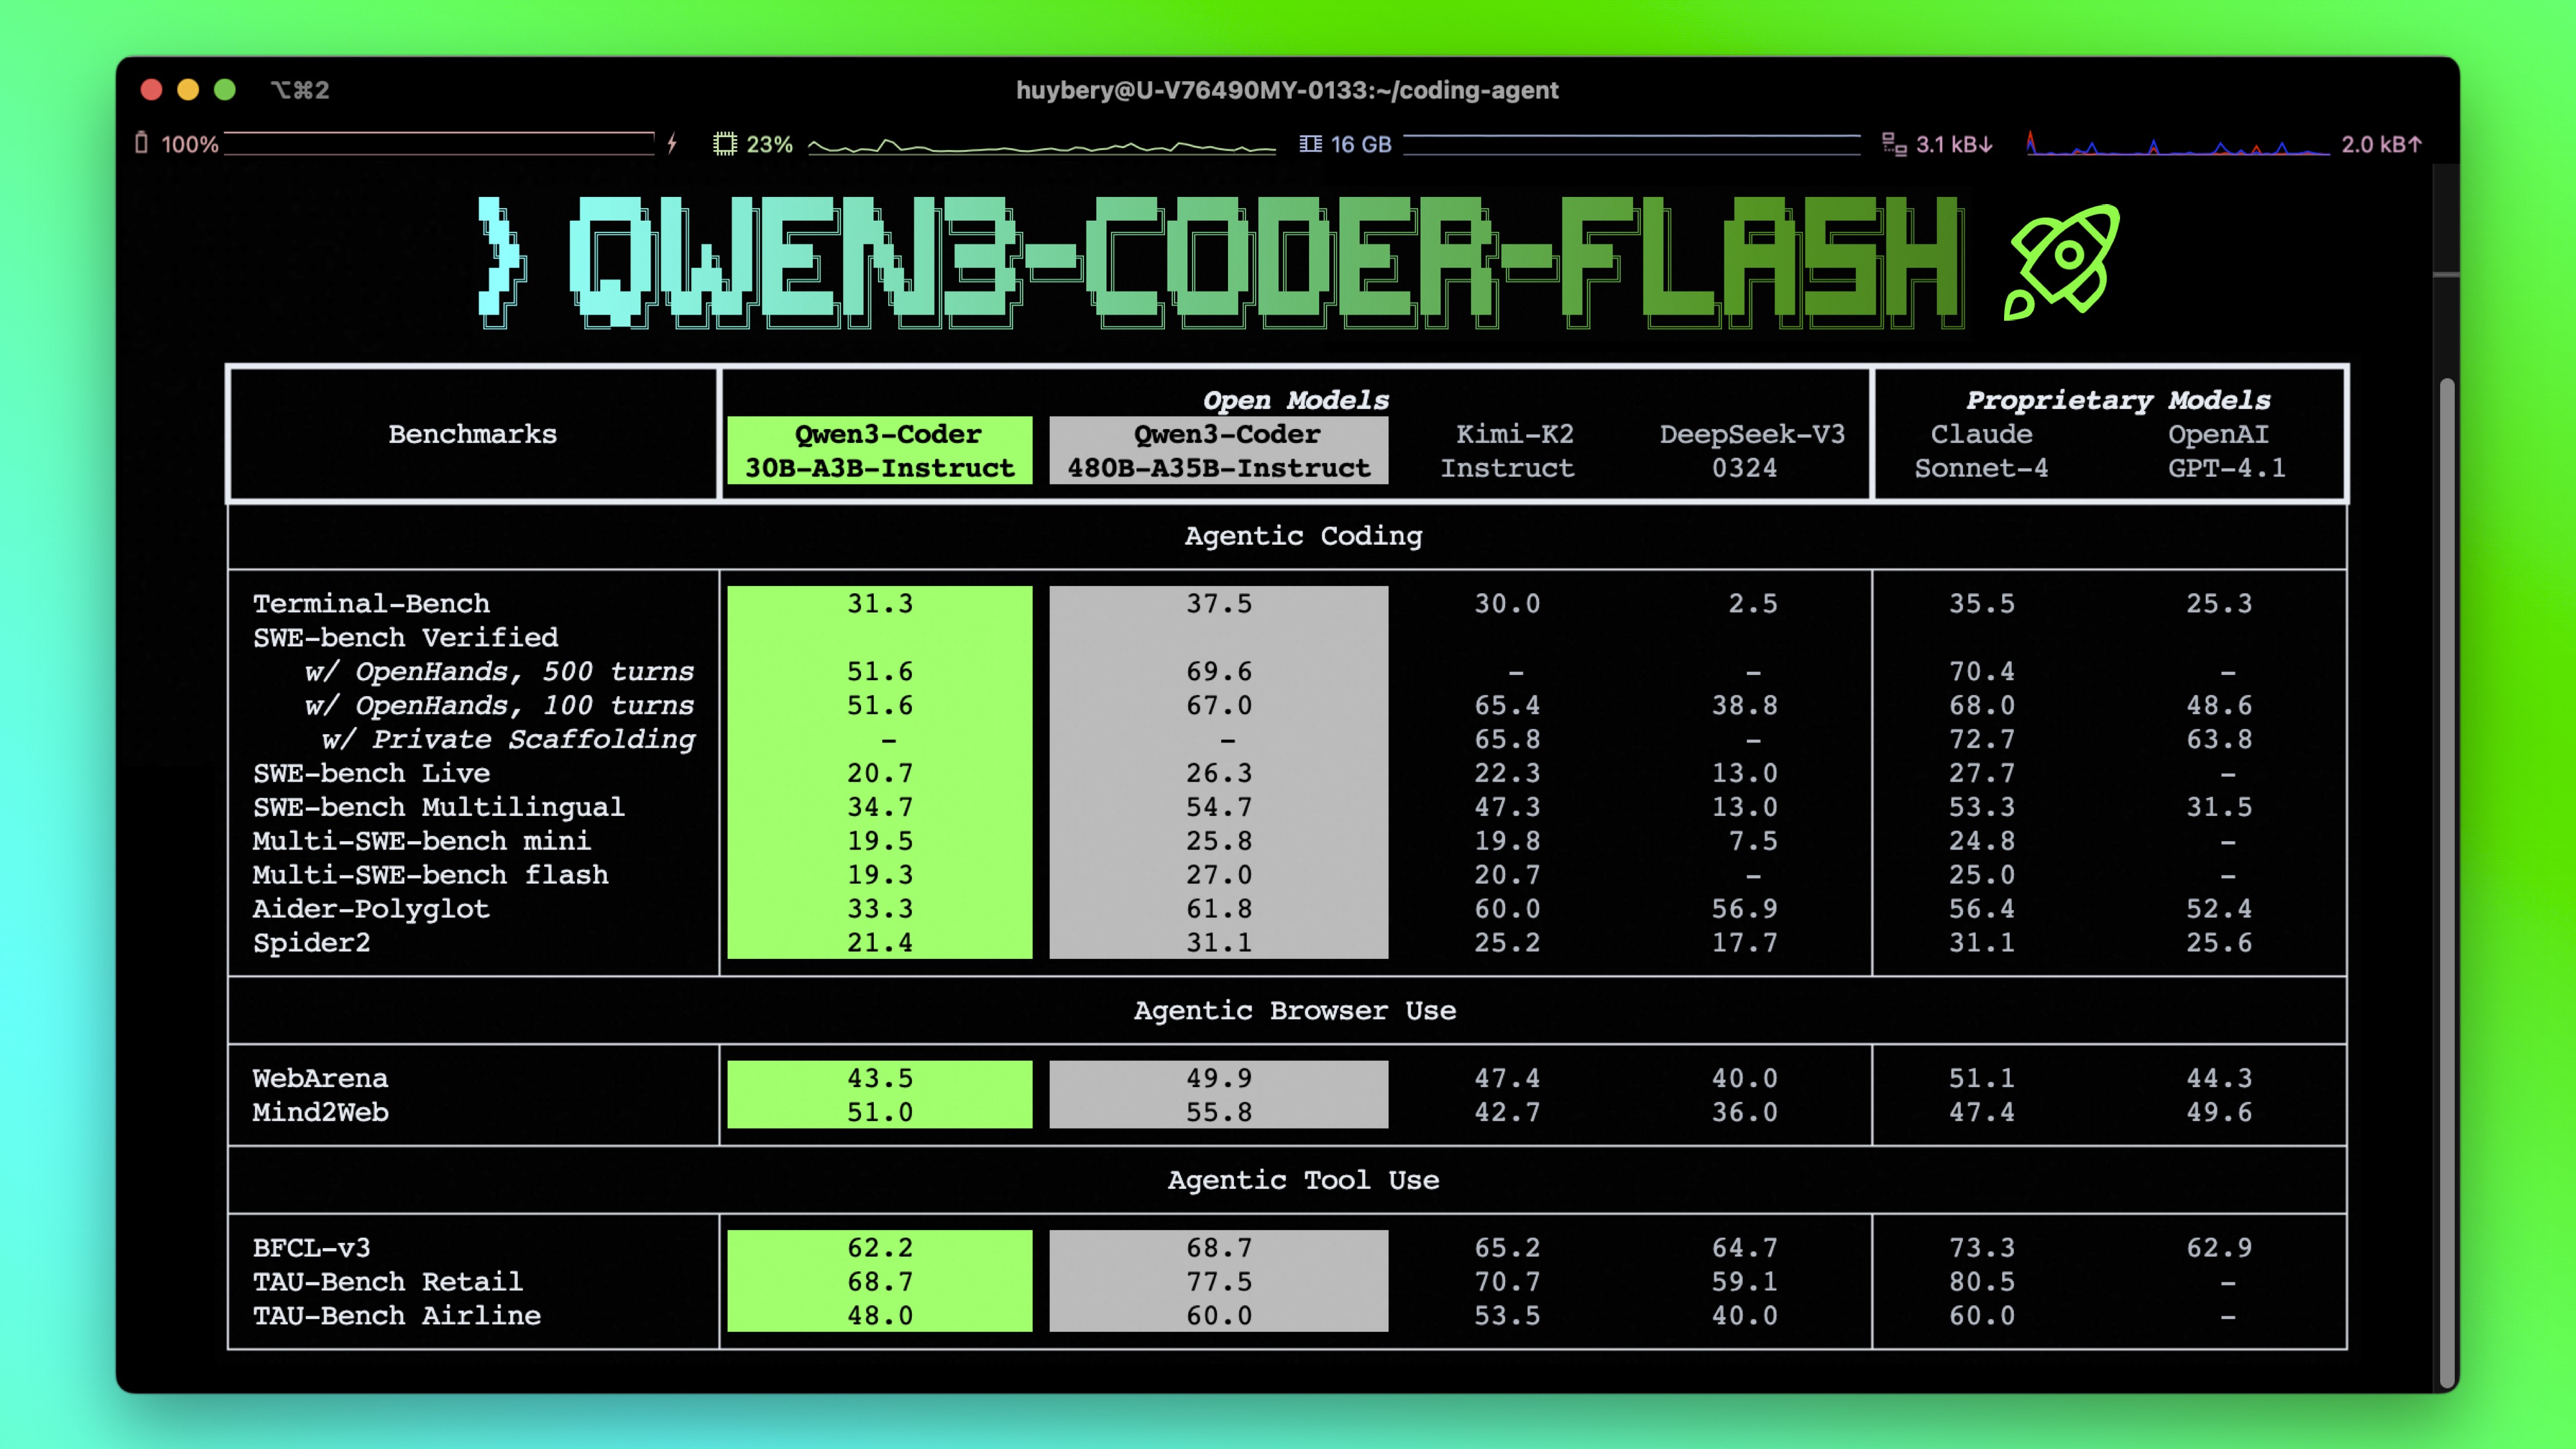
**Qwen3-Coder** is available in multiple sizes. Today, we're excited to introduce **Qwen3-Coder-30B-A3B-Instruct**. This streamlined model maintains impressive performance and efficiency, featuring the following key enhancements:
- **Significant Performance** among open models on **Agentic Coding**, **Agentic Browser-Use**, and other foundational coding tasks.
- **Long-context Capabilities** with native support for **256K** tokens, extendable up to **1M** tokens using Yarn, optimized for repository-scale understanding.
- **Agentic Coding** supporting for most platform such as **Qwen Code**, **CLINE**, featuring a specially designed function call format.
## Model Overview
**Qwen3-Coder-30B-A3B-Instruct** has the following features:
- Type: Causal Language Models
- Training Stage: Pretraining & Post-training
- Number of Parameters: 30.5B in total and 3.3B activated
- Number of Layers: 48
- Number of Attention Heads (GQA): 32 for Q and 4 for KV
- Number of Experts: 128
- Number of Activated Experts: 8
- Context Length: **262,144 natively**.
**NOTE: This model supports only non-thinking mode and does not generate ```` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3-coder/), [GitHub](https://github.com/QwenLM/Qwen3-Coder), and [Documentation](https://qwen.readthedocs.io/en/latest/).
## Quickstart
We advise you to use the latest version of `transformers`.
With `transformers<4.51.0`, you will encounter the following error:
```
KeyError: 'qwen3_moe'
```
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
model_name = "Qwen/Qwen3-Coder-30B-A3B-Instruct"
# load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
model_name,
torch_dtype="auto",
device_map="auto"
)
# prepare the model input
prompt = "Write a quick sort algorithm."
messages = [
{"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
messages,
tokenize=False,
add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
# conduct text completion
generated_ids = model.generate(
**model_inputs,
max_new_tokens=65536
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
content = tokenizer.decode(output_ids, skip_special_tokens=True)
print("content:", content)
```
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
For local use, applications such as Ollama, LMStudio, MLX-LM, llama.cpp, and KTransformers have also supported Qwen3.
## Agentic Coding
Qwen3-Coder excels in tool calling capabilities.
You can simply define or use any tools as following example.
```python
# Your tool implementation
def square_the_number(num: float) -> dict:
return num ** 2
# Define Tools
tools=[
{
"type":"function",
"function":{
"name": "square_the_number",
"description": "output the square of the number.",
"parameters": {
"type": "object",
"required": ["input_num"],
"properties": {
'input_num': {
'type': 'number',
'description': 'input_num is a number that will be squared'
}
},
}
}
}
]
import OpenAI
# Define LLM
client = OpenAI(
# Use a custom endpoint compatible with OpenAI API
base_url='http://localhost:8000/v1', # api_base
api_key="EMPTY"
)
messages = [{'role': 'user', 'content': 'square the number 1024'}]
completion = client.chat.completions.create(
messages=messages,
model="Qwen3-Coder-30B-A3B-Instruct",
max_tokens=65536,
tools=tools,
)
print(completion.choice[0])
```
## Best Practices
To achieve optimal performance, we recommend the following settings:
1. **Sampling Parameters**:
- We suggest using `temperature=0.7`, `top_p=0.8`, `top_k=20`, `repetition_penalty=1.05`.
2. **Adequate Output Length**: We recommend using an output length of 65,536 tokens for most queries, which is adequate for instruct models.
### Citation
If you find our work helpful, feel free to give us a cite.
```
@misc{qwen3technicalreport,
title={Qwen3 Technical Report},
author={Qwen Team},
year={2025},
eprint={2505.09388},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2505.09388},
}
```