---
title: QwQ-32B-FP8
canonical_url: "https://www.modelscope.cn/models/okwinds/QwQ-32B-FP8"
md_url: "https://www.modelscope.cn/models/okwinds/QwQ-32B-FP8.md"
repository: okwinds/QwQ-32B-FP8
last_updated: 2025-04-17
license: apache-2.0
pipeline_tag: text-generation
tasks:
- text-generation
model_type:
- qwen2
architectures:
- Qwen2ForCausalLM
base_model:
- Qwen/QwQ-32B
base_model_relation: quantized
parameters: 32.8B
tensor_type:
- BF16
- F8_E4M3
- F32
library_name:
- safetensors
- pytorch
frameworks:
- Pytorch
language:
- en
- zh
inference_backends:
- "deploy_task text/emb"
- "lmdeploy 0.9.1"
- "lmdeploy_turbomind 0.9.1"
- "sglang 0.5.2"
- "vllm 0.9.2"
downloads: 717
stars: 2
tags:
- Instruct
- Chat
- "Reason Model"
- Quantization
---
# QwQ-32B-FP8
> QwQ-32B-FP8 - okwinds 在 ModelScope 开源的模型。正式版 QwQ-32B 的量化版本已出,用了更优质的数据做校准。欢迎品尝:QwQ-32B-Int8-W8A16
okwinds/QwQ-32B-FP8 是 ModelScope 魔搭社区上的 32.8B 参数text-generation模型,采用 apache-2.0 许可,基于 Qwen/QwQ-32B 构建,可用 deploy_task text/emb、lmdeploy 0.9.1、lmdeploy_turbomind 0.9.1 部署。
- **Repository**: okwinds/QwQ-32B-FP8
- **License**: apache-2.0
- **Tasks**: text-generation
- **Parameters**: 32.8B
- **Base model**: Qwen/QwQ-32B
- **Inference backends**: deploy_task text/emb, lmdeploy 0.9.1, lmdeploy_turbomind 0.9.1, sglang 0.5.2, vllm 0.9.2
- **Tags**: Instruct, Chat, Reason Model, Quantization
- **Downloads**: 717
- **Stars**: 2
- **Last updated**: 2025-04-17
Source: https://www.modelscope.cn/models/okwinds/QwQ-32B-FP8
---
正式版 QwQ-32B 的量化版本已出,用了更优质的数据做校准。欢迎品尝:[QwQ-32B-Int8-W8A16](https://www.modelscope.cn/models/okwinds/QwQ-32B-Int8-W8A16)
友情提醒,推理本模型时,请按照如下官方指引:
> 注意:建议在运行这些模型时设置适当的温度(0.5 到 0.7 之间),否则您可能会遇到无休止的重复或不连贯的输出问题。
📖 关于量化损失方面的研究,可阅读公众号“觉察流”文章👇
《[Reason Model 的“瘦身计划”:量化技术的得与失](https://mp.weixin.qq.com/s/NMGq4UUkfo8GMix5LHnWCg)》
# 通义千问 QwQ-32B-FP8
原模型 [Qwen/QwQ-32B](https://www.modelscope.cn/models/Qwen/QwQ-32B)
---
#### _作者在此 👇🏻 扫一扫_
 ---
## 下载
SDK下载
```bash
#安装ModelScope
pip install modelscope
```
```python
#SDK模型下载
from modelscope import snapshot_download
model_dir = snapshot_download('okwinds/QwQ-32B-FP8')
```
Git下载
```
#Git模型下载
git clone https://www.modelscope.cn/okwinds/QwQ-32B-FP8.git
```
## 模型概述
QwQ-32B-FP8 是一个基于 通义千问 QwQ-32B 的 FP8 量化模型。
- **模型名称:** QwQ-32B-FP8
- **模型架构:** Qwen2.5
- **权重量化:** FP8
该模型通过将 [qwen/QwQ-32B](https://www.modelscope.cn/models/Qwen/QwQ-32B) 的权重量化为 FP8 数据类型而实现。
量化过程将每个参数从 16bit 减少到 8bit,将模型占用磁盘空间大小,以及推理时加载模型需要的GPU显存空间,减少到了大约为原模型的1/2。
FP8(Floating Point 8-bit)是一种8位浮点数数据格式,由Nvidia、Arm、Intel联合推出,旨在加速深度学习的训练和推理过程。
本模型的量化,采用 F8_E4M3 数据类型对权重进行 dynamic 量化,尽可能减少模型量化后所带来的精度损失。
> 注意:本模型需要 compute capability > 8.0(Ampere、Ada Lovelace、Hopper 架构)的 Nvidia GPU 来支持 FP8 **混合精度**计算。
## 部署推理
#### 推荐使用 vLLM
Openai api 兼容模式
```bash
>>> vllm serve "/home/gavin/llm/QwQ-32B-FP8" --host 0.0.0.0 --port 8000 --gpu-memory-utilization 0.9 --served-model-name "QwQ-32B-FP8"
```
---
# 附录 QwQ-32B 介绍
 ## Qwen2.5 同系列模型
#### 同系量化
| **Model** | GPTQ Compression & FP8 | GGUF | **MLX** (macOS) |
| ------------ |----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------| -------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| *3B params* | - | [3B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-3B-Instruct-GGUF-V3-LOT) | [3B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-3B-Instruct-MLX-4bit)
[3B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-3B-Instruct-MLX-8bit) |
| *7B params* | [7B-Int4-W4A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-7B-Instruct-Int4-W4A16)
[7B-Int8-W8A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-7B-Instruct-Int8-W8A16)
[7B-FP8-A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-7B-Instruct-FP8-A16)
[Coder-7B-Instruct-FP8](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-7B-Instruct-FP8) | [7B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-7B-Instruct-GGUF-V3-LOT) | [7B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-7B-Instruct-MLX-4bit)
[7B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-7B-Instruct-MLX-8bit) |
| *Coder 7B params* | [Coder-7B-Int4-W4A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-7B-Instruct-Int4-W4A16)
[Coder-7B-Int8-W8A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-7B-Instruct-Int8-W8A16)
[Coder-7B-FP8-A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-7B-Instruct-FP8-A16) | [Coder-7B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-7B-Instruct-GGUF-V3-LOT) | [Coder-7B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-7B-Instruct-MLX-4bit)
[Coder-7B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-7B-Instruct-MLX-8bit) |
| *14B params* | [14B-Int4-W4A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-14B-Instruct-Int4-W4A16)
[14B-Int8-W8A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-14B-Instruct-Int8-W8A16)
[14B-FP8-A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-14B-Instruct-FP8-A16) | [14B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-14B-Instruct-GGUF-V3-LOT) | [14B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-14B-Instruct-MLX-4bit)
[14B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-14B-Instruct-MLX-8bit) |
| *Coder 14B params* | [Coder-14B-Int4-W4A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-14B-Instruct-Int4-W4A16)
[Coder-14B-Int8-W8A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-14B-Instruct-Int8-W8A16) | [Coder-14B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-14B-Instruct-GGUF-V3-LOT) | [Coder-14B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-14B-Instruct-MLX-4bit)
[Coder-14B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-14B-Instruct-MLX-8bit) |
| *32B params* | [32B-Int4-W4A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-32B-Instruct-Int4-W4A16)
[32B-Int8-W8A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-32B-Instruct-Int8-W8A16)
[32B-FP8-A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-32B-Instruct-FP8-A16) | [32B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-32B-Instruct-GGUF-V3-LOT) | [32B-MLX-2bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-32B-Instruct-MLX-2bit)
[32B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-32B-Instruct-MLX-4bit)
[32B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-32B-Instruct-MLX-8bit) |
| *Coder 32B params* | [Coder-32B-Int4-W4A16](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-32B-Instruct-Int4-W4A16)
[Coder-32B-FP8](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-32B-Instruct-FP8) | [Coder-32B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-32B-Instruct-GGUF-V3-LOT) | [Coder-32B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-32B-Instruct-MLX-4bit)
[Coder-32B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-Coder-32B-Instruct-MLX-8bit) |
| *QwQ-Preview 32B params* | [QwQ-32B-Preview-Int4-W4A16](https://www.modelscope.cn/models/okwinds/QwQ-32B-Preview-Int4-W4A16)
[QwQ-32B-Preview-FP8](https://www.modelscope.cn/models/okwinds/QwQ-32B-Preview-FP8) | [QwQ-32B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/QwQ-32B-Preview-GGUF-V3-LOT) | [QwQ-32B-MLX-4bit](https://www.modelscope.cn/models/okwinds/QwQ-32B-Preview-MLX-4bit)
[QwQ-32B-MLX-8bit](https://www.modelscope.cn/models/okwinds/QwQ-32B-Preview-MLX-8bit) |
| *72B params* | - | [72B-GGUF-V3-LOT](https://www.modelscope.cn/models/okwinds/Qwen2.5-72B-Instruct-GGUF-V3-LOT) | [72B-MLX-2bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-72B-Instruct-MLX-2bit)
[72B-MLX-4bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-72B-Instruct-MLX-4bit)
[72B-MLX-8bit](https://www.modelscope.cn/models/okwinds/Qwen2.5-72B-Instruct-MLX-8bit) |
## Introduction
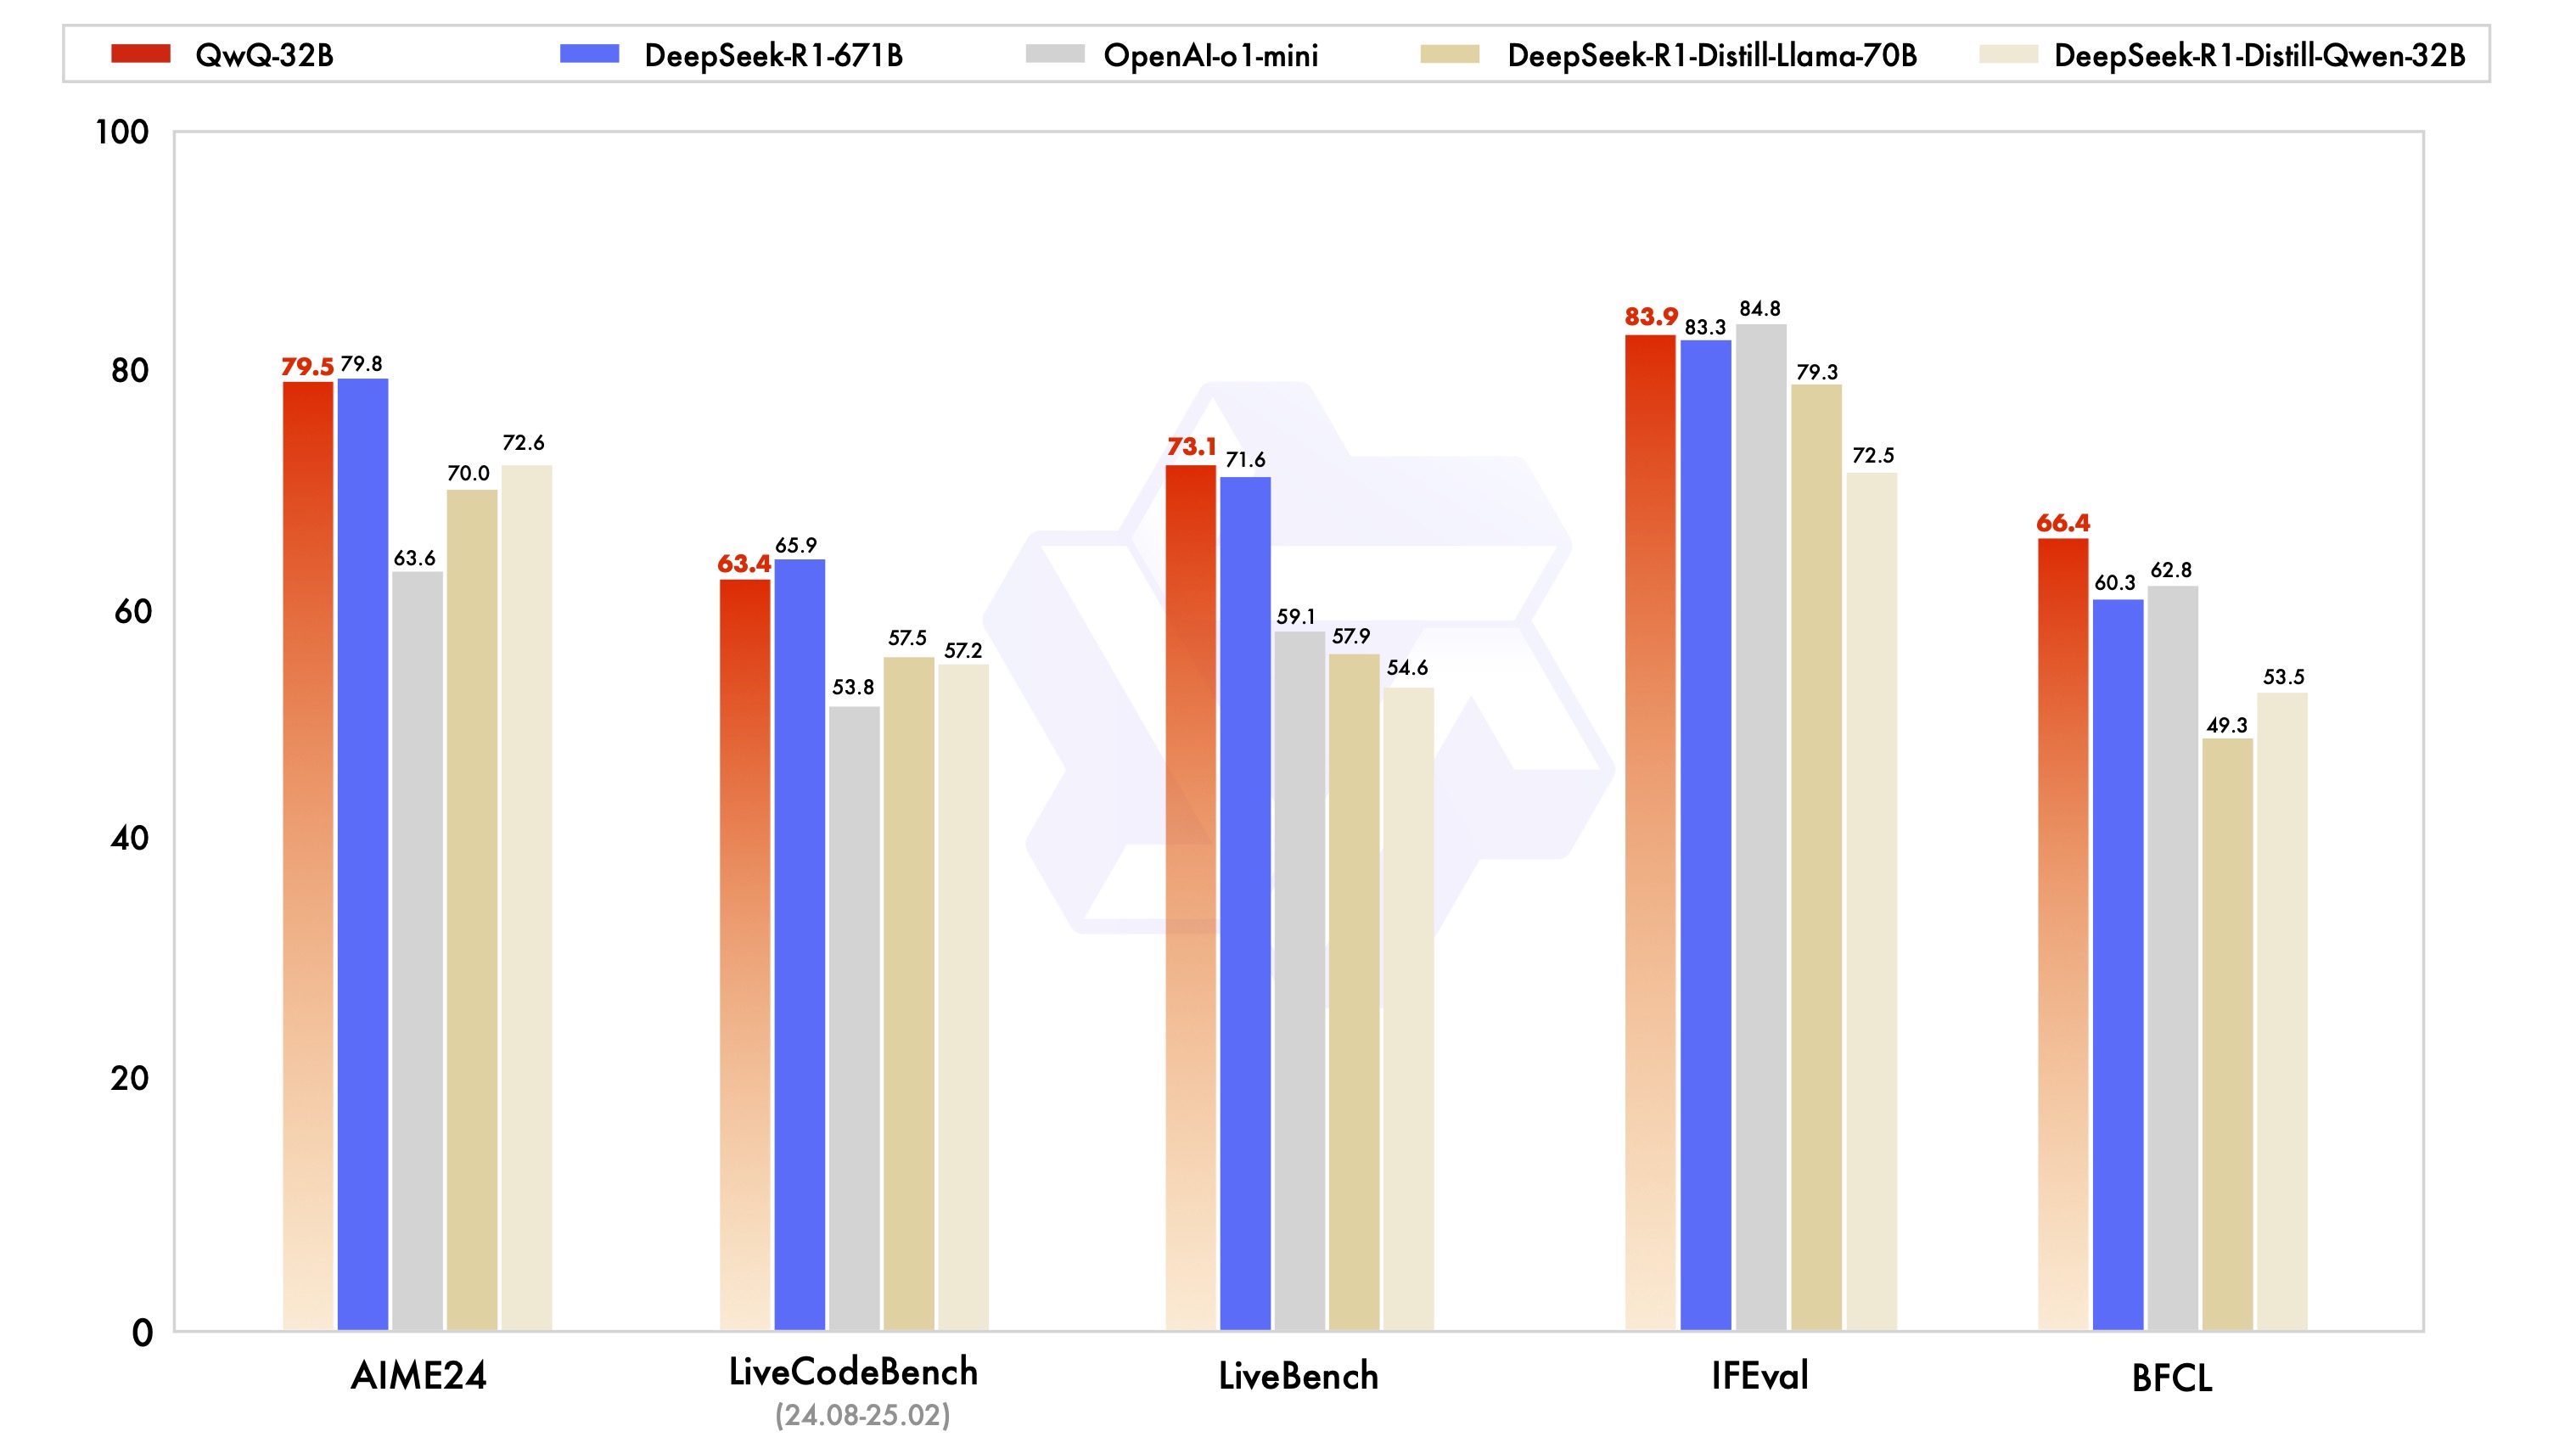
QwQ is the reasoning model of the Qwen series. Compared with conventional instruction-tuned models, QwQ, which is capable of thinking and reasoning, can achieve significantly enhanced performance in downstream tasks, especially hard problems. QwQ-32B is the medium-sized reasoning model, which is capable of achieving competitive performance against state-of-the-art reasoning models, e.g., DeepSeek-R1, o1-mini.
**This repo contains the QwQ 32B model**, which has the following features:
- Type: Causal Language Models
- Training Stage: Pretraining & Post-training (Supervised Finetuning and Reinforcement Learning)
- Architecture: transformers with RoPE, SwiGLU, RMSNorm, and Attention QKV bias
- Number of Parameters: 32.5B
- Number of Paramaters (Non-Embedding): 31.0B
- Number of Layers: 64
- Number of Attention Heads (GQA): 40 for Q and 8 for KV
- Context Length: Full 131,072 tokens
**Note:** For the best experience, please review the [usage guidelines](#usage-guidelines) before deploying QwQ models.
You can try our [demo](https://huggingface.co/spaces/Qwen/QwQ-32B-Demo) or access QwQ models via [QwenChat](https://chat.qwen.ai).
For more details, please refer to our [blog](https://qwenlm.github.io/blog/qwq-32b/), [GitHub](https://github.com/QwenLM/Qwen2.5), and [Documentation](https://qwen.readthedocs.io/en/latest/).
## Requirements
QwQ is based on Qwen2.5, whose code has been in the latest Hugging face `transformers`. We advise you to use the latest version of `transformers`.
With `transformers<4.37.0`, you will encounter the following error:
```
KeyError: 'qwen2'
```
## Usage Guidelines
To achieve optimal performance, we recommend the following settings:
1. **Enforce Thoughtful Output**: Ensure the model starts with "\\n" to prevent generating empty thinking content, which can degrade output quality. If you use `apply_chat_template` and set `add_generation_prompt=True`, this is already automatically implemented, but it may cause the response to lack the \ tag at the beginning. This is normal behavior.
2. **Sampling Parameters**:
- Use Temperature=0.6 and TopP=0.95 instead of Greedy decoding to avoid endless repetitions.
- Use TopK between 20 and 40 to filter out rare token occurrences while maintaining the diversity of the generated output.
3. **No Thinking Content in History**: In multi-turn conversations, the historical model output should only include the final output part and does not need to include the thinking content. This feature is already implemented in `apply_chat_template`.
4. **Standardize Output Format**: We recommend using prompts to standardize model outputs when benchmarking.
- **Math Problems**: Include "Please reason step by step, and put your final answer within \boxed{}." in the prompt.
- **Multiple-Choice Questions**: Add the following JSON structure to the prompt to standardize responses: "Please show your choice in the `answer` field with only the choice letter, e.g.,`\"answer\": \"C\"`." in the prompt.
5. **Handle Long Inputs**: For inputs exceeding 32,768 tokens, enable [YaRN](https://arxiv.org/abs/2309.00071) to improve the model's ability to capture long-sequence information effectively.
For supported frameworks, you could add the following to `config.json` to enable YaRN:
```json
{
...,
"rope_scaling": {
"factor": 4.0,
"original_max_position_embeddings": 32768,
"type": "yarn"
}
}
```
For deployment, we recommend using vLLM. Please refer to our [Documentation](https://qwen.readthedocs.io/en/latest/deployment/vllm.html) for usage if you are not familar with vLLM.
Presently, vLLM only supports static YARN, which means the scaling factor remains constant regardless of input length, **potentially impacting performance on shorter texts**.
We advise adding the `rope_scaling` configuration only when processing long contexts is required.
## Evaluation & Performance
Detailed evaluation results are reported in this [📑 blog](https://qwenlm.github.io/blog/qwq-32b/).
For requirements on GPU memory and the respective throughput, see results [here](https://qwen.readthedocs.io/en/latest/benchmark/speed_benchmark.html).