---
title: vitpose_image_pose_detection
canonical_url: "https://www.modelscope.cn/models/iic/vitpose_image_pose_detection"
md_url: "https://www.modelscope.cn/models/iic/vitpose_image_pose_detection.md"
repository: iic/vitpose_image_pose_detection
chinese_name: "VitPose姿态估计"
last_updated: 2023-09-14
license: "MIT License"
library_name:
- pytorch
frameworks:
- pytorch
domain:
- cv
downloads: 5730
stars: 13
tags:
- VitPose
- "Pose Detection"
- "姿态检测"
---
# vitpose_image_pose_detection
> vitpose_image_pose_detection - iic 在 ModelScope 开源的模型。VitPose姿态估计SOTA
iic/vitpose_image_pose_detection 是 ModelScope 魔搭社区上的机器学习模型,采用 MIT License 许可。
- **Repository**: iic/vitpose_image_pose_detection
- **License**: MIT License
- **Tags**: VitPose, Pose Detection, 姿态检测
- **Downloads**: 5730
- **Stars**: 13
- **Last updated**: 2023-09-14
Source: https://www.modelscope.cn/models/iic/vitpose_image_pose_detection
---
# VitPose 姿态估计
[](https://paperswithcode.com/sota/pose-estimation-on-coco-test-dev?p=vitpose-simple-vision-transformer-baselines)
[](https://paperswithcode.com/sota/pose-estimation-on-aic?p=vitpose-simple-vision-transformer-baselines)
[](https://paperswithcode.com/sota/pose-estimation-on-crowdpose?p=vitpose-simple-vision-transformer-baselines)
[](https://paperswithcode.com/sota/pose-estimation-on-ochuman?p=vitpose-simple-vision-transformer-baselines)
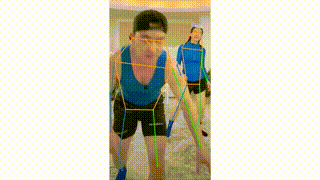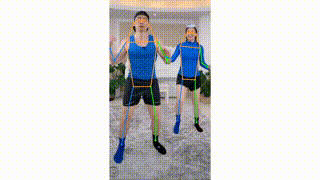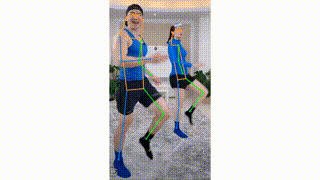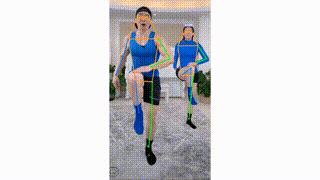
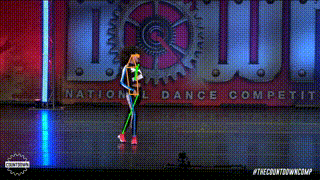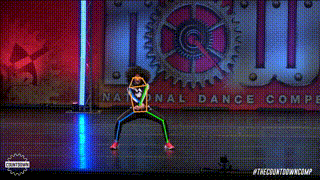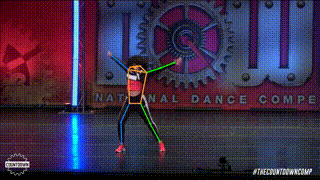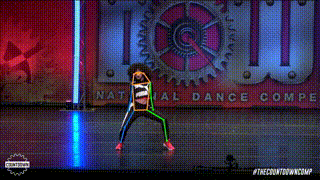
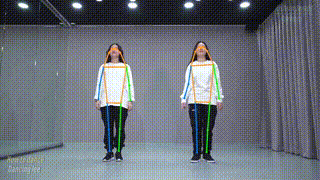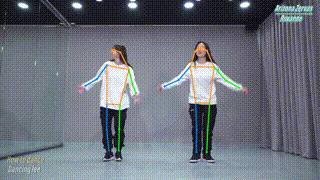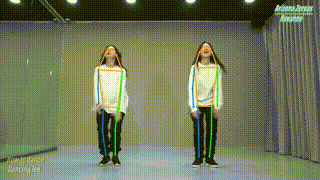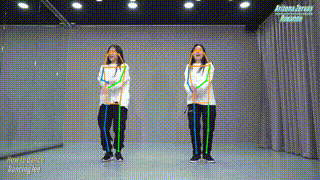
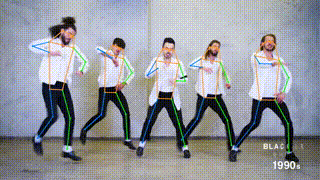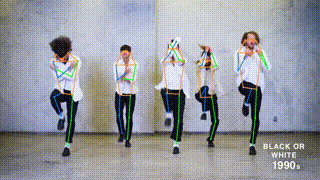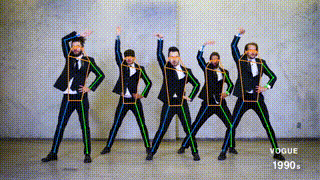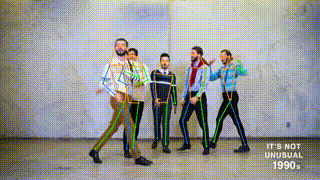
## 模型描述
该模型是对论文 ViTPose: Simple Vision Transformer Baselines for Human Pose Estimation 以及 ViTPose+: Vision Transformer Foundation Model for Generic Body Pose Estimation的实现。采用Vit模型进行全身关键点的预测。
 ## 期望模型使用方式以及适用范围
本模型适用范围为室内室外自然场景;
### 如何使用
在ModelScope框架上,提供输入图片,即可通过简单的Pipeline调用来使用。
#### 环境配置
```shell
# 安装git(如有请跳过)
conda install -c anaconda git
# 准备基础环境
conda create -n vitpose python=3.8
conda activate vitpose
# modelscope 环境(如有请跳过)
pip install modelscope
# VitPose克隆
git clone https://github.com/ViTAE-Transformer/ViTPose.git
cd ViTPose
vim mmpose/__init__.py
修改mmcv_maximum_version = '1.5.0' 为 mmcv_maximum_version = '1.7.0', 保存退出
pip install -v -e .
```
#### 代码范例
```shell
cd ..
vim demo.py
```
在demo.py文件中添加以下代码
```
import numpy as np
from PIL import Image
from modelscope.pipelines import pipeline
## 使用自己的图片
input = Image.open("vcg.jpg").convert("RGB")
input = np.array(input)
inference = pipeline('VitPose', model="damo/vitpose_image_pose_detection", model_revision='v1.0.3')
detected_map = inference(input)
Image.fromarray(np.clip(detected_map, 0, 255).astype(np.uint8)).save("pose.jpg")
```
随后执行python demo.py即可
### 模型局限性以及可能的偏差
- 关键点在大姿态,遮挡情况下可能不准确。
## 引用
如果你觉得这个该模型对有所帮助,请考虑引用下面的相关的论文:
```BibTeX
@inproceedings{
xu2022vitpose,
title={Vi{TP}ose: Simple Vision Transformer Baselines for Human Pose Estimation},
author={Yufei Xu and Jing Zhang and Qiming Zhang and Dacheng Tao},
booktitle={Advances in Neural Information Processing Systems},
year={2022},
}
```
```BibTeX
@article{xu2022vitpose+,
title={ViTPose+: Vision Transformer Foundation Model for Generic Body Pose Estimation},
author={Xu, Yufei and Zhang, Jing and Zhang, Qiming and Tao, Dacheng},
journal={arXiv preprint arXiv:2212.04246},
year={2022}
}
```