---
title: code-millenials-3b
canonical_url: "https://www.modelscope.cn/models/budecosystem/code-millenials-3b"
md_url: "https://www.modelscope.cn/models/budecosystem/code-millenials-3b.md"
repository: budecosystem/code-millenials-3b
last_updated: 2026-02-28
model_type:
- mpt
architectures:
- MPTForCausalLM
library_name:
- pytorch
- transformer
frameworks:
- pytorch
inference_backends:
- "deploy_task text/emb"
- "vllm 0.9.2"
downloads: 17
stars: 0
tags:
- code
---
# code-millenials-3b
> code-millenials-3b - budecosystem 在 ModelScope 开源的模型。Bud Code Millenials 3B
budecosystem/code-millenials-3b 是 ModelScope 魔搭社区上的机器学习模型,可用 deploy_task text/emb、vllm 0.9.2 部署。
- **Repository**: budecosystem/code-millenials-3b
- **Inference backends**: deploy_task text/emb, vllm 0.9.2
- **Tags**: code
- **Downloads**: 17
- **Stars**: 0
- **Last updated**: 2026-02-28
Source: https://www.modelscope.cn/models/budecosystem/code-millenials-3b
---
# Bud Code Millenials 3B
Welcome to our Code Model repository! Our model is specifically fine-tuned for code generation tasks. Bud Millenial Code Gen open-source models are currently the State of the Art (SOTA) for code generation, beating all the existing models of all sizes. We have achieved a HumanEval value of 80.48 @ Pass 1, beating proprietary models like Gemini Ultra, Claude, GPT-3.5 etc. by a large margin, and on par with GPT-4 (HumanEval ~ 82. Ref. WizardCoder). Our proprietary model (Bud Code Jr) beats GPT-4 as well with a HumanEval value of 88.2 & a context size of 168K, we will be releasing an API for Researchers, Enterprises, and potential Partners by January 2024 end. If interested, please reach out to jithinvg@bud.studio
### News 🔥🔥🔥
- [2024/01/09] We released **Code Millenials 3B** , which achieves the **56.09 pass@1** on the [HumanEval Benchmarks](https://github.com/openai/human-eval).
- [2024/01/09] We released **Code Millenials 1B** , which achieves the **51.82 pass@1** on the [HumanEval Benchmarks](https://github.com/openai/human-eval).
- [2024/01/03] We released **Code Millenials 34B** , which achieves the **80.48 pass@1** on the [HumanEval Benchmarks](https://github.com/openai/human-eval).
- [2024/01/02] We released **Code Millenials 13B** , which achieves the **76.21 pass@1** on the [HumanEval Benchmarks](https://github.com/openai/human-eval).
### HumanEval
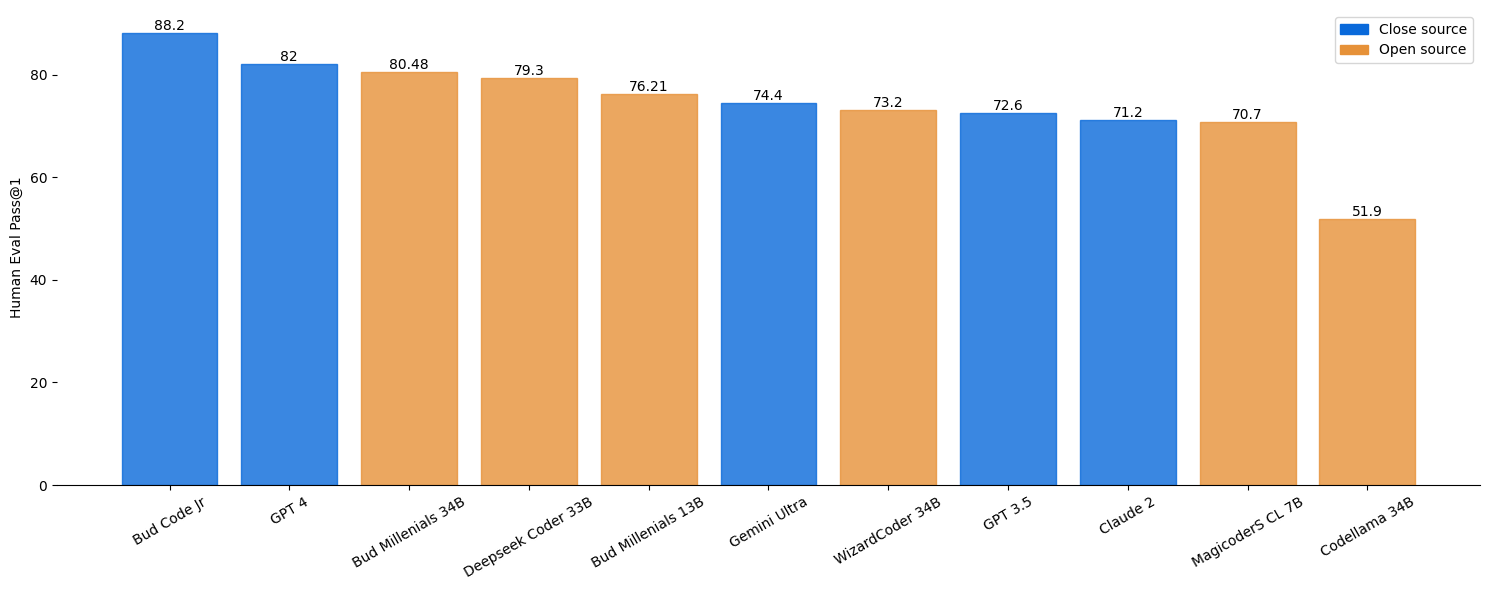
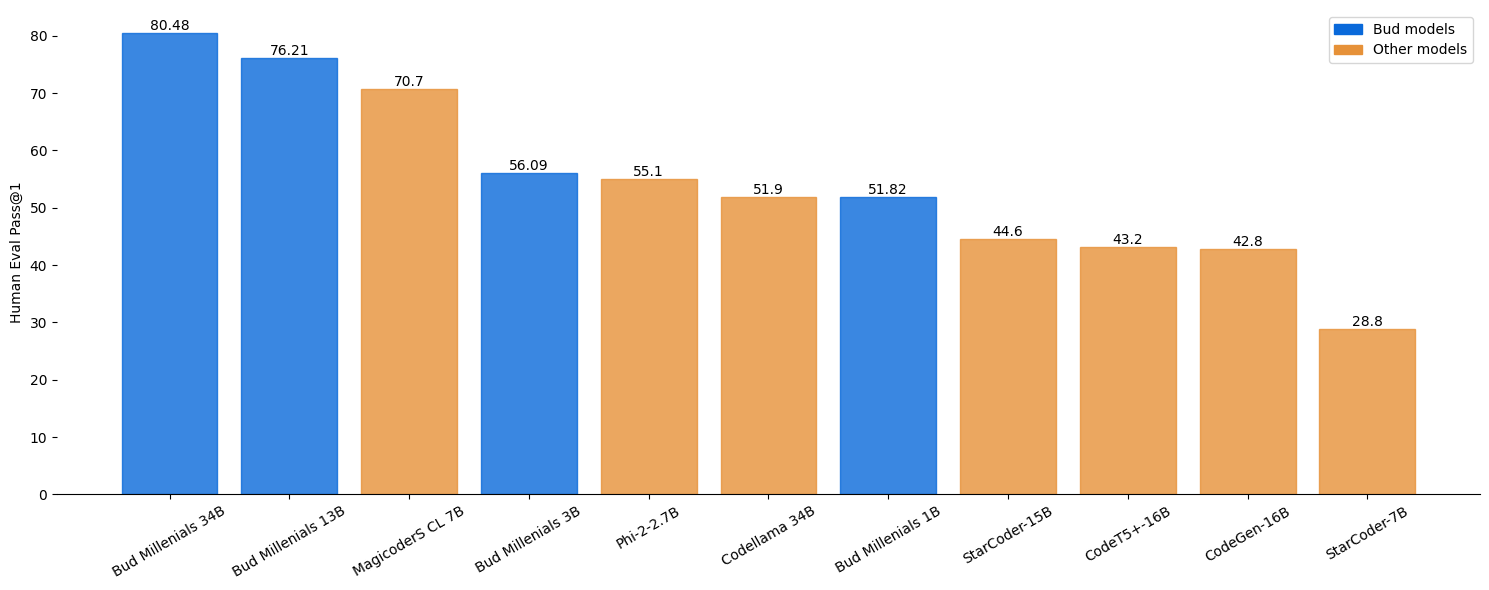
For the millenial models, the eval script in the github repo is used for the above result.
Note: The humaneval values of other models are taken from the official repos of [WizardCoder](https://github.com/nlpxucan/WizardLM), [DeepseekCoder](https://github.com/deepseek-ai/deepseek-coder), [Gemini](https://deepmind.google/technologies/gemini/#capabilities) etc.
### Models
| Model | Checkpoint | HumanEval (+) | MBPP (+) |
|---------|-------------|---------------|----------|
|Code Millenials 34B | HF Link | 80.48 (75) | 74.68 (62.9) |
|Code Millenials 13B | HF Link | 76.21 (69.5) | 70.17 (57.6) |
|Code Millenials 3B | HF Link | 56.09 (52.43) | 55.13 (47.11) |
|Code Millenials 1B | HF Link | 51.82 (48.17) | 53.13 (44.61) |
### 🚀 Quick Start
Inference code using the pre-trained model from the Hugging Face model hub
```python
import torch
from transformers import AutoTokenizer, AutoModelForCausalLM
tokenizer = AutoTokenizer.from_pretrained("budecosystem/code-millenials-3b")
model = AutoModelForCausalLM.from_pretrained("budecosystem/code-millenials-3b")
template = """A chat between a curious user and an artificial intelligence assistant. The assistant gives helpful, detailed, and polite answers to the user's questions.
### Instruction: {instruction} ### Response:"""
instruction =
prompt = template.format(instruction=instruction)
inputs = tokenizer(prompt, return_tensors="pt")
sample = model.generate(**inputs, max_length=128)
print(tokenizer.decode(sample[0]))
```
## Training details
The model is trained of 8 A100 80GB for approximately 6hrs.
| Hyperparameters | Value |
| :----------------------------| :-----: |
| per_device_train_batch_size | 3 |
| gradient_accumulation_steps | 1 |
| epoch | 3 |
| steps | 26289 |
| learning_rate | 2e-5 |
| lr schedular type | cosine |
| warmup ratio | 0.15 |
| optimizer | adamw |
| fp16 | True |
| GPU | 8 A100 80GB |
### Important Note
- **Bias, Risks, and Limitations:** Model may sometimes make errors, produce misleading contents, or struggle to manage tasks that are not related to coding.