---
title: Glyph
canonical_url: "https://www.modelscope.cn/models/ZhipuAI/Glyph"
md_url: "https://www.modelscope.cn/models/ZhipuAI/Glyph.md"
repository: ZhipuAI/Glyph
chinese_name: Glyph
last_updated: 2026-01-20
license: mit
pipeline_tag: image-text-to-text
tasks:
- image-text-to-text
model_type:
- glm4v
architectures:
- Glm4vForConditionalGeneration
base_model:
- zai-org/GLM-4.1V-9B-Base
base_model_relation: finetune
parameters: 10.3B
tensor_type:
- BF16
library_name:
- pytorch
- transformer
- safetensors
frameworks:
- Pytorch
language:
- zh
- en
inference_backends:
- "deploy_task vlm/text/emb"
- "sglang 0.5.2"
- "vllm 0.9.2"
downloads: 5563
stars: 10
---
# Glyph
> Glyph - ZhipuAI 在 ModelScope 开源的模型。Glyph: Scaling Context Windows via Visual-Text Compression
ZhipuAI/Glyph 是 ModelScope 魔搭社区上的 10.3B 参数image-text-to-text模型,采用 mit 许可,基于 zai-org/GLM-4.1V-9B-Base 构建,可用 deploy_task vlm/text/emb、sglang 0.5.2、vllm 0.9.2 部署。
- **Repository**: ZhipuAI/Glyph
- **License**: mit
- **Tasks**: image-text-to-text
- **Parameters**: 10.3B
- **Base model**: zai-org/GLM-4.1V-9B-Base
- **Inference backends**: deploy_task vlm/text/emb, sglang 0.5.2, vllm 0.9.2
- **Downloads**: 5563
- **Stars**: 10
- **Last updated**: 2026-01-20
Source: https://www.modelscope.cn/models/ZhipuAI/Glyph
---
Glyph: Scaling Context Windows via Visual-Text Compression
- **Repository:** https://github.com/thu-coai/Glyph
- **Paper:** https://arxiv.org/abs/2510.17800
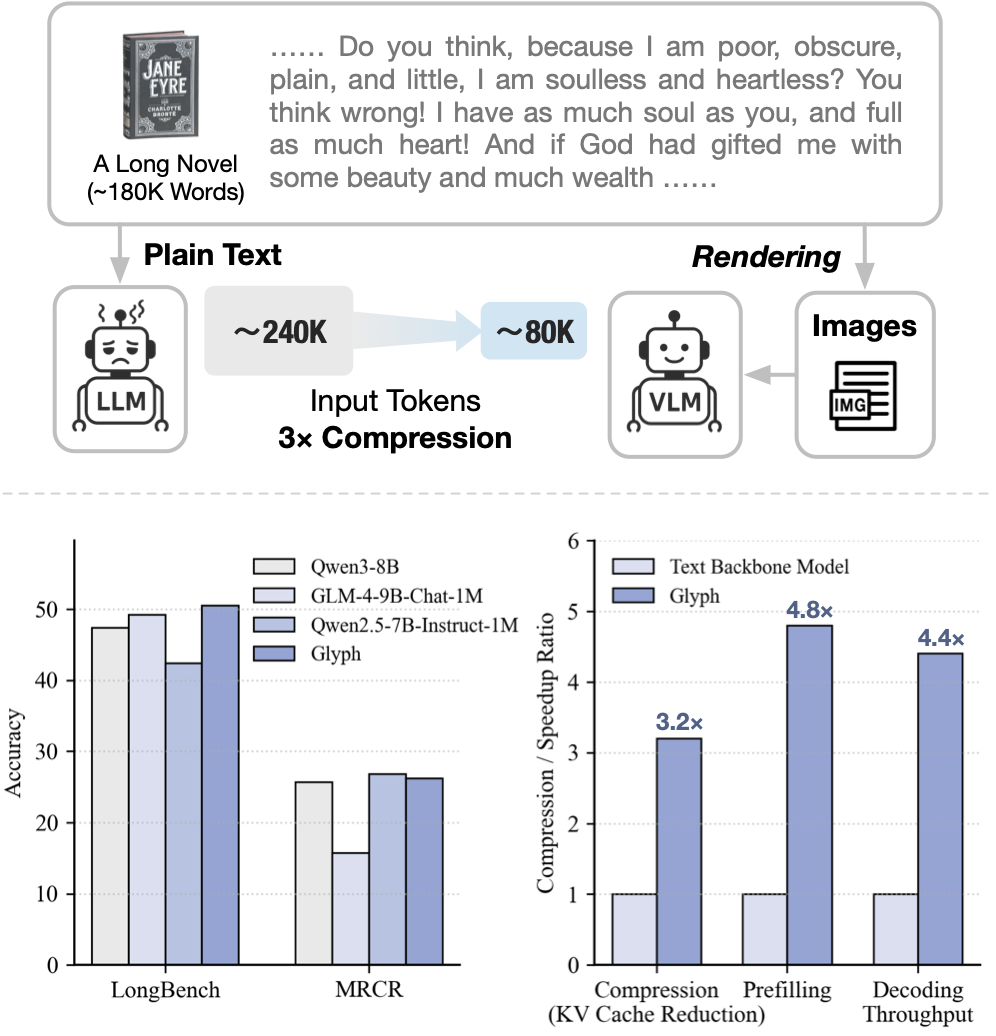
**Glyph** is a framework for scaling the context length through visual-text compression.
Instead of extending token-based context windows, Glyph renders long textual sequences into images and processes them using vision–language models (VLMs).
This design transforms the challenge of long-context modeling into a multimodal problem, substantially reducing computational and memory costs while preserving semantic information.
### Backbone Model
Our model is built on [GLM-4.1V-9B-Base](https://huggingface.co/zai-org/GLM-4.1V-9B-Base).
### Quick Inference
This is a simple example of running single-image inference using the `transformers` library.
First, install the `transformers` library:
```
pip install transformers>=4.57.1
```
Then, run the following code:
```python
from transformers import AutoProcessor, AutoModelForImageTextToText
import torch
messages = [
{
"role": "user",
"content": [
{
"type": "image",
"url": "https://raw.githubusercontent.com/thu-coai/Glyph/main/assets/Little_Red_Riding_Hood.png"
},
{
"type": "text",
"text": "Who pretended to be Little Red Riding Hood's grandmother"
}
],
}
]
processor = AutoProcessor.from_pretrained("zai-org/Glyph")
model = AutoModelForImageTextToText.from_pretrained(
pretrained_model_name_or_path="zai-org/Glyph",
torch_dtype=torch.bfloat16,
device_map="auto",
)
inputs = processor.apply_chat_template(
messages,
tokenize=True,
add_generation_prompt=True,
return_dict=True,
return_tensors="pt"
).to(model.device)
generated_ids = model.generate(**inputs, max_new_tokens=8192)
output_text = processor.decode(generated_ids[0][inputs["input_ids"].shape[1]:], skip_special_tokens=False)
print(output_text)
```
See our [Github Repo](https://github.com/thu-coai/Glyph) for more detailed usage.
## Known Limitations
- Sensitivity to rendering parameters: Glyph’s performance can vary with rendering settings such as resolution, font, and spacing. Since our search procedure adopts a fixed rendering configuration during post-training, the model may not generalize well to unseen or substantially different rendering styles.
- OCR-related challenges: Recognizing fine-grained or rare alphanumeric strings (e.g., UUIDs) remains difficult for visual-language models, especially with ultra-long inputs, sometimes leading to minor character misclassification.
- Limited generalization: The training of Glyph mainly targets long-context understanding, and its capability on broader tasks is yet to be studied.
## Citation
If you find our model useful in your work, please cite it with:
```
@article{cheng2025glyphscalingcontextwindows,
title={Glyph: Scaling Context Windows via Visual-Text Compression},
author={Jiale Cheng and Yusen Liu and Xinyu Zhang and Yulin Fei and Wenyi Hong and Ruiliang Lyu and Weihan Wang and Zhe Su and Xiaotao Gu and Xiao Liu and Yushi Bai and Jie Tang and Hongning Wang and Minlie Huang},
journal={arXiv preprint arXiv:2510.17800},
year={2025}
}
```