---
title: SenseNova-U1.5-8B-MoT-LoRAs
canonical_url: "https://www.modelscope.cn/models/SenseNova/SenseNova-U1.5-8B-MoT-LoRAs"
md_url: "https://www.modelscope.cn/models/SenseNova/SenseNova-U1.5-8B-MoT-LoRAs.md"
repository: SenseNova/SenseNova-U1.5-8B-MoT-LoRAs
last_updated: 2026-09-25
license: apache-2.0
base_model:
- sensenova/SenseNova-U1.5-8B-MoT
base_model_relation: adapter
parameters: 407.4M
tensor_type:
- BF16
library_name:
- lora
- safetensors
- pytorch
frameworks:
- pytorch
language:
- en
- zh
downloads: 380
stars: 2
tags:
- "native multimodal"
- image-generation
- image-editing
- any-to-any
- lora
- distilled
---
# SenseNova-U1.5-8B-MoT-LoRAs
> SenseNova-U1.5-8B-MoT-LoRAs - SenseNova 在 ModelScope 开源的模型。SenseNova-U1.5-8B-MoT-LoRAs
SenseNova/SenseNova-U1.5-8B-MoT-LoRAs 是 ModelScope 魔搭社区上的 407.4M 参数机器学习模型,采用 apache-2.0 许可,基于 sensenova/SenseNova-U1.5-8B-MoT 构建。
- **Repository**: SenseNova/SenseNova-U1.5-8B-MoT-LoRAs
- **License**: apache-2.0
- **Parameters**: 407.4M
- **Base model**: sensenova/SenseNova-U1.5-8B-MoT
- **Tags**: native multimodal, image-generation, image-editing, any-to-any, lora, distilled
- **Downloads**: 380
- **Stars**: 2
- **Last updated**: 2026-09-25
Source: https://www.modelscope.cn/models/SenseNova/SenseNova-U1.5-8B-MoT-LoRAs
---
# SenseNova-U1.5-8B-MoT-LoRAs
English | 简体中文



## Overview
This repository hosts the official LoRA weights for [**SenseNova-U1.5-8B-MoT**](https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT). [**SenseNova-U1.5-8B-MoT-LoRA-8step-V2**](https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT-LoRAs/blob/main/SenseNova-U1.5-8B-MoT-LoRA-8step-V2.safetensors) is the latest and recommended 8-step LoRA-distilled adapter. Compared with the previous [**SenseNova-U1.5-8B-MoT-LoRA-8step**](https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT-LoRAs/blob/main/SenseNova-U1.5-8B-MoT-LoRA-8step.safetensors), **SenseNova-U1.5-8B-MoT-LoRA-8step-V2** delivers improved visual quality with better color balance, more natural contrast, and reduced oversharpening across the board.
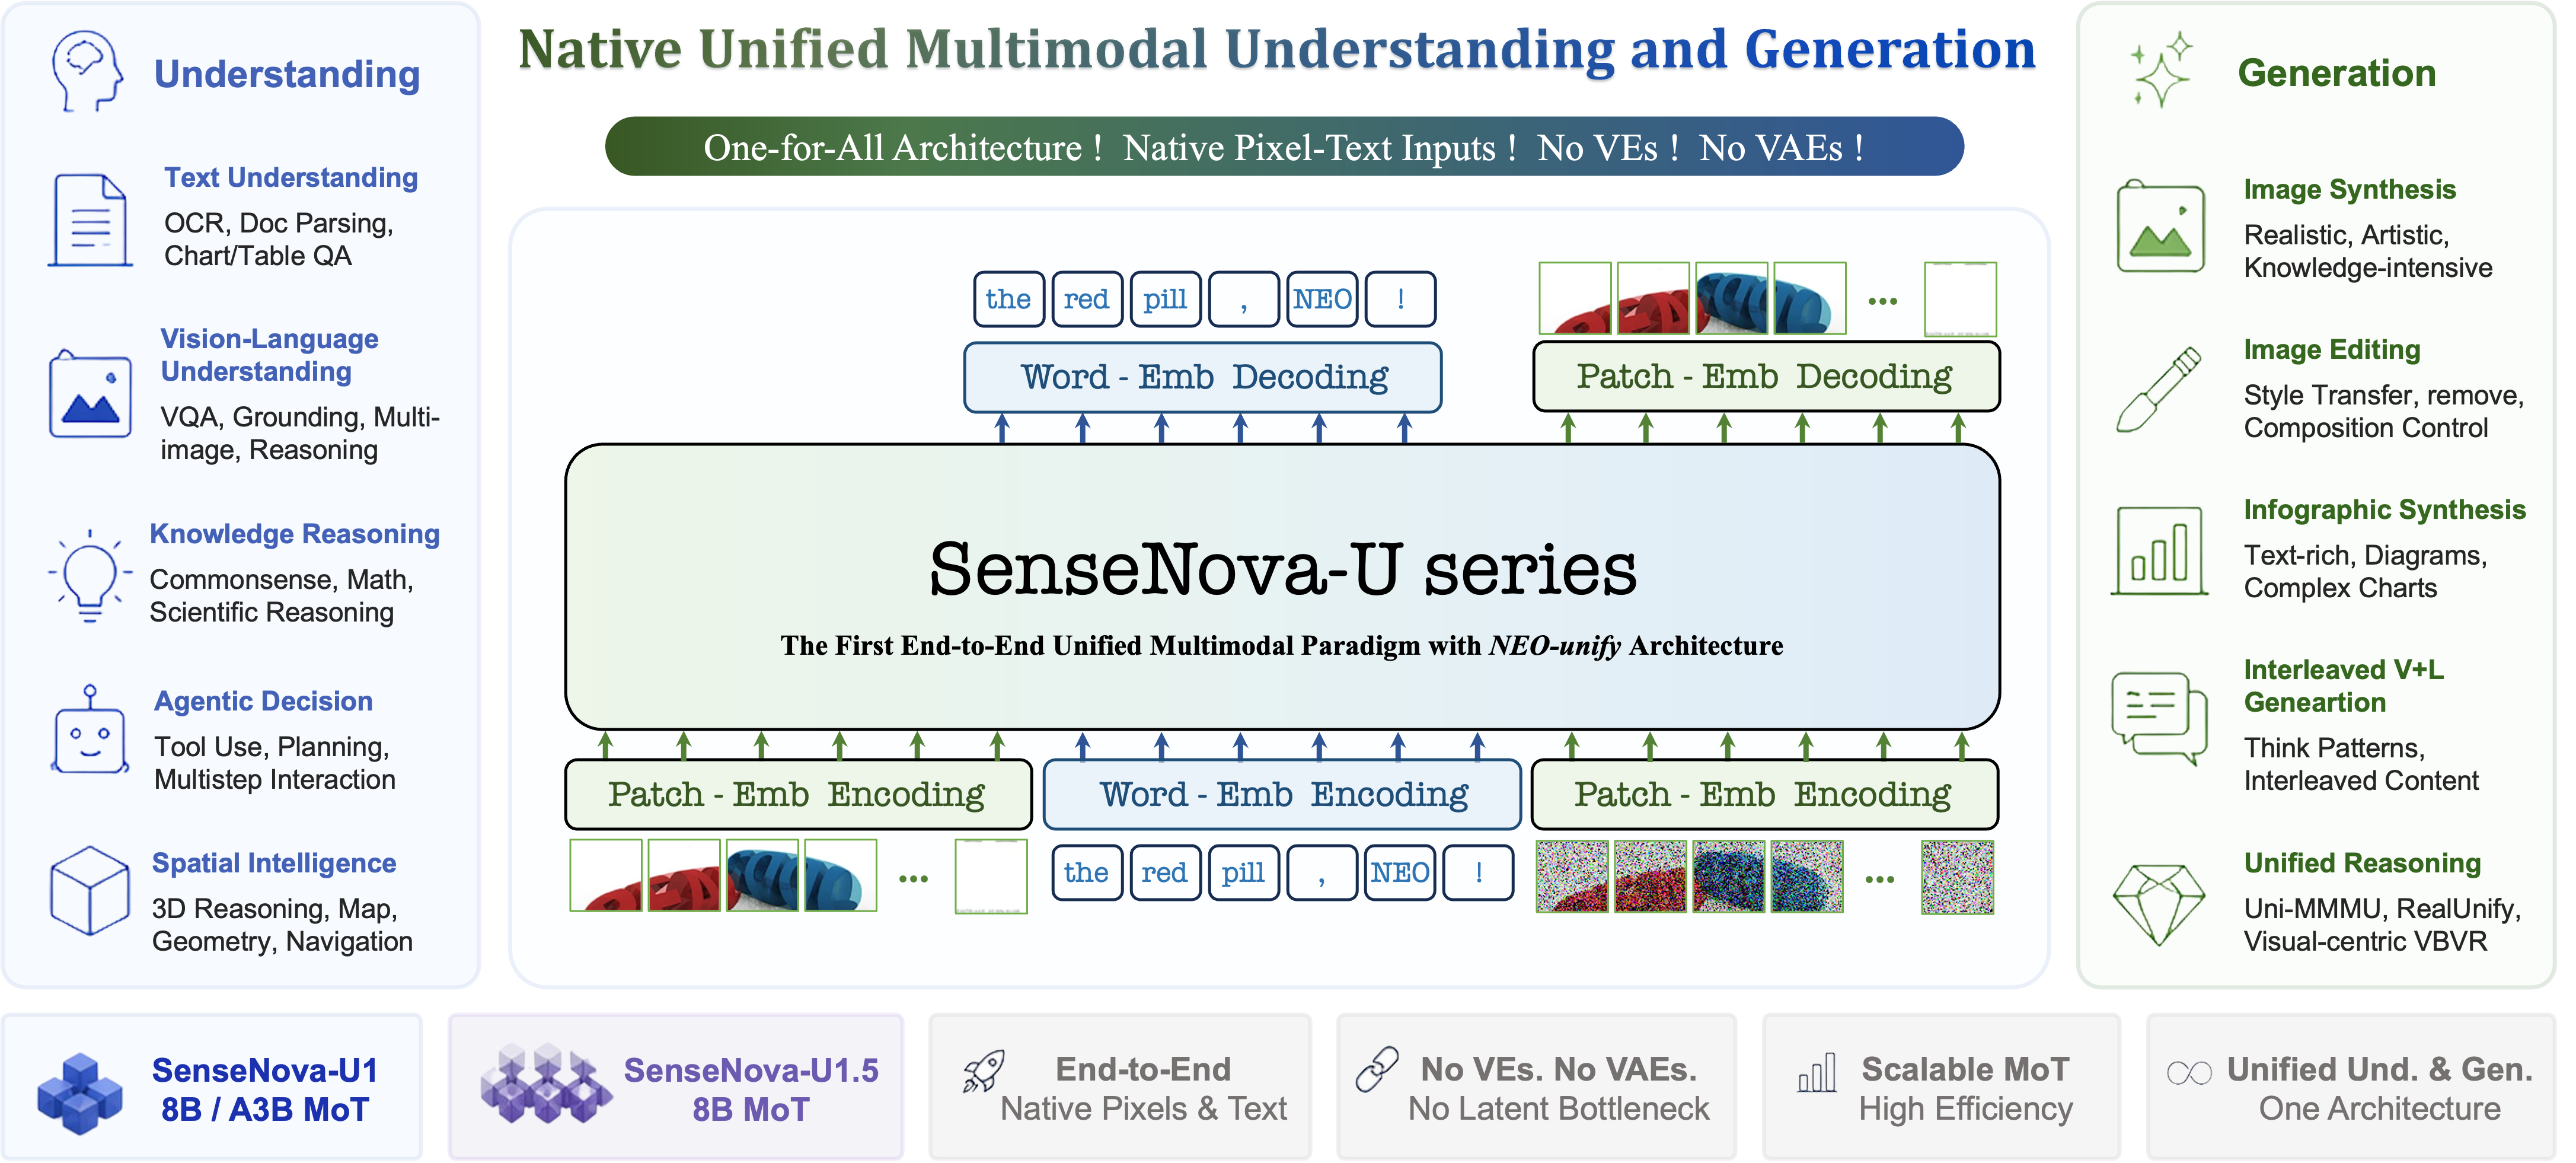
**SenseNova-U1.5-8B-MoT** is our latest native unified multimodal checkpoint for more accurate, consistent, reliable, and aesthetically compelling visual creation. Built on [NEO-unify](https://huggingface.co/blog/sensenova/neo-unify), it strengthens the patchify layers, data quality and distribution, task formulation, prompt enhancement, and post-training pipeline.
The official release focuses on six user-visible improvements:
- **Higher-quality image generation:** improved composition and color harmony, with more realistic material rendering, natural lighting, stronger visual fidelity, and finer local details.
- **Better text rendering and infographic generation:** more legible Chinese and English text, with clearer information hierarchy in posters, infographics, brand assets, and other text-dense designs.
- **More efficient native 4K generation:** more coherent global structure, color harmony, and stable high-resolution output with improved generation efficiency.
- **More reliable native image editing:** stronger preservation of subject identity and unedited content across local, text, multi-reference, insertion, and replacement edits.
- **Stronger complex-instruction following:** more consistent execution of object counts, spatial relationships, layouts, styles, and multiple constraints within a single request.
- **More precise visual control:** more accurate region- and object-level control through bounding boxes, visual markers, and single- or multi-image references.
## Showcases
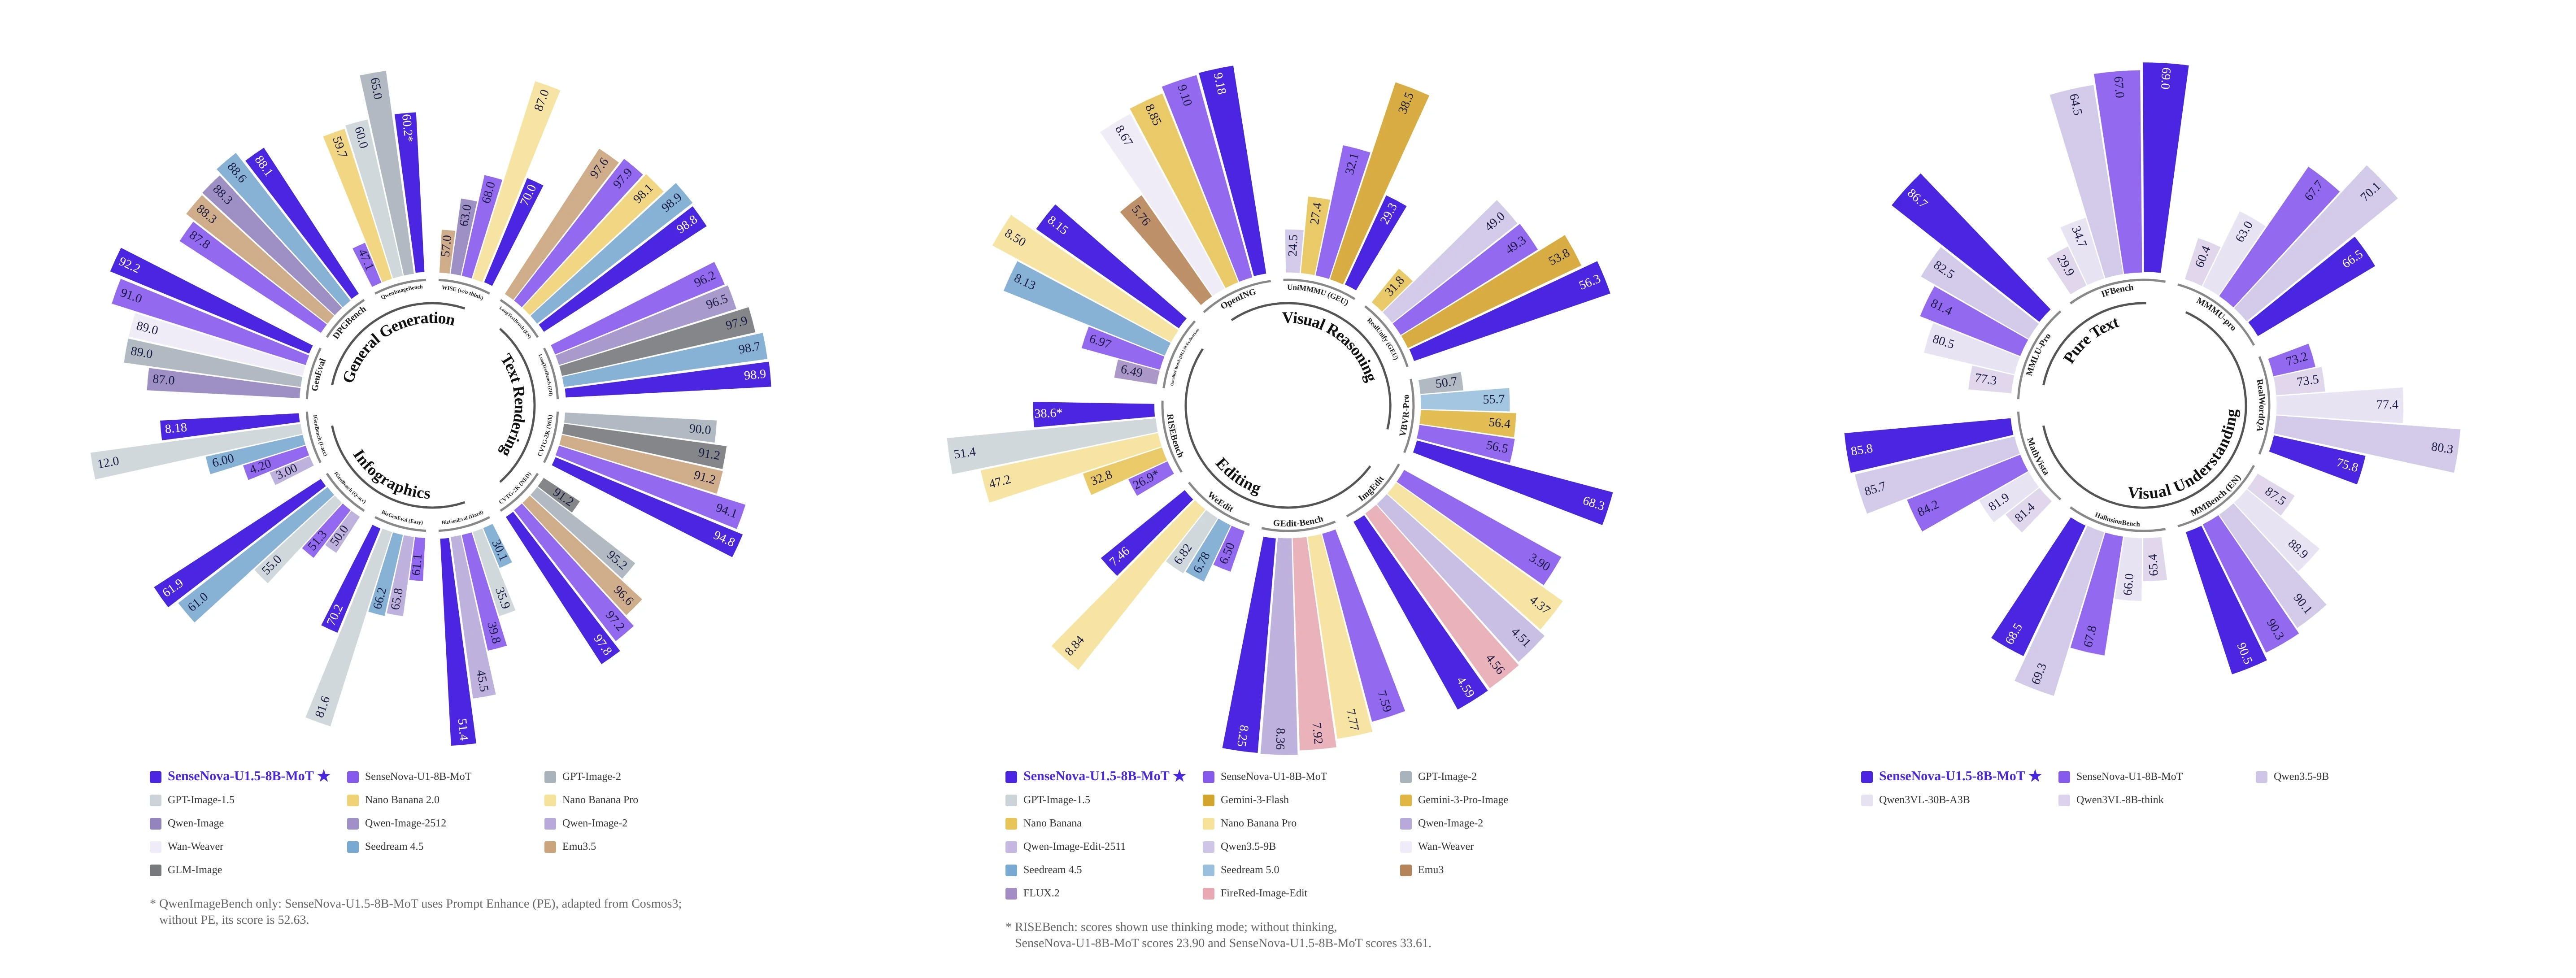
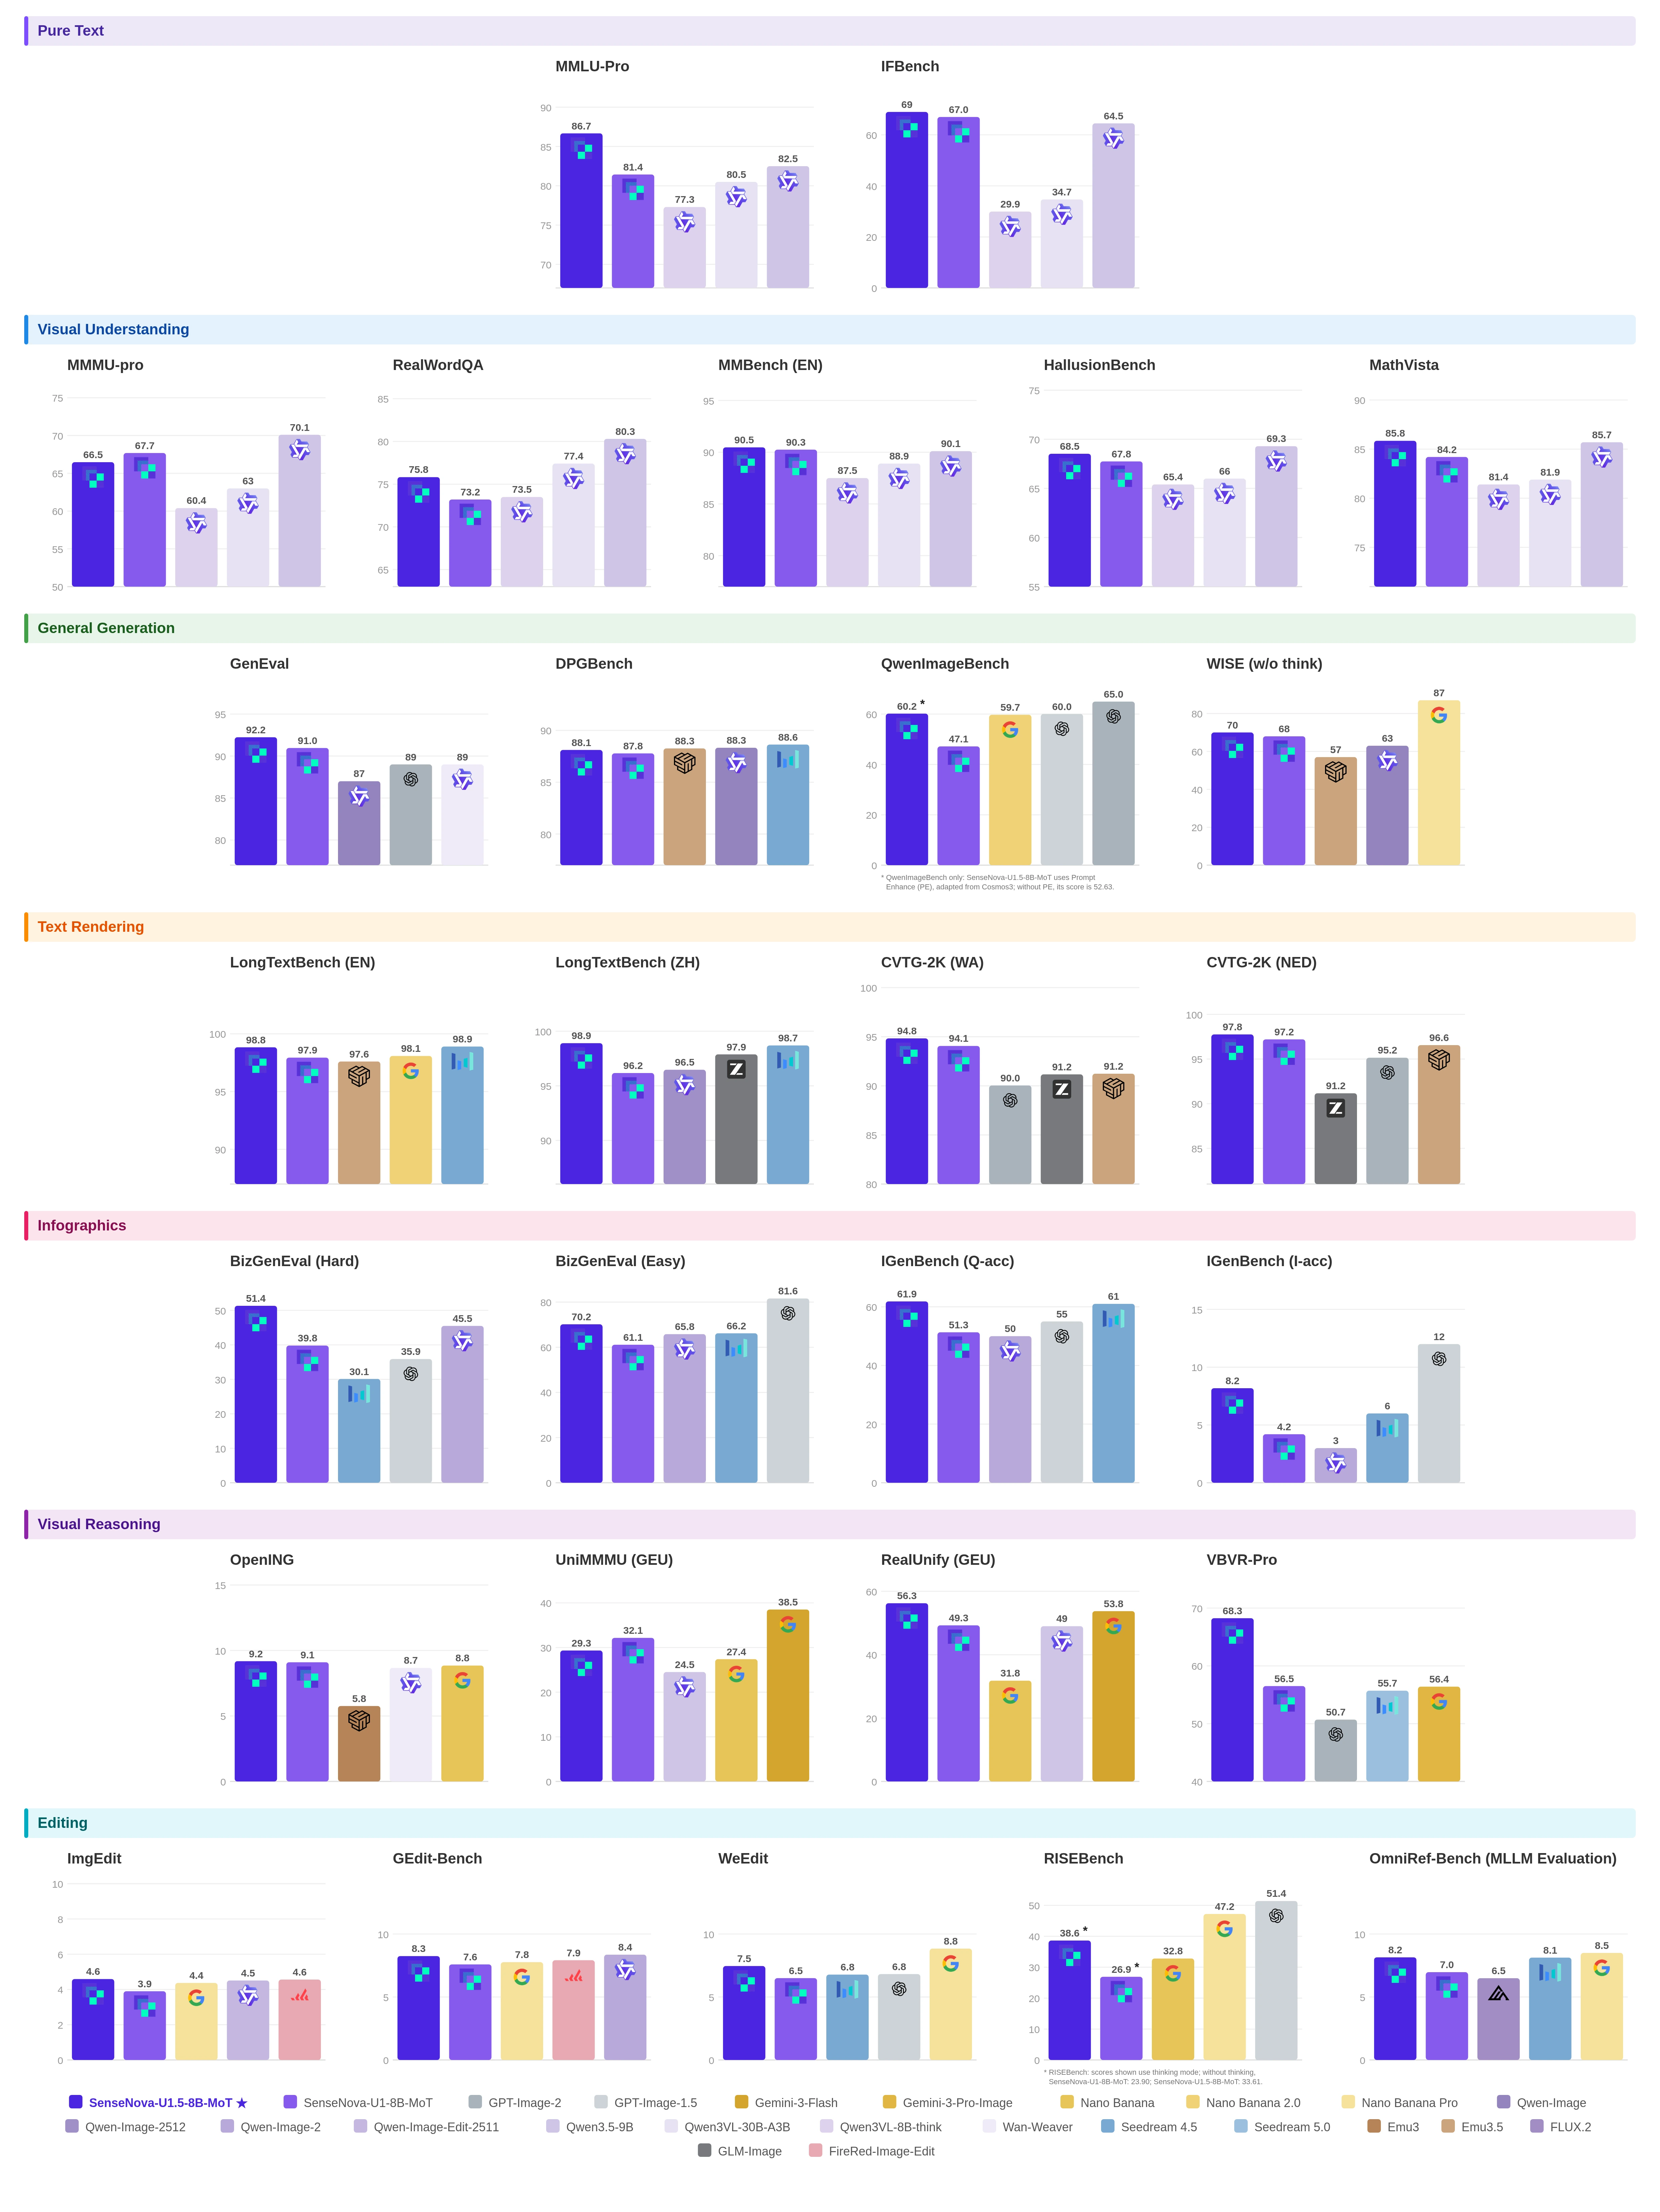
## Key Benchmarks
View detailed benchmark results
## Quick Start
The reference inference implementation is available in the [SenseNova-U1 GitHub repository](https://github.com/OpenSenseNova/SenseNova-U1/tree/refs/heads/feat/u1.5).
### Installation
```bash
git clone https://github.com/OpenSenseNova/SenseNova-U1.git
cd SenseNova-U1
uv sync
source .venv/bin/activate
```
The upstream environment uses Python 3.11, PyTorch 2.8, and CUDA 12.8. For other CUDA versions and optional FlashAttention configurations, see the [installation guide](https://github.com/OpenSenseNova/SenseNova-U1/blob/refs/heads/feat/u1.5/docs/installation.md).
### 8-Step LoRA Text-to-Image (Recommended)
Download the LoRA weight and apply it to the official base checkpoint:
```bash
hf download sensenova/SenseNova-U1.5-8B-MoT-LoRAs \
SenseNova-U1.5-8B-MoT-LoRA-8step-V2.safetensors \
--local-dir ./sensenova/SenseNova-U1.5-8B-MoT-LoRAs
python examples/t2i/inference.py \
--model_path sensenova/SenseNova-U1.5-8B-MoT \
--lora_path ./sensenova/SenseNova-U1.5-8B-MoT-LoRAs/SenseNova-U1.5-8B-MoT-LoRA-8step-V2.safetensors \
--prompt "A cinematic mountain lake at sunrise, realistic photography." \
--width 2048 --height 2048 \
--cfg_scale 1.0 --cfg_norm none --timestep_shift 3.0 --num_steps 8 \
--device_map auto \
--output output.png
```
> [!IMPORTANT]
> This LoRA is intended for `sensenova/SenseNova-U1.5-8B-MoT`. It is not compatible with the earlier `SenseNova-U1.5-8B-MoT-Preview` checkpoint.
### 8-Step LoRA Image Editing (Recommended)
```bash
python examples/editing/inference.py \
--model_path sensenova/SenseNova-U1.5-8B-MoT \
--lora_path ./sensenova/SenseNova-U1.5-8B-MoT-LoRAs/SenseNova-U1.5-8B-MoT-LoRA-8step-V2.safetensors \
--image input.png \
--prompt "Change the jacket to cobalt blue. Preserve the face, pose, background, lighting, and framing." \
--cfg_scale 1.0 --cfg_norm none --timestep_shift 3.0 --num_steps 8 \
--device_map auto \
--output edited.png
```
### Base Model Text-to-Image
```bash
python examples/t2i/inference.py \
--model_path sensenova/SenseNova-U1.5-8B-MoT \
--prompt "A cinematic mountain lake at sunrise, realistic photography." \
--width 2048 --height 2048 \
--device_map auto \
--output output.png
```
### Base Model Image Editing
```bash
python examples/editing/inference.py \
--model_path sensenova/SenseNova-U1.5-8B-MoT \
--image input.png \
--prompt "Change the jacket to cobalt blue. Preserve the face, pose, background, lighting, and framing." \
--output edited.png
```
See the [inference examples](https://github.com/OpenSenseNova/SenseNova-U1/blob/refs/heads/feat/u1.5/examples/README.md) for more options, supported resolutions, and batch processing.
## Best Practices
Direct natural-language prompts work well for clear tasks with few constraints. For complex generation or editing, use prompt enhancement when additional planning is needed and explicitly specify what should remain unchanged.
See the **[SenseNova-U1.5 Cookbook](https://github.com/OpenSenseNova/SenseNova-U1/blob/refs/heads/feat/u1.5/docs/u1.5_best_practices.md)** for setup instructions and optional Image PE, Caption-to-Prompt, and Editing PE recipes.
## 🌐 Use with SenseNova-Studio
The fastest way to experience SenseNova-U1.5 is through **[SenseNova-Studio](https://unify.light-ai.top/)** — a 🆓 free online playground where you can try the model directly in your browser, no installation or GPU required.
## Ongoing Improvements
The official release improves upon the Preview, though challenges remain in:
- **Over-emphasized details or colors:** some prompts may produce excessive high-frequency detail or oversaturated colors, which can often be mitigated by lowering `cfg_scale`.
- **Dense text errors:** dense, lengthy, small, or mixed Chinese-English text may contain errors.
- **Constrained layouts:** exact counts, alignment, or hierarchy may be imperfect in highly constrained layouts.
- **Unstable human details:** small faces, hands, limbs, and fine-grained object structures may remain unstable.
- **Complex editing drift:** broad, multi-turn, or multi-reference edits may drift, especially when many regions must be preserved simultaneously.
## Models
| Model | Stage | HF Weights |
| :---- | :---- | :--------- |
| **SenseNova-U1.5-8B-MoT-LoRA-8step-V2** | 8-step distilled LoRA (0.4B) | [🤗 Weight](https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT-LoRAs/blob/main/SenseNova-U1.5-8B-MoT-LoRA-8step-V2.safetensors) |
| SenseNova-U1.5-8B-MoT-LoRA-8step | 8-step distilled LoRA (0.4B) | [🤗 Weight](https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT-LoRAs/blob/main/SenseNova-U1.5-8B-MoT-LoRA-8step.safetensors) |
| **SenseNova-U1.5-8B-MoT** | RL | [🤗 Model](https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT) |
| SenseNova-U1.5-8B-MoT-SFT | Supervised fine-tuning | [🤗 Model](https://huggingface.co/sensenova/SenseNova-U1.5-8B-MoT-SFT) |
## 🌐 Join the Community!
Join our growing community to share feedback, get support, and stay updated on the latest SenseNova-U1 developments — we'd love to hear from you!
## Citation
If this project is helpful for your research, please consider starring the repository and citing:
```bibtex
@misc{sensenova2026neounify,
title = {NEO-unify: Building Native Multimodal Unified Models End to End},
author = {SenseNova},
journal = {Hugging Face blog},
url = {https://huggingface.co/blog/sensenova/neo-unify},
year = {2026}
}
@article{sensenova2026sensenovau1,
title = {SenseNova-U1: Unifying Multimodal Understanding and Generation with NEO-unify Architecture},
author = {Diao, Haiwen and Wu, Penghao and Deng, Hanming and Wang, Jiahao and Bai, Shihao and Wu, Silei and Fan, Weichen and Ye, Wenjie and Tong, Wenwen and Fan, Xiangyu and others},
journal = {arXiv preprint arXiv:2605.12500},
year = {2026}
}
@article{sensenova2026sensenovau1.5,
title = {SenseNova-U1.5: Towards Native Unified Visual Intelligence},
author = {Diao, Haiwen and Wang, Jiahao and Ding, Chenjing and Deng, Hanming and Chen, Jiangnan and Zhang, Ruixi and Wang, Ruohui and Tong, Wenwen and Fan, Xiangyu and Wang, Yubo and others},
journal = {arXiv preprint arXiv:2609.11929},
year = {2026}
}
```
## License
This model is released under the [Apache 2.0 License](https://github.com/OpenSenseNova/SenseNova-U1/blob/refs/heads/feat/u1.5/LICENSE).