---
title: Qwen3-Coder-30B-A3B-Instruct-FP8
canonical_url: "https://www.modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct-FP8"
md_url: "https://www.modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct-FP8.md"
repository: Qwen/Qwen3-Coder-30B-A3B-Instruct-FP8
chinese_name: "千问3-Coder-30B-A3B-Instruct-FP8"
last_updated: 2025-12-03
license: apache-2.0
pipeline_tag: text-generation
tasks:
- text-generation
model_type:
- qwen3_moe
architectures:
- Qwen3MoeForCausalLM
parameters: 30.5B
tensor_type:
- F8_E4M3
- BF16
library_name:
- transformer
- safetensors
- pytorch
frameworks:
- Pytorch
inference_backends:
- "deploy_task text/emb"
- "lmdeploy_turbomind 0.9.1"
- "sglang 0.5.2"
- "vllm 0.9.2"
downloads: 1233025
stars: 25
---
# Qwen3-Coder-30B-A3B-Instruct-FP8
> Qwen3-Coder-30B-A3B-Instruct-FP8 - Qwen 在 ModelScope 开源的模型。Qwen3-Coder-30B-A3B-Instruct-FP8
Qwen/Qwen3-Coder-30B-A3B-Instruct-FP8 是 ModelScope 魔搭社区上的 30.5B 参数text-generation模型,采用 apache-2.0 许可,可用 deploy_task text/emb、lmdeploy_turbomind 0.9.1、sglang 0.5.2 部署。
- **Repository**: Qwen/Qwen3-Coder-30B-A3B-Instruct-FP8
- **License**: apache-2.0
- **Tasks**: text-generation
- **Parameters**: 30.5B
- **Inference backends**: deploy_task text/emb, lmdeploy_turbomind 0.9.1, sglang 0.5.2, vllm 0.9.2
- **Downloads**: 1233025
- **Stars**: 25
- **Last updated**: 2025-12-03
Source: https://www.modelscope.cn/models/Qwen/Qwen3-Coder-30B-A3B-Instruct-FP8
---
# Qwen3-Coder-30B-A3B-Instruct-FP8
 ## Highlights
**Qwen3-Coder** is available in multiple sizes. Today, we're excited to introduce **Qwen3-Coder-30B-A3B-Instruct-FP8**. This streamlined model maintains impressive performance and efficiency, featuring the following key enhancements:
- **Significant Performance** among open models on **Agentic Coding**, **Agentic Browser-Use**, and other foundational coding tasks.
- **Long-context Capabilities** with native support for **256K** tokens, extendable up to **1M** tokens using Yarn, optimized for repository-scale understanding.
- **Agentic Coding** supporting for most platform such as **Qwen Code**, **CLINE**, featuring a specially designed function call format.
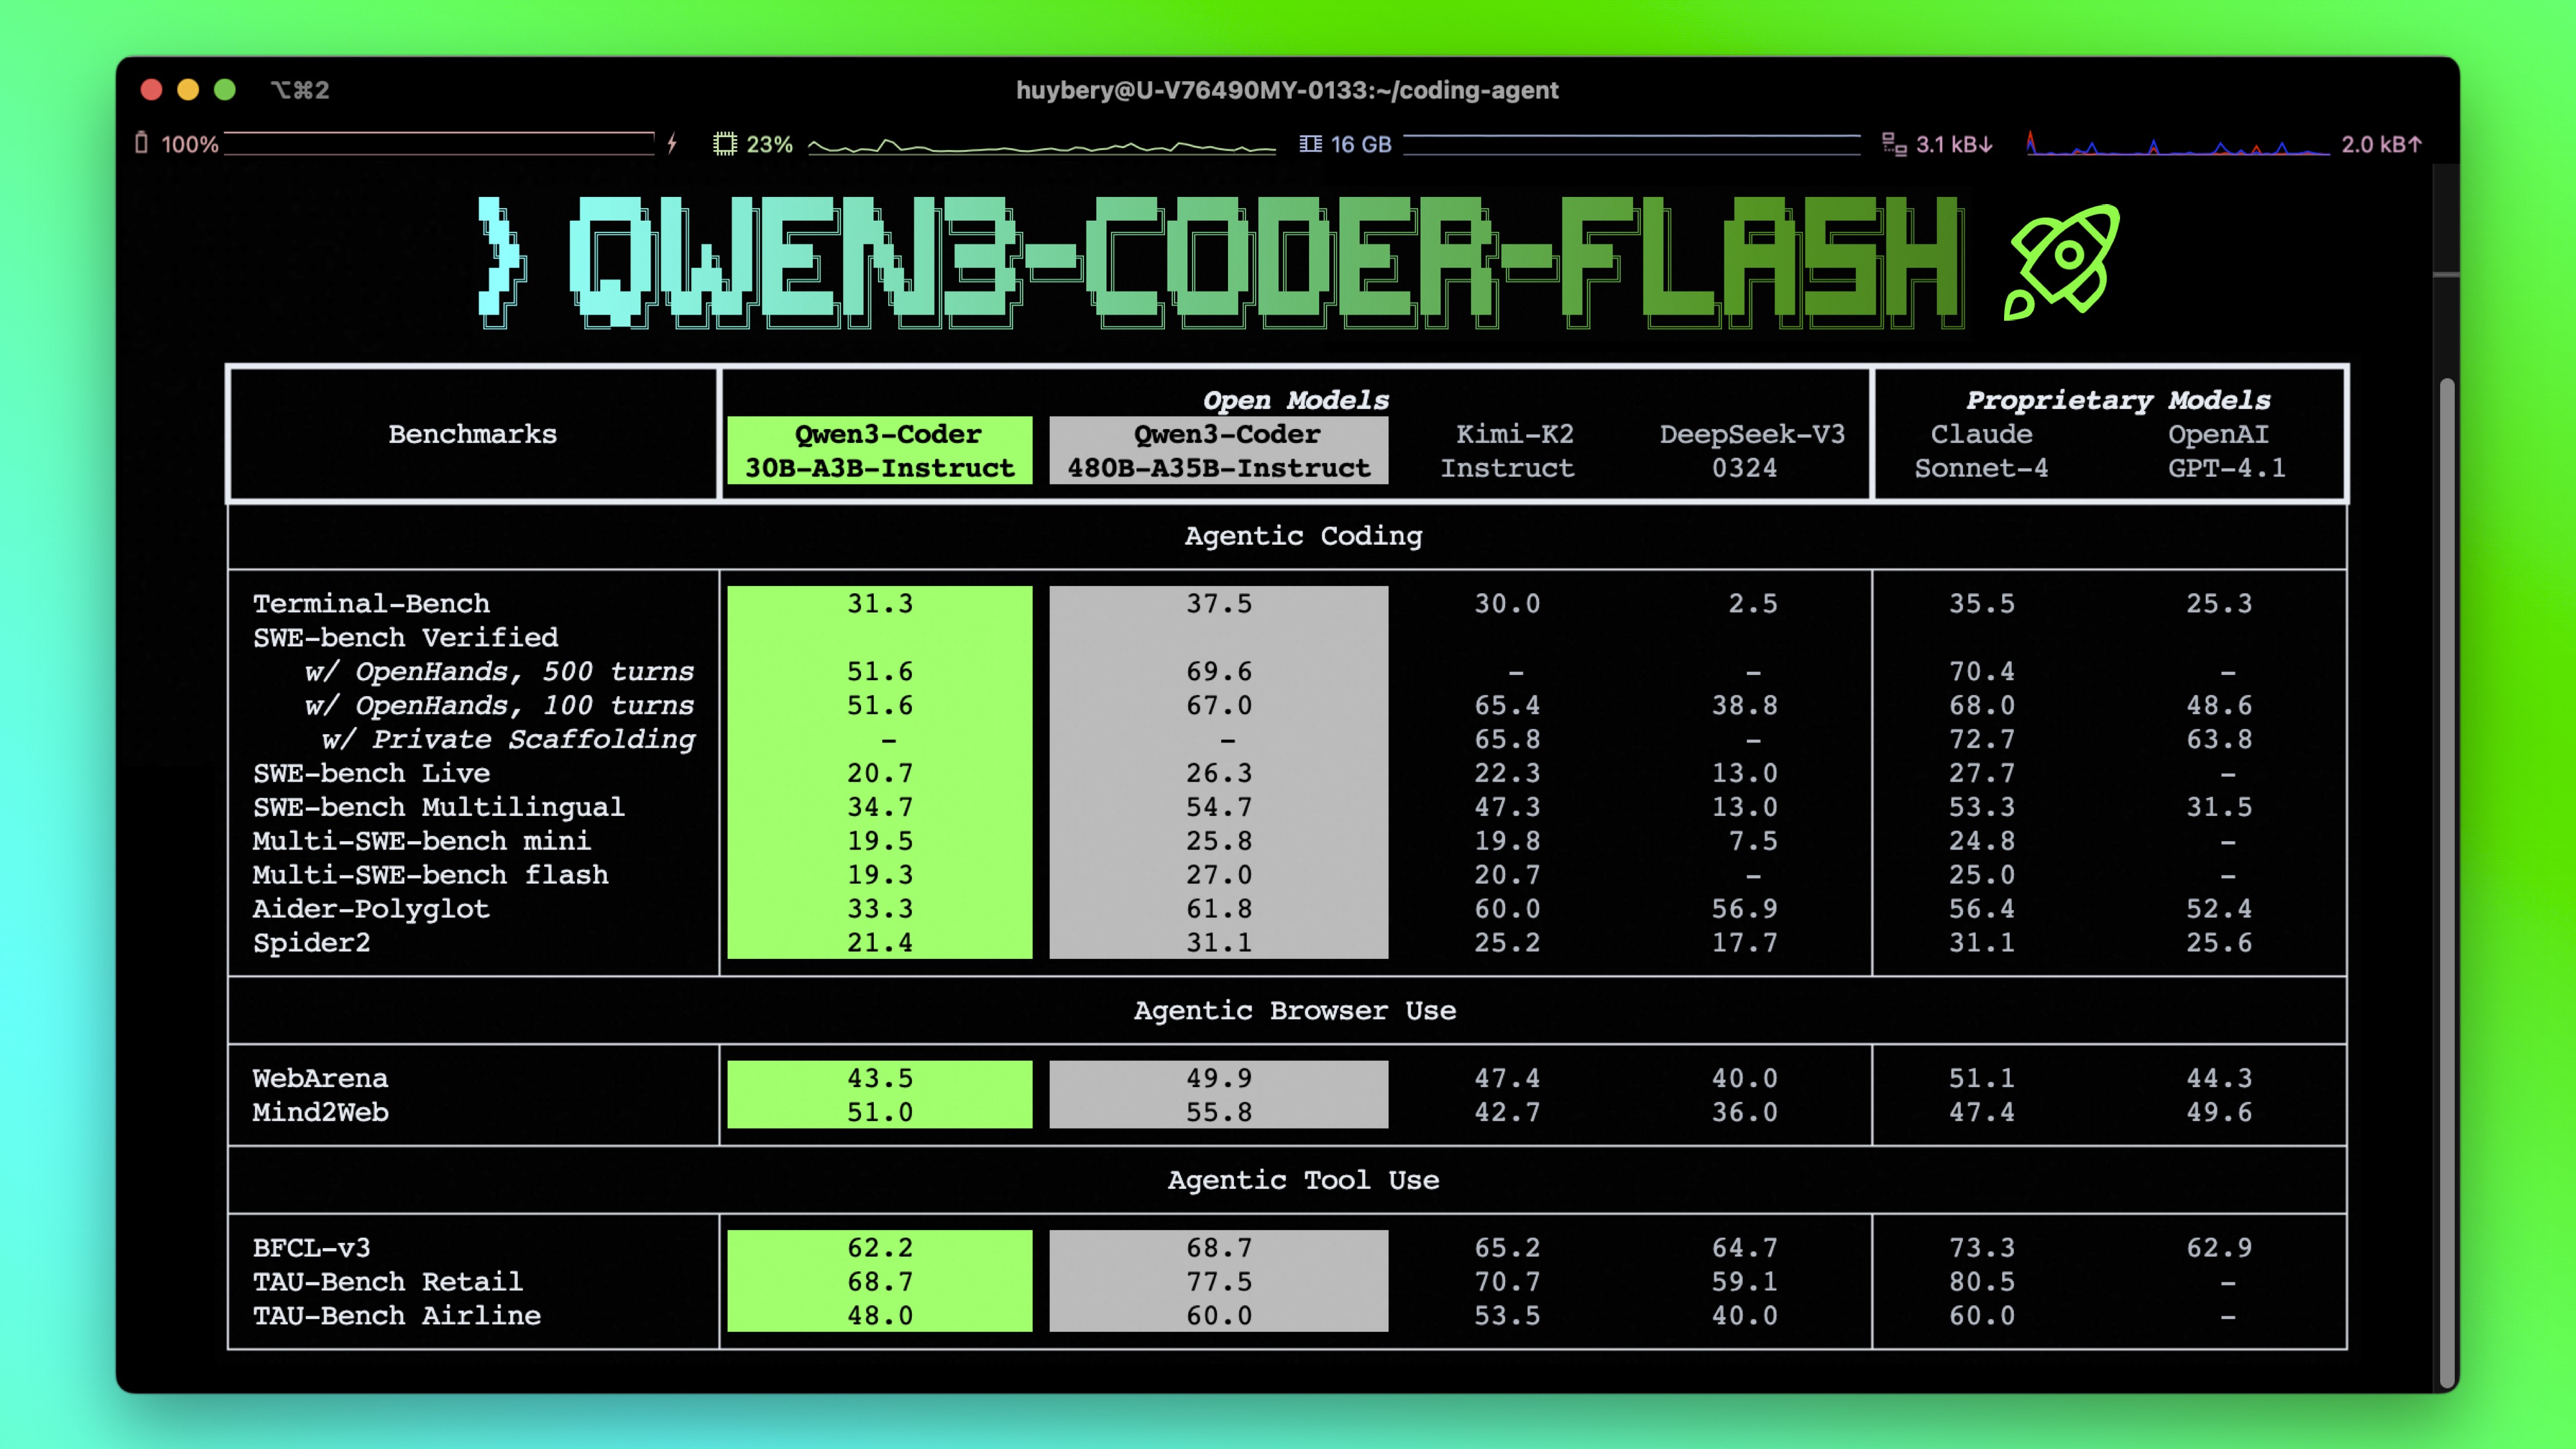
## Model Overview
**Qwen3-Coder-30B-A3B-Instruct-FP8** has the following features:
- Type: Causal Language Models
- Training Stage: Pretraining & Post-training
- Number of Parameters: 30.5B in total and 3.3B activated
- Number of Layers: 48
- Number of Attention Heads (GQA): 32 for Q and 4 for KV
- Number of Experts: 128
- Number of Activated Experts: 8
- Context Length: **262,144 natively**.
**NOTE: This model supports only non-thinking mode and does not generate ```` blocks in its output. Meanwhile, specifying `enable_thinking=False` is no longer required.**
For more details, including benchmark evaluation, hardware requirements, and inference performance, please refer to our [blog](https://qwenlm.github.io/blog/qwen3-coder/), [GitHub](https://github.com/QwenLM/Qwen3-Coder), and [Documentation](https://qwen.readthedocs.io/en/latest/).
## Quickstart
We advise you to use the latest version of `transformers`.
With `transformers<4.51.0`, you will encounter the following error:
```
KeyError: 'qwen3_moe'
```
The following contains a code snippet illustrating how to use the model generate content based on given inputs.
```python
from transformers import AutoModelForCausalLM, AutoTokenizer
model_name = "Qwen/Qwen3-Coder-30B-A3B-Instruct-FP8"
# load the tokenizer and the model
tokenizer = AutoTokenizer.from_pretrained(model_name)
model = AutoModelForCausalLM.from_pretrained(
model_name,
torch_dtype="auto",
device_map="auto"
)
# prepare the model input
prompt = "Write a quick sort algorithm."
messages = [
{"role": "user", "content": prompt}
]
text = tokenizer.apply_chat_template(
messages,
tokenize=False,
add_generation_prompt=True,
)
model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
# conduct text completion
generated_ids = model.generate(
**model_inputs,
max_new_tokens=65536
)
output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
content = tokenizer.decode(output_ids, skip_special_tokens=True)
print("content:", content)
```
**Note: If you encounter out-of-memory (OOM) issues, consider reducing the context length to a shorter value, such as `32,768`.**
## Note on FP8
For convenience and performance, we have provided `fp8`-quantized model checkpoint for Qwen3, whose name ends with `-FP8`. The quantization method is fine-grained `fp8` quantization with block size of 128. You can find more details in the `quantization_config` field in `config.json`.
You can use the Qwen3-30B-A3B-Instruct-FP8 model with serveral inference frameworks, including `transformers`, `sglang`, and `vllm`, as the original bfloat16 model.
However, please pay attention to the following known issues:
- `transformers`:
- there are currently issues with the "fine-grained fp8" method in `transformers` for distributed inference. You may need to set the environment variable `CUDA_LAUNCH_BLOCKING=1` if multiple devices are used in inference.
## Agentic Coding
Qwen3-Coder excels in tool calling capabilities.
You can simply define or use any tools as following example.
```python
# Your tool implementation
def square_the_number(num: float) -> dict:
return num ** 2
# Define Tools
tools=[
{
"type":"function",
"function":{
"name": "square_the_number",
"description": "output the square of the number.",
"parameters": {
"type": "object",
"required": ["input_num"],
"properties": {
'input_num': {
'type': 'number',
'description': 'input_num is a number that will be squared'
}
},
}
}
}
]
import OpenAI
# Define LLM
client = OpenAI(
# Use a custom endpoint compatible with OpenAI API
base_url='http://localhost:8000/v1', # api_base
api_key="EMPTY"
)
messages = [{'role': 'user', 'content': 'square the number 1024'}]
completion = client.chat.completions.create(
messages=messages,
model="Qwen3-Coder-30B-A3B-Instruct-FP8",
max_tokens=65536,
tools=tools,
)
print(completion.choice[0])
```
## Best Practices
To achieve optimal performance, we recommend the following settings:
1. **Sampling Parameters**:
- We suggest using `temperature=0.7`, `top_p=0.8`, `top_k=20`, `repetition_penalty=1.05`.
2. **Adequate Output Length**: We recommend using an output length of 65,536 tokens for most queries, which is adequate for instruct models.
### Citation
If you find our work helpful, feel free to give us a cite.
```
@misc{qwen3technicalreport,
title={Qwen3 Technical Report},
author={Qwen Team},
year={2025},
eprint={2505.09388},
archivePrefix={arXiv},
primaryClass={cs.CL},
url={https://arxiv.org/abs/2505.09388},
}
```