---
title: MiniCPM-V-4.7-1B
canonical_url: "https://www.modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B"
md_url: "https://www.modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B.md"
repository: OpenBMB/MiniCPM-V-4.7-1B
last_updated: 2026-10-12
license: apache-2.0
pipeline_tag: image-text-to-text
tasks:
- image-text-to-text
model_type:
- minicpmv4_7
architectures:
- MiniCPMV4_7ForConditionalGeneration
parameters: 1.6B
tensor_type:
- BF16
library_name:
- pytorch
- transformer
- safetensors
downloads: 14
stars: 0
tags:
- minicpm-v
- multimodal
- "On-Device Model"
- lightweight
---
# MiniCPM-V-4.7-1B
> MiniCPM-V-4.7-1B - OpenBMB 在 ModelScope 开源的模型。Evaluation · Examples · Usage · Model weights
OpenBMB/MiniCPM-V-4.7-1B 是 ModelScope 魔搭社区上的 1.6B 参数image-text-to-text模型,采用 apache-2.0 许可。
- **Repository**: OpenBMB/MiniCPM-V-4.7-1B
- **License**: apache-2.0
- **Tasks**: image-text-to-text
- **Parameters**: 1.6B
- **Tags**: minicpm-v, multimodal, On-Device Model, lightweight
- **Downloads**: 14
- **Stars**: 0
- **Last updated**: 2026-10-12
Source: https://www.modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B
---
# MiniCPM-V 4.7
[Evaluation](#evaluation) · [Examples](#examples) · [Usage](#usages) · [Model weights](#model-weights)
**MiniCPM-V 4.7** is the latest model in the MiniCPM-V series, available in a **1B** variant. It builds on the family's single-image, multi-image, and video understanding capabilities, combining stronger foundation capabilities with efficient visual encoding and on-device inference. Notable features of MiniCPM-V 4.7 include:
- 🔥 **A New Pareto Frontier in Performance and Efficiency.**
As model capabilities continue to advance, inference efficiency has become an important measure of a model's value. On resource-constrained devices, delivering the strongest possible capabilities within a limited resource budget calls for higher capability density. The **1B** variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier for MLLMs. In Instruct mode, the 1B variant continues to improve foundation capabilities over MiniCPM-V 4.6 and **substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency**.
- 🚀 **Efficient Architecture.**
Based on the intra-ViT early compression technique from [LLaVA-UHD v4](https://github.com/THUMAI-Lab/LLaVA-UHD-v4), MiniCPM-V 4.7 compresses visual tokens early within the vision encoder, reducing computation in subsequent encoder layers. It also supports **mixed 4x/16x visual token compression**, allowing developers to balance visual detail and inference cost across tasks.
- 💻 **Broad Platform and Chip Support.**
MiniCPM-V 4.7 supports **iOS, Android, and HarmonyOS**, together with open-source on-device deployment support. It also provides **day-0 support for chip platforms from Rockchip, Houmo, Intel, AMD, and Arm**, extending deployment options across mobile and local computing devices.
- 🛠️ **Developer Friendly.**
MiniCPM-V 4.7 supports [inference frameworks](https://github.com/OpenBMB/MiniCPM-o/blob/main/docs/deployment_en.md#supported-inference-and-training-frameworks-and-api) including SGLang, vLLM, llama.cpp, and Ollama, along with [fine-tuning frameworks](https://github.com/OpenBMB/MiniCPM-o/blob/main/docs/deployment_en.md#supported-inference-and-training-frameworks-and-api) including SWIFT and LLaMA-Factory. It provides GGUF, BNB, AWQ, and GPTQ quantized variants and adds **FP8 quantization support**. We also release **Self-Replay Fine-Tuning**, a fine-tuning approach that helps developers extend model capabilities at low cost while reducing forgetting of existing capabilities, making further customization easier.
## Get started
Model weights ·
Inference ·
Fine-tuning ·
Live demo ·
Local deployment ·
API ·
Cookbook
### Evaluation
**Significantly Advancing the Performance–Efficiency Pareto Frontier**
The 1B variant of MiniCPM-V 4.7 advances the performance–efficiency Pareto frontier. In Instruct mode, 1B substantially outperforms Qwen3.5 0.8B in both overall score and inference efficiency.
**Overall Performance (1B, Instruct)**
### Examples
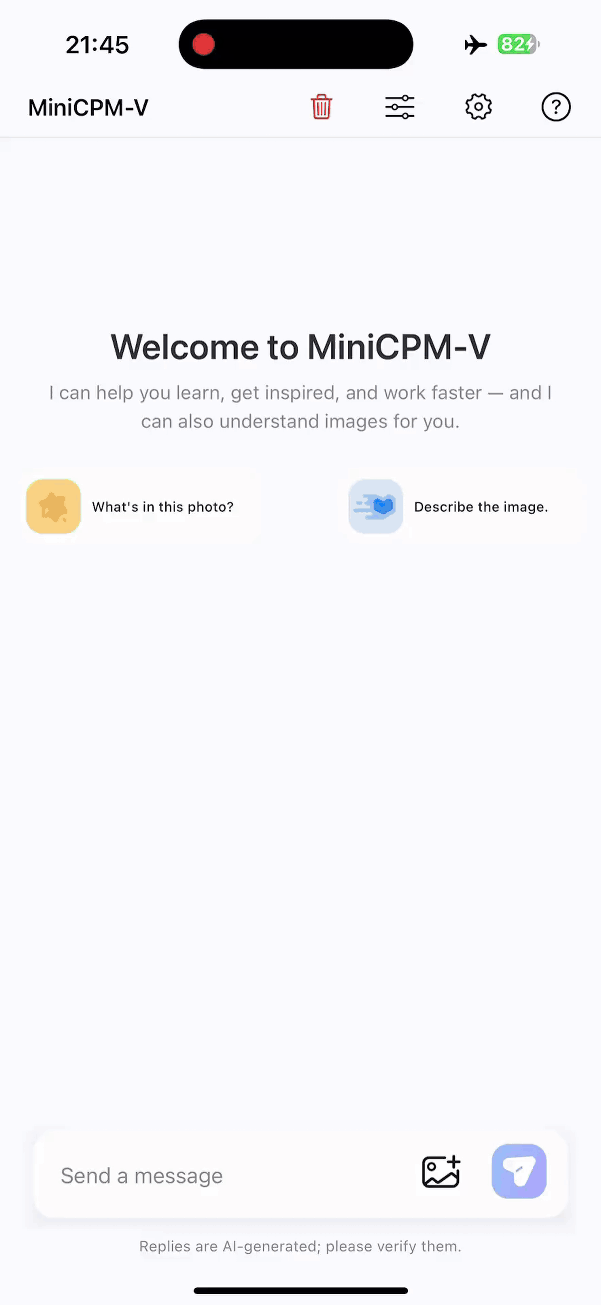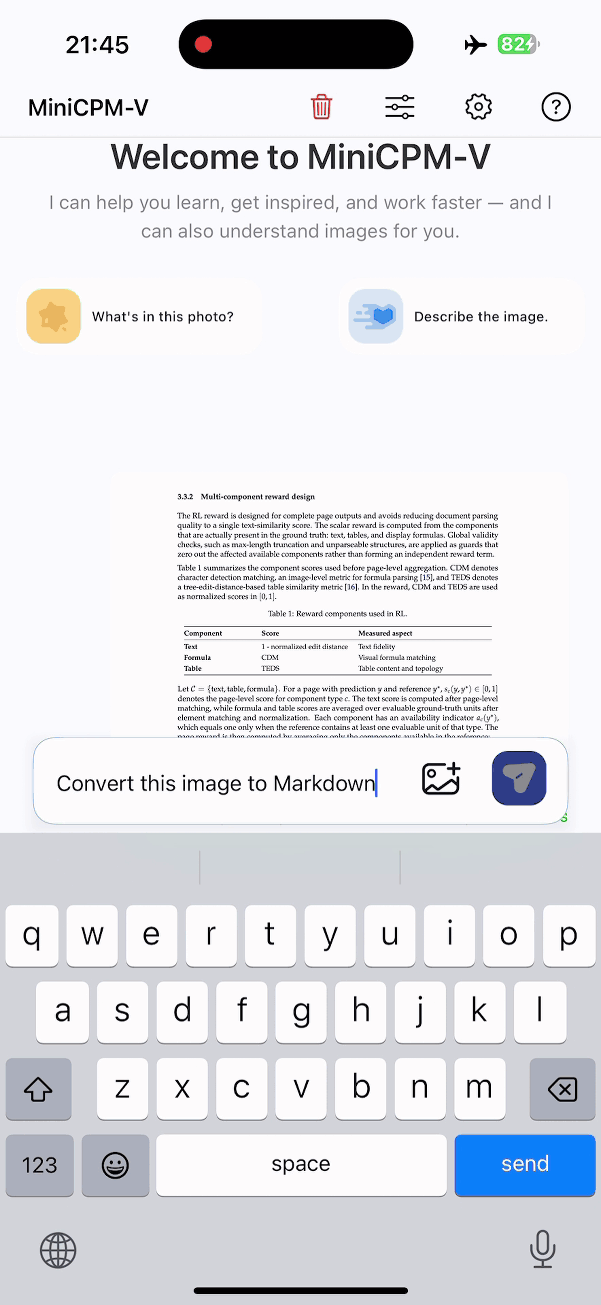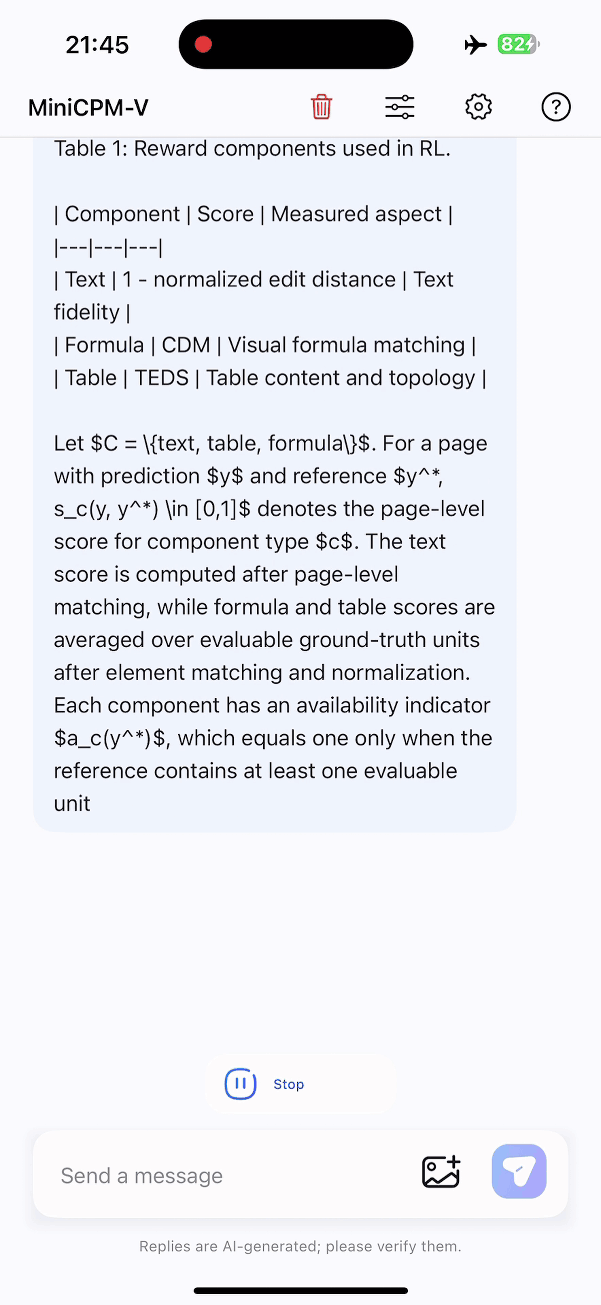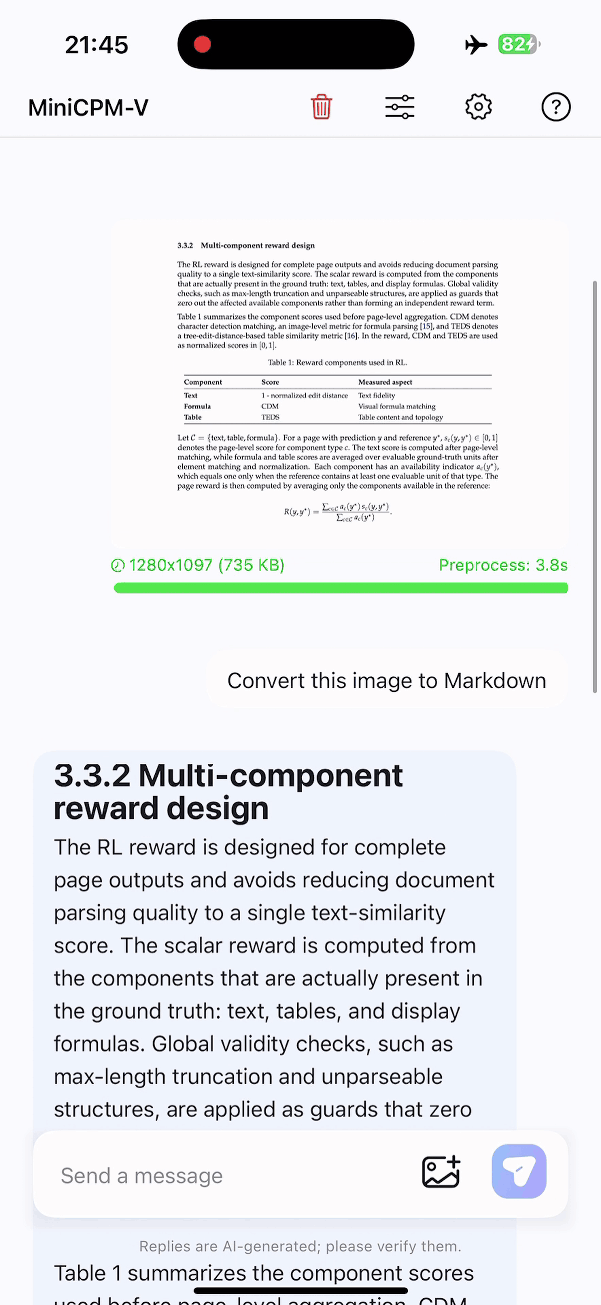
MiniCPM-V 4.7 can run on phones and tablets. The clips below are unedited screen recordings captured directly on the devices.
1B
iPhone 17 Pro Max |
 |
### Usages
#### Inference with Transformers
Click to expand the Transformers inference examples.
##### Installation
```bash
pip install "transformers[torch]>=5.18.0" torchvision torchcodec
```
> **Note on CUDA compatibility:** `torchcodec` (used for video decoding) may have compatibility issues with certain CUDA versions. For example, `torch>=2.11` bundles CUDA 13.1 by default, while environments with CUDA 12.x may encounter errors such as `RuntimeError: Could not load libtorchcodec`. Two workarounds:
>
> 1. **Replace `torchcodec` with `PyAV`** — supports both image and video inference without CUDA version constraints:
> ```bash
> pip install "transformers[torch]>=5.18.0" torchvision av
> ```
> 2. **Pin the CUDA version** when installing torch to match your environment (e.g. CUDA 12.8):
> ```bash
> pip install "transformers>=5.18.0" torchvision torchcodec --index-url https://download.pytorch.org/whl/cu128
> ```
##### Load the Model
```python
import torch
from transformers import AutoModelForImageTextToText, AutoProcessor
model_id = "openbmb/MiniCPM-V-4.7-1B"
processor = AutoProcessor.from_pretrained(model_id)
model = AutoModelForImageTextToText.from_pretrained(
model_id, torch_dtype="auto", device_map="auto"
)
# Flash Attention 2 is recommended for faster inference and lower GPU memory usage,
# especially in multi-image and video scenarios.
# model = AutoModelForImageTextToText.from_pretrained(
# model_id,
# torch_dtype=torch.bfloat16,
# attn_implementation="flash_attention_2",
# device_map="auto",
# )
```
##### Image Inference
```python
messages = [
{
"role": "user",
"content": [
{"type": "image", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"},
{"type": "text", "text": "What causes this phenomenon?"},
],
}
]
downsample_mode = "16x" # Using `downsample_mode="4x"` for Finer Detail
inputs = processor.apply_chat_template(
messages, tokenize=True, add_generation_prompt=True,
return_dict=True, return_tensors="pt",
downsample_mode=downsample_mode,
max_slice_nums=36,
enable_thinking=False,
).to(model.device)
generated_ids = model.generate(**inputs, downsample_mode=downsample_mode, max_new_tokens=512)
generated_ids_trimmed = [
out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
```
##### Video Inference
```python
messages = [
{
"role": "user",
"content": [
{"type": "video", "url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/football.mp4"},
{"type": "text", "text": "Describe this video in detail. Follow the timeline and focus on on-screen text, interface changes, main actions, and scene changes."},
],
}
]
downsample_mode = "16x" # Using `downsample_mode="4x"` for Finer Detail
inputs = processor.apply_chat_template(
messages, tokenize=True, add_generation_prompt=True,
return_dict=True, return_tensors="pt",
downsample_mode=downsample_mode,
max_num_frames=128,
stack_frames=1,
max_slice_nums=1,
use_image_id=False,
enable_thinking=False,
).to(model.device)
generated_ids = model.generate(**inputs, downsample_mode=downsample_mode, max_new_tokens=2048)
generated_ids_trimmed = [
out_ids[len(in_ids):] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
]
output_text = processor.batch_decode(
generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
)
print(output_text[0])
```
##### Advanced Parameters
You can customize image/video processing by passing additional parameters to `apply_chat_template`:
| Parameter | Default | Applies to | Description |
|-----------|---------|------------|-------------|
| `downsample_mode` | `"16x"` | Image & Video | Visual token downsampling. `"16x"` merges tokens for efficiency; `"4x"` keeps four times as many tokens for finer detail. **Must also be passed to `generate()`**. |
| `max_slice_nums` | `9` | Image & Video | Maximum number of slices when splitting a high-resolution image. Higher values preserve more detail for large images. Recommended: `36` for image, `1` for video. |
| `max_num_frames` | `128` | Video only | Maximum number of main frames sampled from the video. |
| `stack_frames` | `1` | Video only | Total sample points per second. `1` = main frame only (no stacking). `N` (N>1) = 1 main frame + N−1 sub-frames per second; the sub-frames are composited into a grid image and interleaved with main frames. Recommended: `3` or `5`. |
| `use_image_id` | `True` | Image & Video | Whether to prepend `N` tags before each image/frame placeholder. Recommended: `True` for image, `False` for video. |
> **Note:** `downsample_mode` must be passed to **both** `apply_chat_template` (for correct placeholder count) and `generate` (for the vision encoder). All other parameters only need to be passed to `apply_chat_template`.
##### Serving with `transformers serve`
Hugging Face Transformers includes a lightweight OpenAI-compatible server for quick testing and moderate-load deployment.
```bash
pip install "transformers[serving]>=5.18.0"
```
Start the server:
```bash
transformers serve openbmb/MiniCPM-V-4.7-1B --port 8000 --host 0.0.0.0
```
Send a request:
```bash
curl -s http://localhost:8000/v1/chat/completions \
-H 'Content-Type: application/json' \
-d '{
"model": "openbmb/MiniCPM-V-4.7-1B",
"messages": [{
"role": "user",
"content": [
{"type": "image_url", "image_url": {"url": "https://huggingface.co/datasets/openbmb/DemoCase/resolve/main/refract.png"}},
{"type": "text", "text": "What causes this phenomenon?"}
]
}]
}'
```
Tool calling example:
```bash
curl -s http://localhost:8000/v1/chat/completions -H 'Content-Type: application/json' -d '{
"model": "openbmb/MiniCPM-V-4.7-1B",
"messages": [{"role": "user", "content": [
{"type": "text", "text": "the weather of Beijing"}
]}],
"tools": [{
"type": "function",
"function": {
"name": "get_weather",
"description": "Get the current weather for a given location",
"parameters": {
"type": "object",
"properties": {
"location": {"type": "string", "description": "City name"}
},
"required": ["location"]
}
}
}]
}'
```
#### Speculative decoding (DSpark)
Click to show speculative decoding.
Speculative decoding (DSpark): we also release [MiniCPM-V-4.7-1B-DSpark](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B-DSpark), a DSpark draft model trained for [MiniCPM-V-4.7-1B](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B).
#### Inference with OpenVINO™
[OpenVINO™](https://docs.openvino.ai) is an open-source toolkit for optimizing and deploying AI inference on Intel CPU/GPU/NPU platforms. OpenVINO provides day-0 support for MiniCPM-V-4.7 on Intel platforms with high-performance inference. See the [OpenVINO™ Toolkit](https://github.com/openvinotoolkit) to get started. You can install and run the example with this notebook (link TBD).
#### On-Device Deployment
MiniCPM-V 4.7 supports deployment on iOS, Android, and HarmonyOS, with day-0 support for Rockchip, Houmo, Intel, AMD, and Arm chip platforms. See the [edge deployment repository](https://github.com/OpenBMB/MiniCPM-V-Apps) for the apps and source code.
#### Inference and Fine-Tuning
For supported inference and training frameworks, see [Supported Inference and Training Frameworks and API](https://github.com/OpenBMB/MiniCPM-o/blob/main/docs/deployment_en.md#supported-inference-and-training-frameworks-and-api). The [MiniCPM-V 4.7 Cookbook](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/docs/pages/v4.7/overview.md) covers deployment, fine-tuning, and quantization workflows.
**Task guides**
- [Single-image chat](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/inference/minicpm-v4_7_single_image.md)
- [Multi-image chat](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/inference/minicpm-v4_7_multi_images.md)
- [Video understanding](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/inference/minicpm-v4_7_video_understanding.md)
- [OCR](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/inference/minicpm-v4_7_ocr.md)
- [PDF parsing](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/inference/minicpm-v4_7_pdf_parse.md)
- [Visual grounding](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/inference/minicpm-v4_7_grounding.md)
**Quantization**
| Method | Guide |
|:---|:---|
| GGUF | [Quantization guide](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/quantization/gguf/minicpm-v4_7_gguf_quantize.md) |
| BNB | [Quantization guide](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/quantization/bnb/minicpm-v4_7_bnb_quantize.md) |
| AWQ | [Quantization guide](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/quantization/awq/minicpm-v4_7_awq_quantize.md) |
| GPTQ | [Quantization guide](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/quantization/gptq/minicpm-v4_7_gptq_quantize.md) |
| FP8 / INT4 | [Quantization guide](https://github.com/OpenSQZ/MiniCPM-V-CookBook/blob/main/quantization/llmcompressor/minicpm-v4_7_llmcompressor_quantize.md) |
### Acknowledgements
Click to view acknowledgements.
We would like to thank the following projects:
* [Qwen3.6](https://huggingface.co/collections/Qwen/qwen36) for providing the language backbone
* [SigLIP2](https://github.com/google-research/big_vision/blob/main/big_vision/configs/proj/image_text/README_siglip2.md) for providing the vision understanding module
* [Transformers](https://github.com/huggingface/transformers)
## Model Weights
MiniCPM-V 4.7 is available in the following variants:
| Model | Description | Download |
|:---|:---|:---:|
| MiniCPM-V 4.7 1B | Combines stronger capabilities with extremely high efficiency, advancing the performance–efficiency Pareto frontier for multimodal large language models. | [🤗](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B) [ ](https://modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B) |
| MiniCPM-V 4.7 1B int4 | bitsandbytes int4 quantized version with lower GPU memory usage. | [🤗](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B-int4) [](https://modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B-int4) |
| MiniCPM-V 4.7 1B AWQ | AWQ (W4A16) quantized version with lower GPU memory usage. | [🤗](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B-AWQ) [](https://modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B-AWQ) |
| MiniCPM-V 4.7 1B GPTQ | GPTQ (W4A16) quantized version with lower GPU memory usage. | [🤗](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B-GPTQ) [](https://modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B-GPTQ) |
| MiniCPM-V 4.7 1B GGUF | GGUF version with lower memory usage for CPU inference. | [🤗](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B-gguf) [](https://modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B-gguf) |
| MiniCPM-V 4.7 1B DSpark | DSpark draft model for speculative decoding. | [🤗](https://huggingface.co/openbmb/MiniCPM-V-4.7-1B-DSpark) [](https://modelscope.cn/models/OpenBMB/MiniCPM-V-4.7-1B-DSpark) |
Also available on [Ollama](https://ollama.com/openbmb/minicpm-v4.7).