---
title: MiniCPM-OCR-1.0
canonical_url: "https://www.modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0"
md_url: "https://www.modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0.md"
repository: OpenBMB/MiniCPM-OCR-1.0
last_updated: 2026-10-27
license: apache-2.0
pipeline_tag: image-text-to-text
tasks:
- image-text-to-text
model_type:
- minicpm_ocr
architectures:
- MiniCPMOcrForConditionalGeneration
parameters: 1.3B
tensor_type:
- BF16
library_name:
- safetensors
language:
- en
- zh
downloads: 16
stars: 0
tags:
- minicpm-ocr
- ocr
- document-parsing
- multimodal
- vision-language
- table-recognition
- formula-recognition
---
# MiniCPM-OCR-1.0
> MiniCPM-OCR-1.0 - OpenBMB 在 ModelScope 开源的模型。GitHub · API · Demo · DSpark
OpenBMB/MiniCPM-OCR-1.0 是 ModelScope 魔搭社区上的 1.3B 参数image-text-to-text模型,采用 apache-2.0 许可。
- **Repository**: OpenBMB/MiniCPM-OCR-1.0
- **License**: apache-2.0
- **Tasks**: image-text-to-text
- **Parameters**: 1.3B
- **Tags**: minicpm-ocr, ocr, document-parsing, multimodal, vision-language, table-recognition, formula-recognition
- **Downloads**: 16
- **Stars**: 0
- **Last updated**: 2026-10-27
Source: https://www.modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0
---
[GitHub](https://github.com/OpenBMB/MiniCPM-OCR) · [API](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_api_en.md) · [Demo](https://platform.modelbest.ai/console/playground/document-parse) · [DSpark](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark)
**MiniCPM-OCR 1.0** (1.3B) is the first OCR-specific model in the
[MiniCPM-V/o](https://github.com/openbmb/MiniCPM-V) family. It focuses on text-centric document
understanding — text, tables, formulas, charts, seals, and structured information extraction —
and balances quality against speed on real-world captures.
## Highlights
- 🏆 **SOTA document parsing**: **93.68 on Real5-OmniDocBench**, a benchmark for real-world
document parsing, with leading results on OmniDocBench v1.6, Wild-OmniDocBench, and
olmOCR-Bench. Handles Chinese and English documents and PDFs, including scans, curved pages,
photographs, skewed pages, and recaptured documents.
- ⚡ **Efficient inference.** With DSpark decoding acceleration
([BF16](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark), [GGUF](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark-gguf)) end-to-end
processing efficiency improves by **55%**. Throughput is about **1.49×** PaddleOCR-VL-1.6 and
**3.62×** MinerU2.5 Pro.
- 🔍 **General recognition and information extraction**: **54.7 on OCRBench v2**, plus key
information extraction (KIE) for downstream automation.
- 🛠️ **Easy to deploy and develop**: **vLLM, SGLang, llama.cpp, and Ollama from day one**, with
quantized variants and multi-chip builds. Supports further fine-tuning, and ships a pip SDK,
a full API, and agent workflows. Online demos: [China](https://platform.modelbest.cn/console/playground/document-parse) ·
[Global](https://platform.modelbest.ai/console/playground/document-parse).
## SOTA quality at higher throughput
Among the open-source OCR models compared, MiniCPM-OCR 1.0 reaches **1.2 pages/s** and the
highest equal-weight average score across OmniDocBench v1.6, Real5-OmniDocBench,
Wild-OmniDocBench, and olmOCR-Bench.
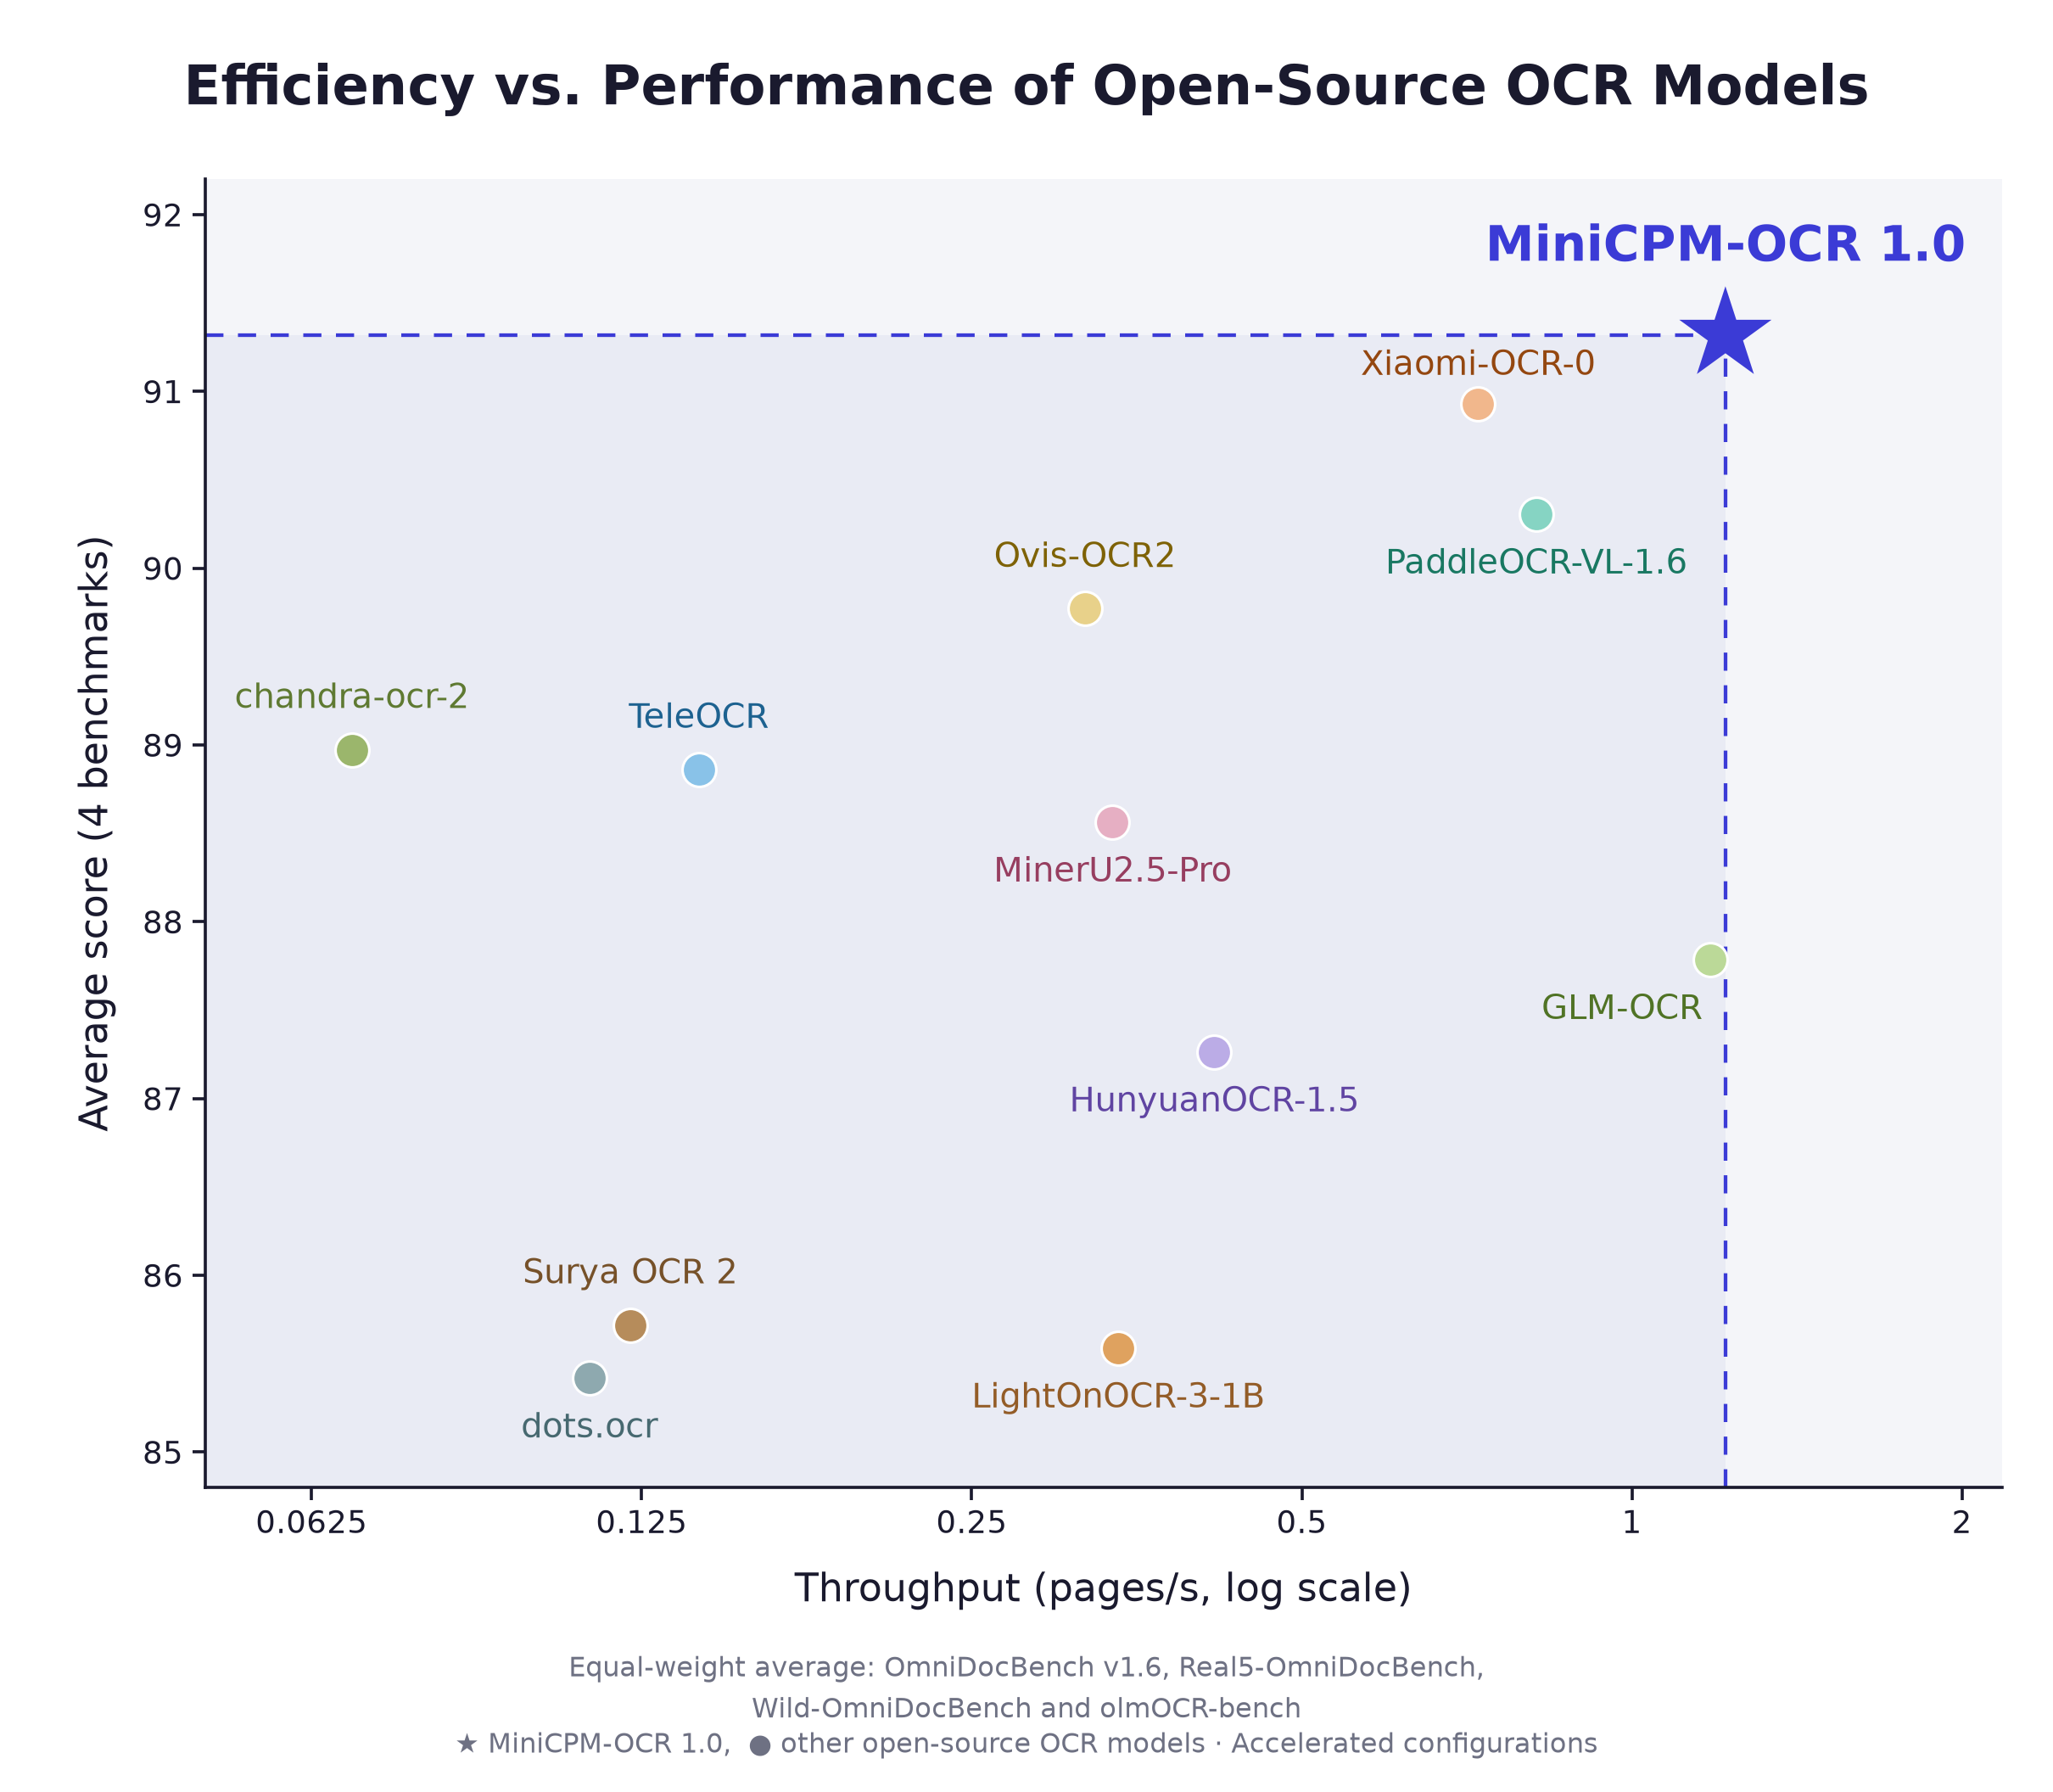
Average score is the equal-weight mean of the four benchmarks. All models use
accelerated configurations. Settings and reproduction: [reproduction guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/benchmark_reproduction_en.md).
Per-model throughput: [model guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_1dot0_en.md#throughput).
## Benchmark comparisons
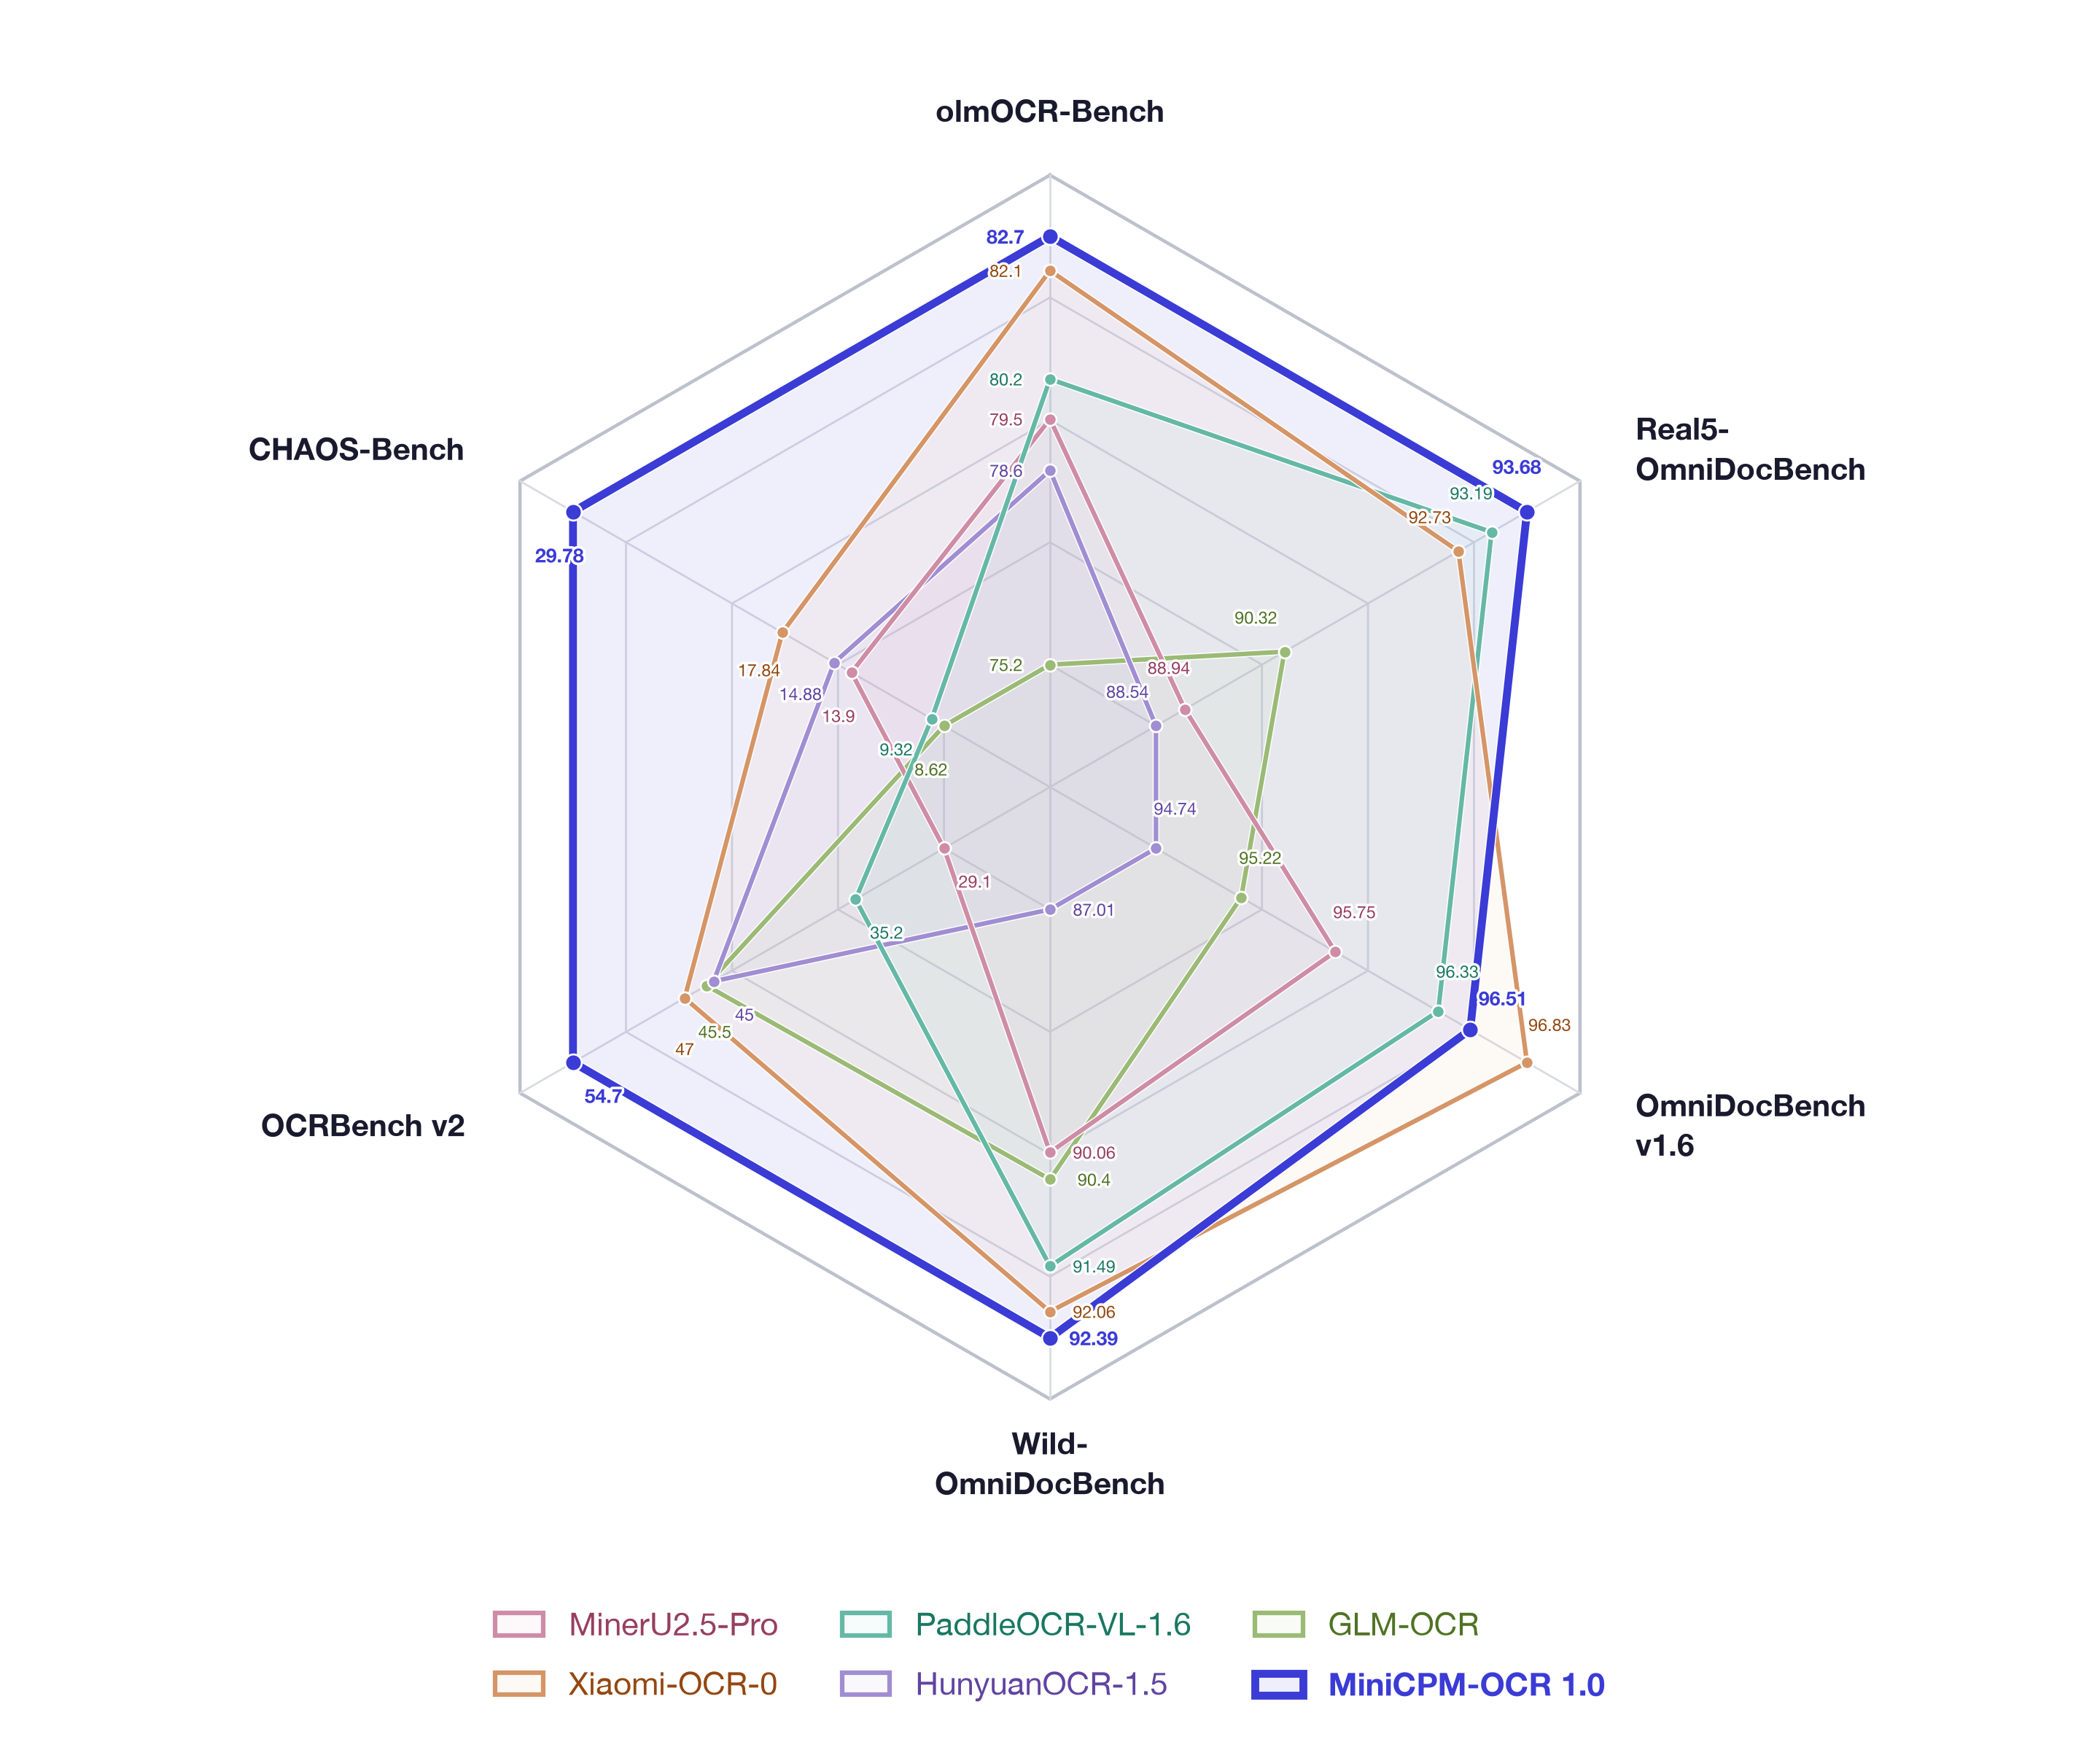
### Full MiniCPM-OCR 1.0 evaluation results
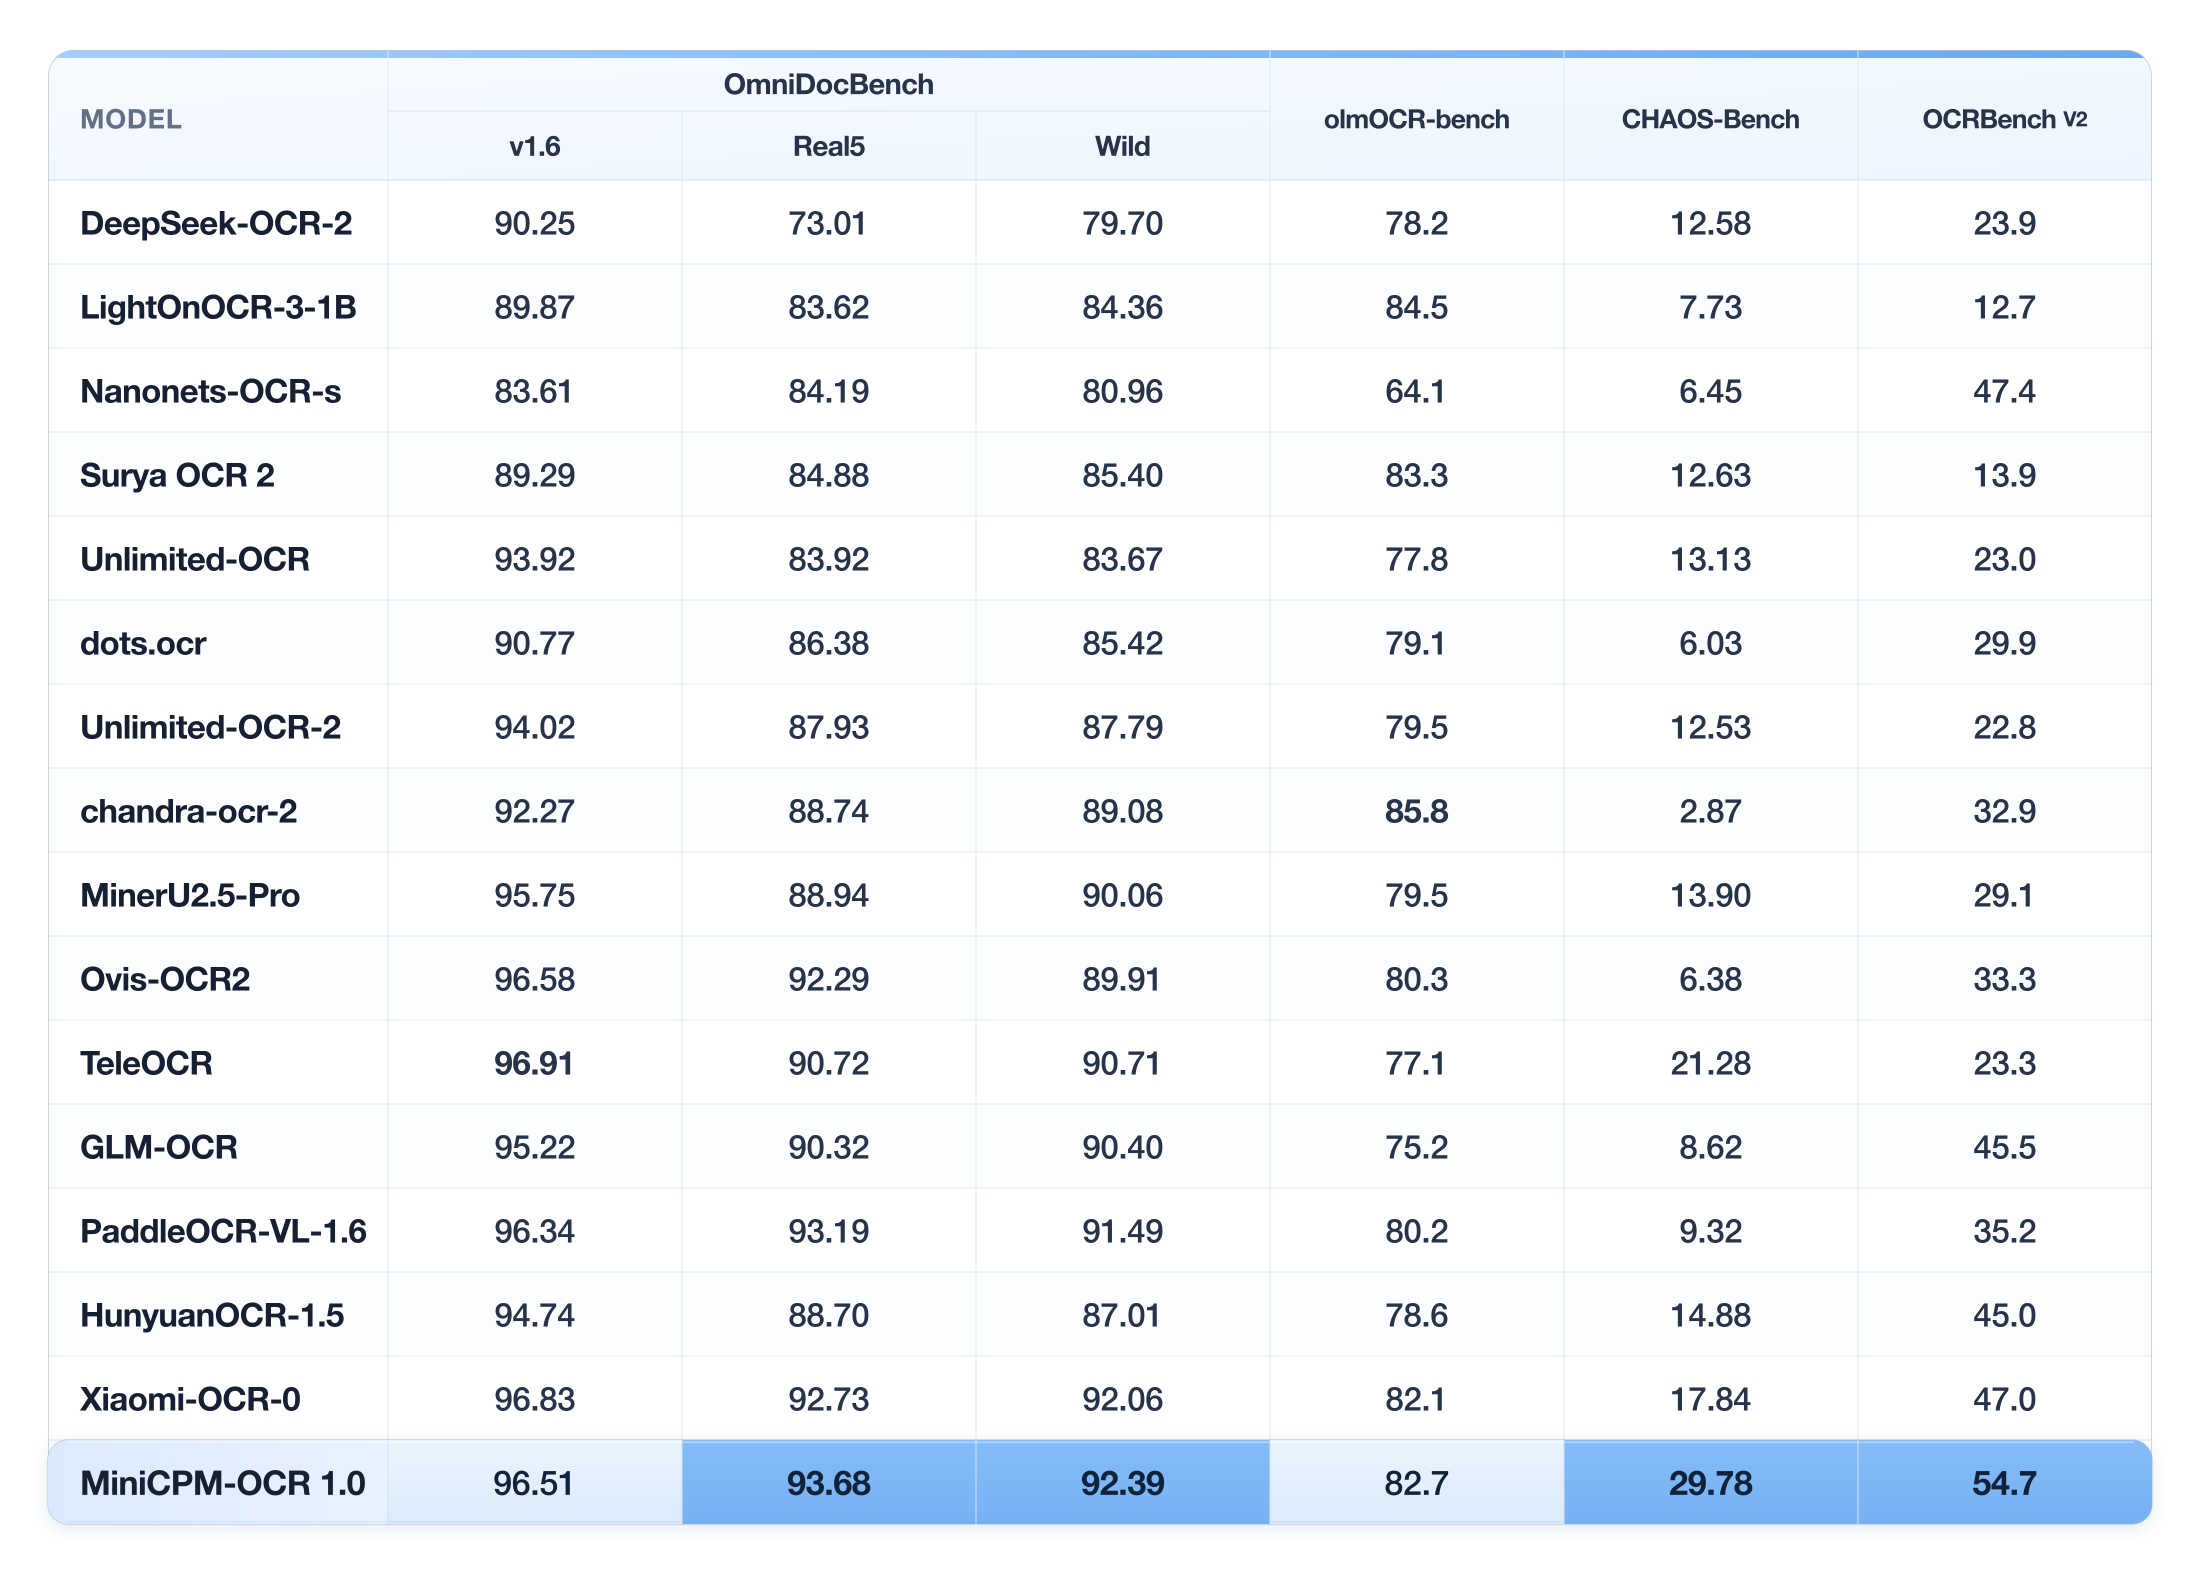
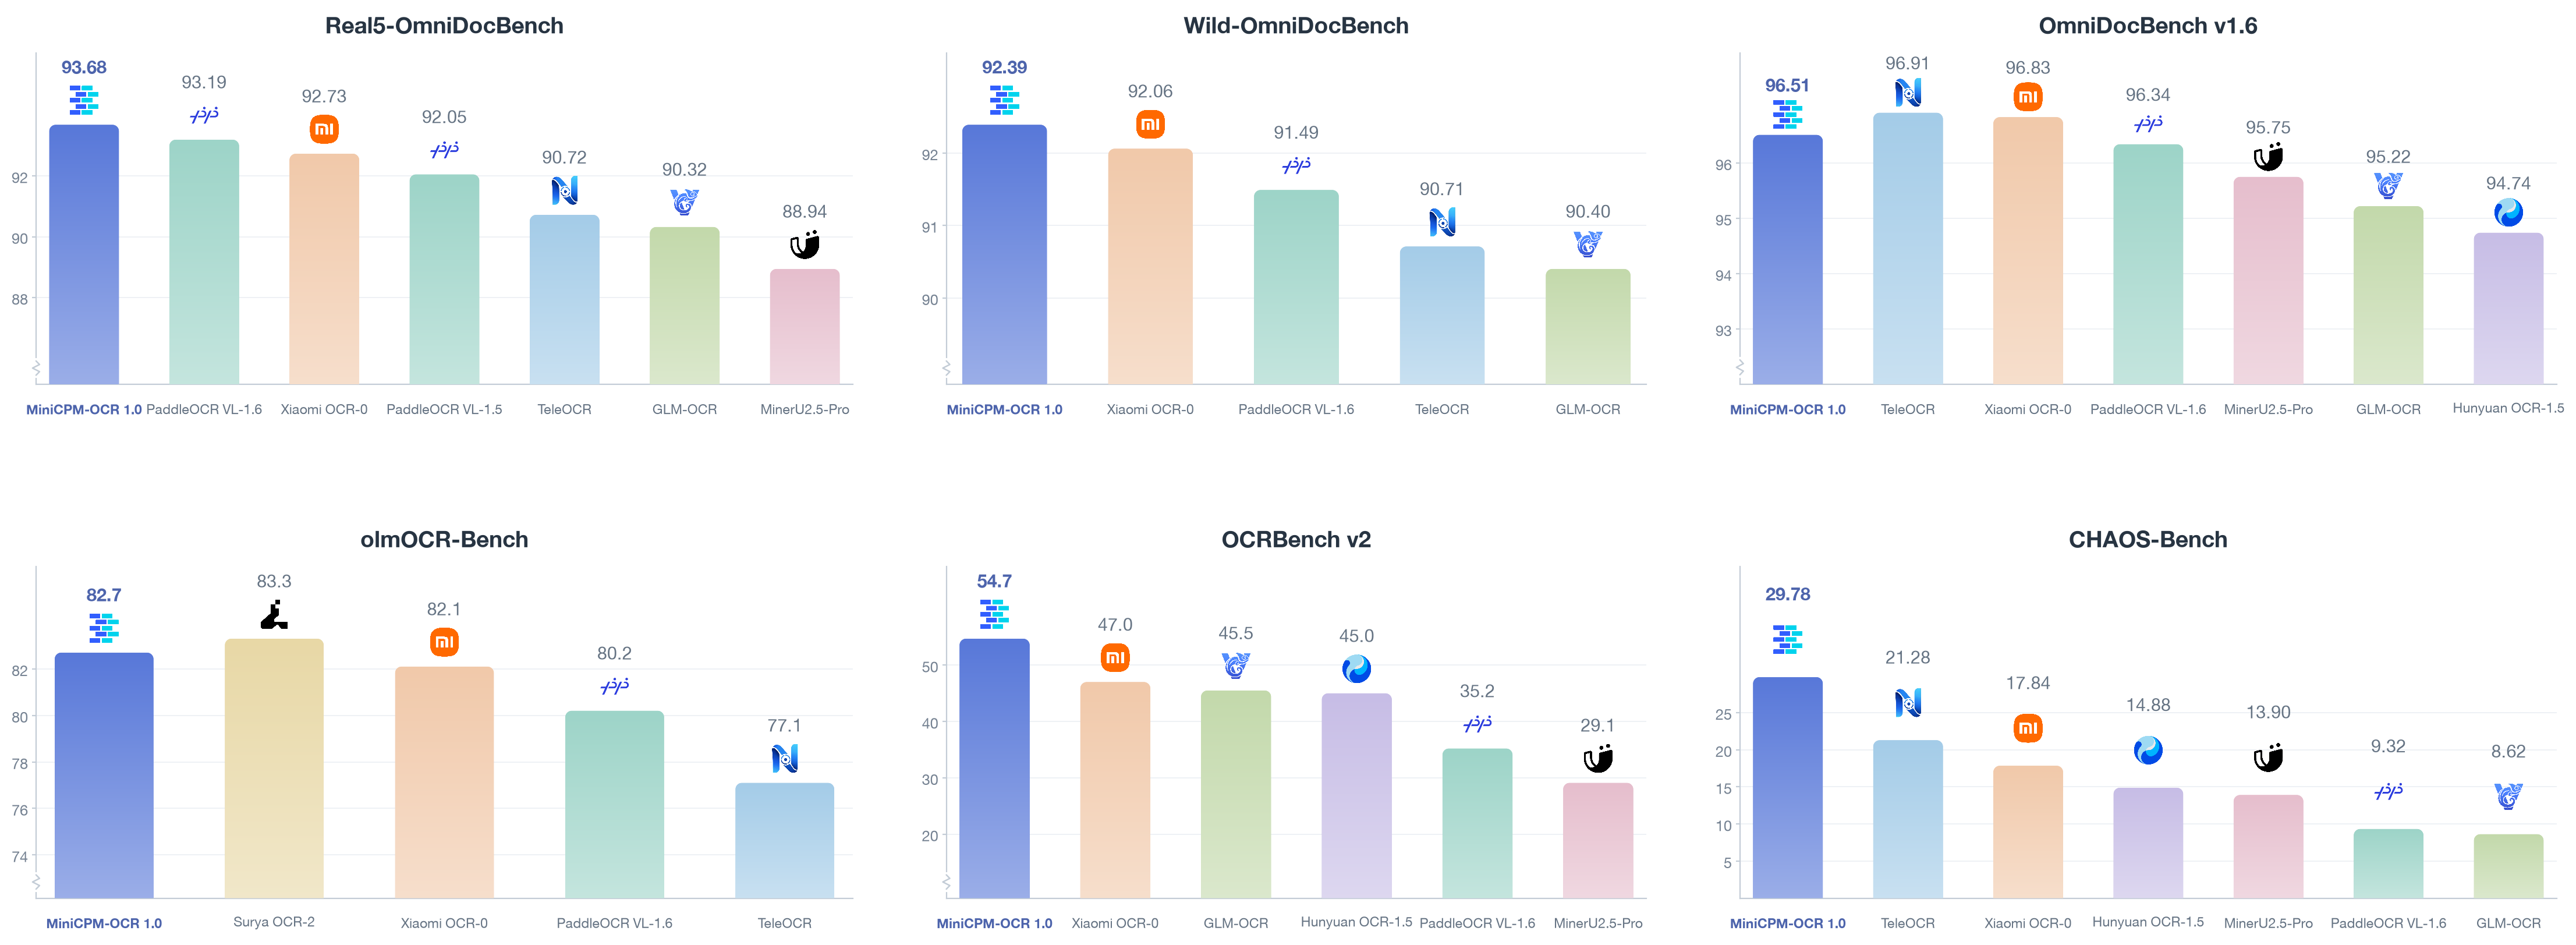
Each panel keeps its own benchmark's scores; higher is better. Scores from different
benchmarks are not directly comparable. Test settings and reproduction steps are in the
[reproduction guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/benchmark_reproduction_en.md); per-benchmark discussion is in the
[model guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_1dot0_en.md#evaluation).
### Throughput
On an NVIDIA GeForce RTX 5090 with all 1651 OmniDocBench v1.6 images, image-level concurrency 1,
and each system's accelerated configuration, MiniCPM-OCR 1.0 reaches **1.2 pages/s**
(relative throughput **1.00×**; higher is faster).
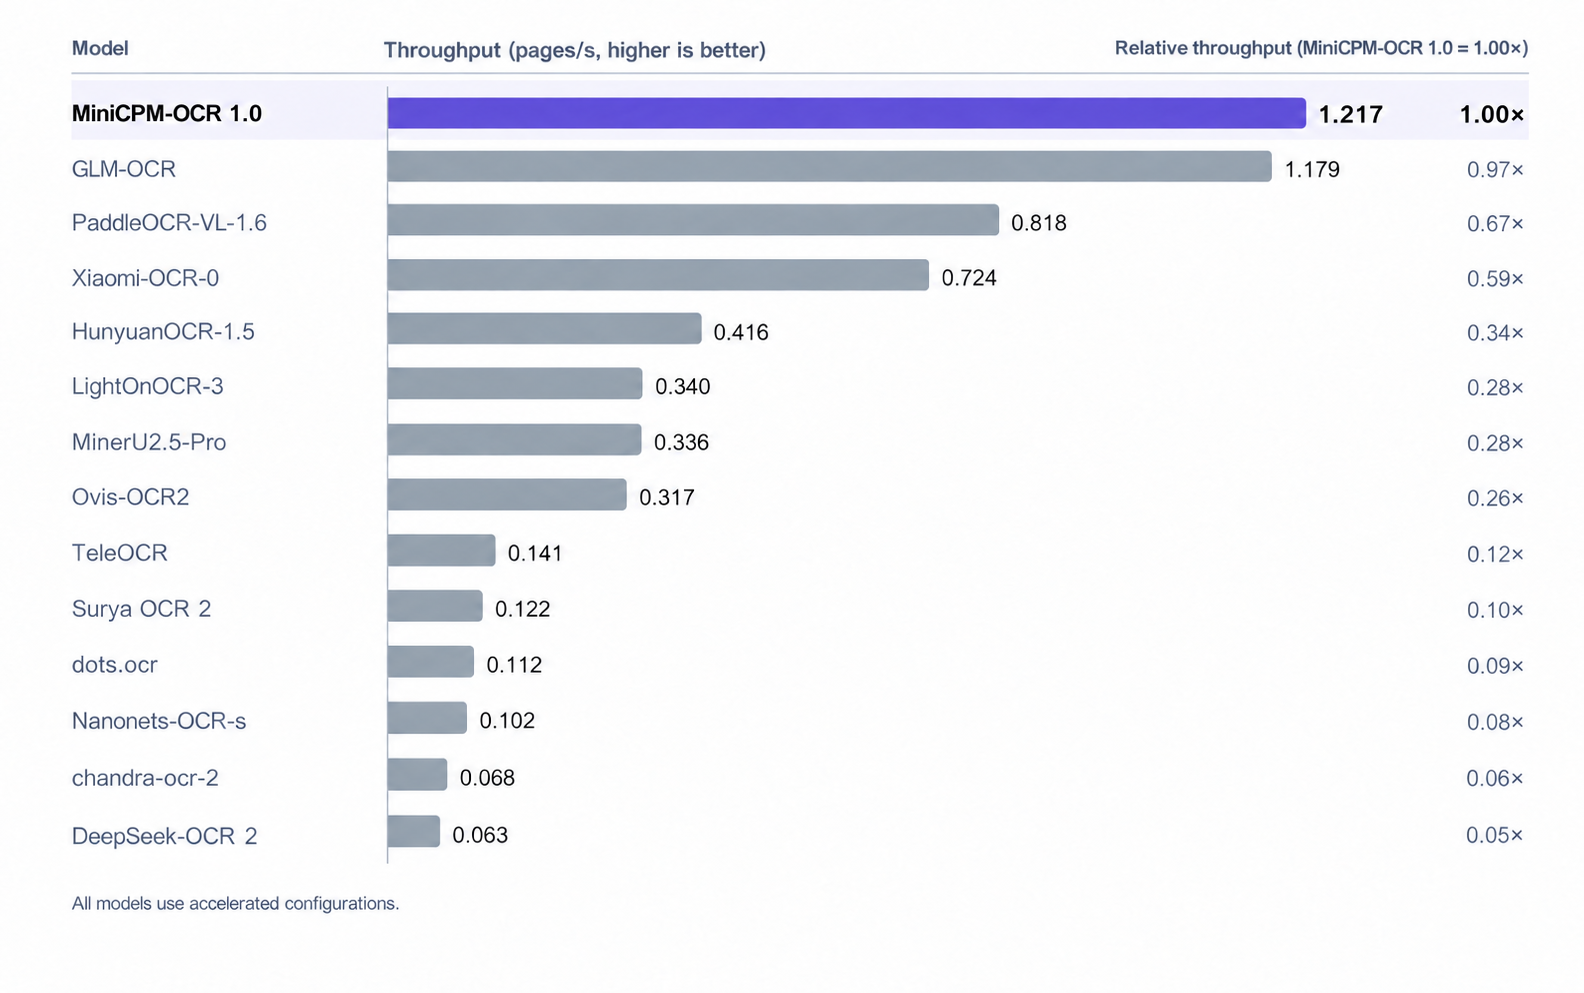
Concurrency 1 is image-level: regions inside a page are still recognised in parallel.
Real throughput also depends on page content, backend, concurrency, and hardware.
## Examples
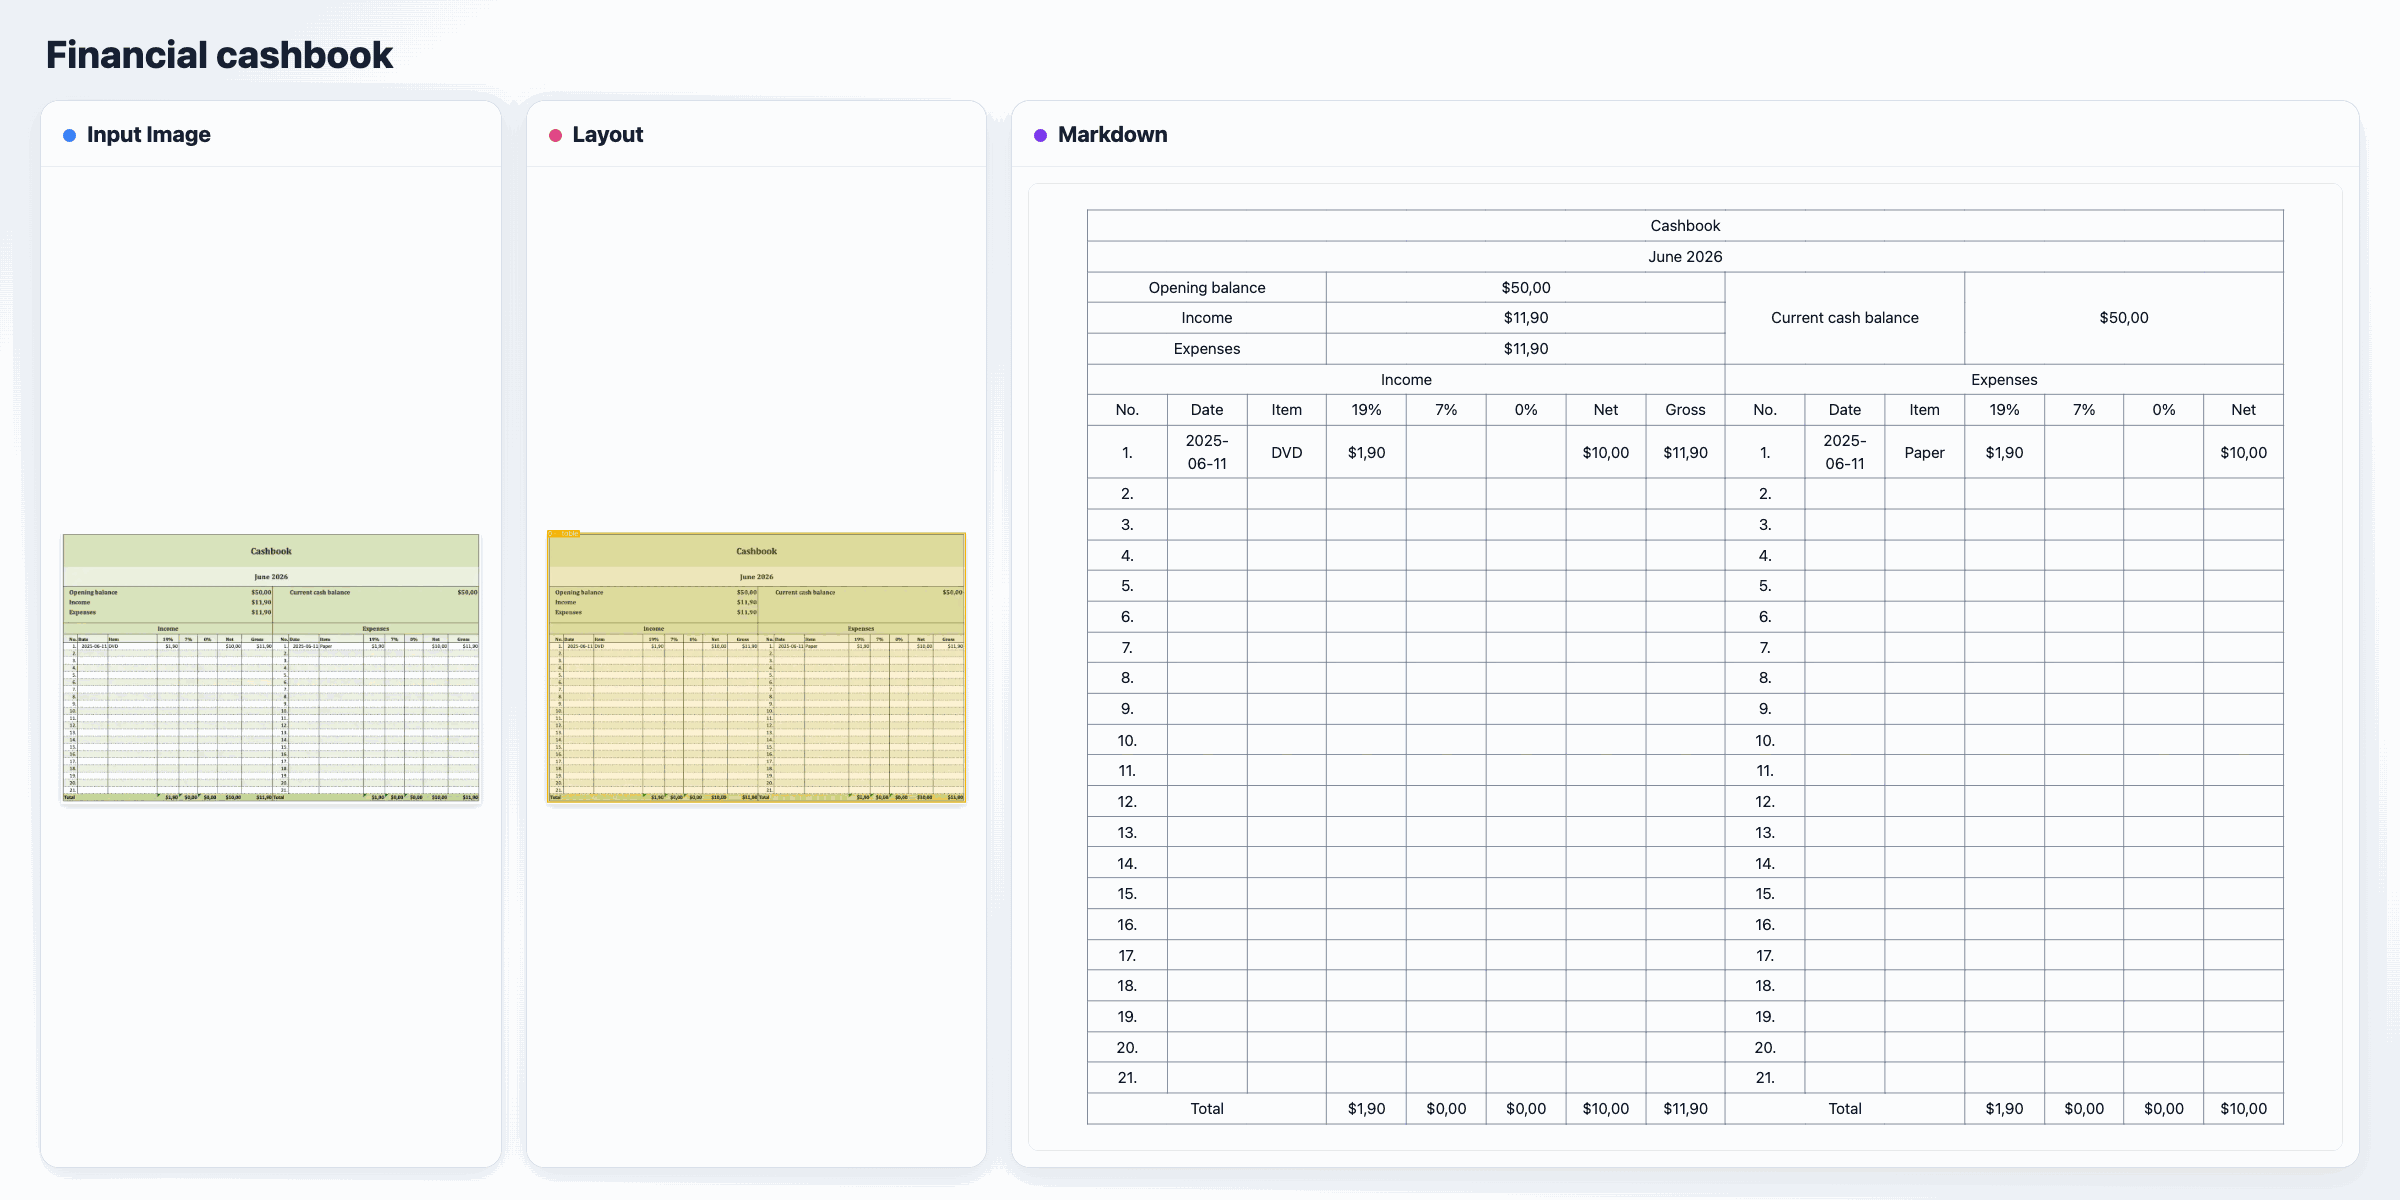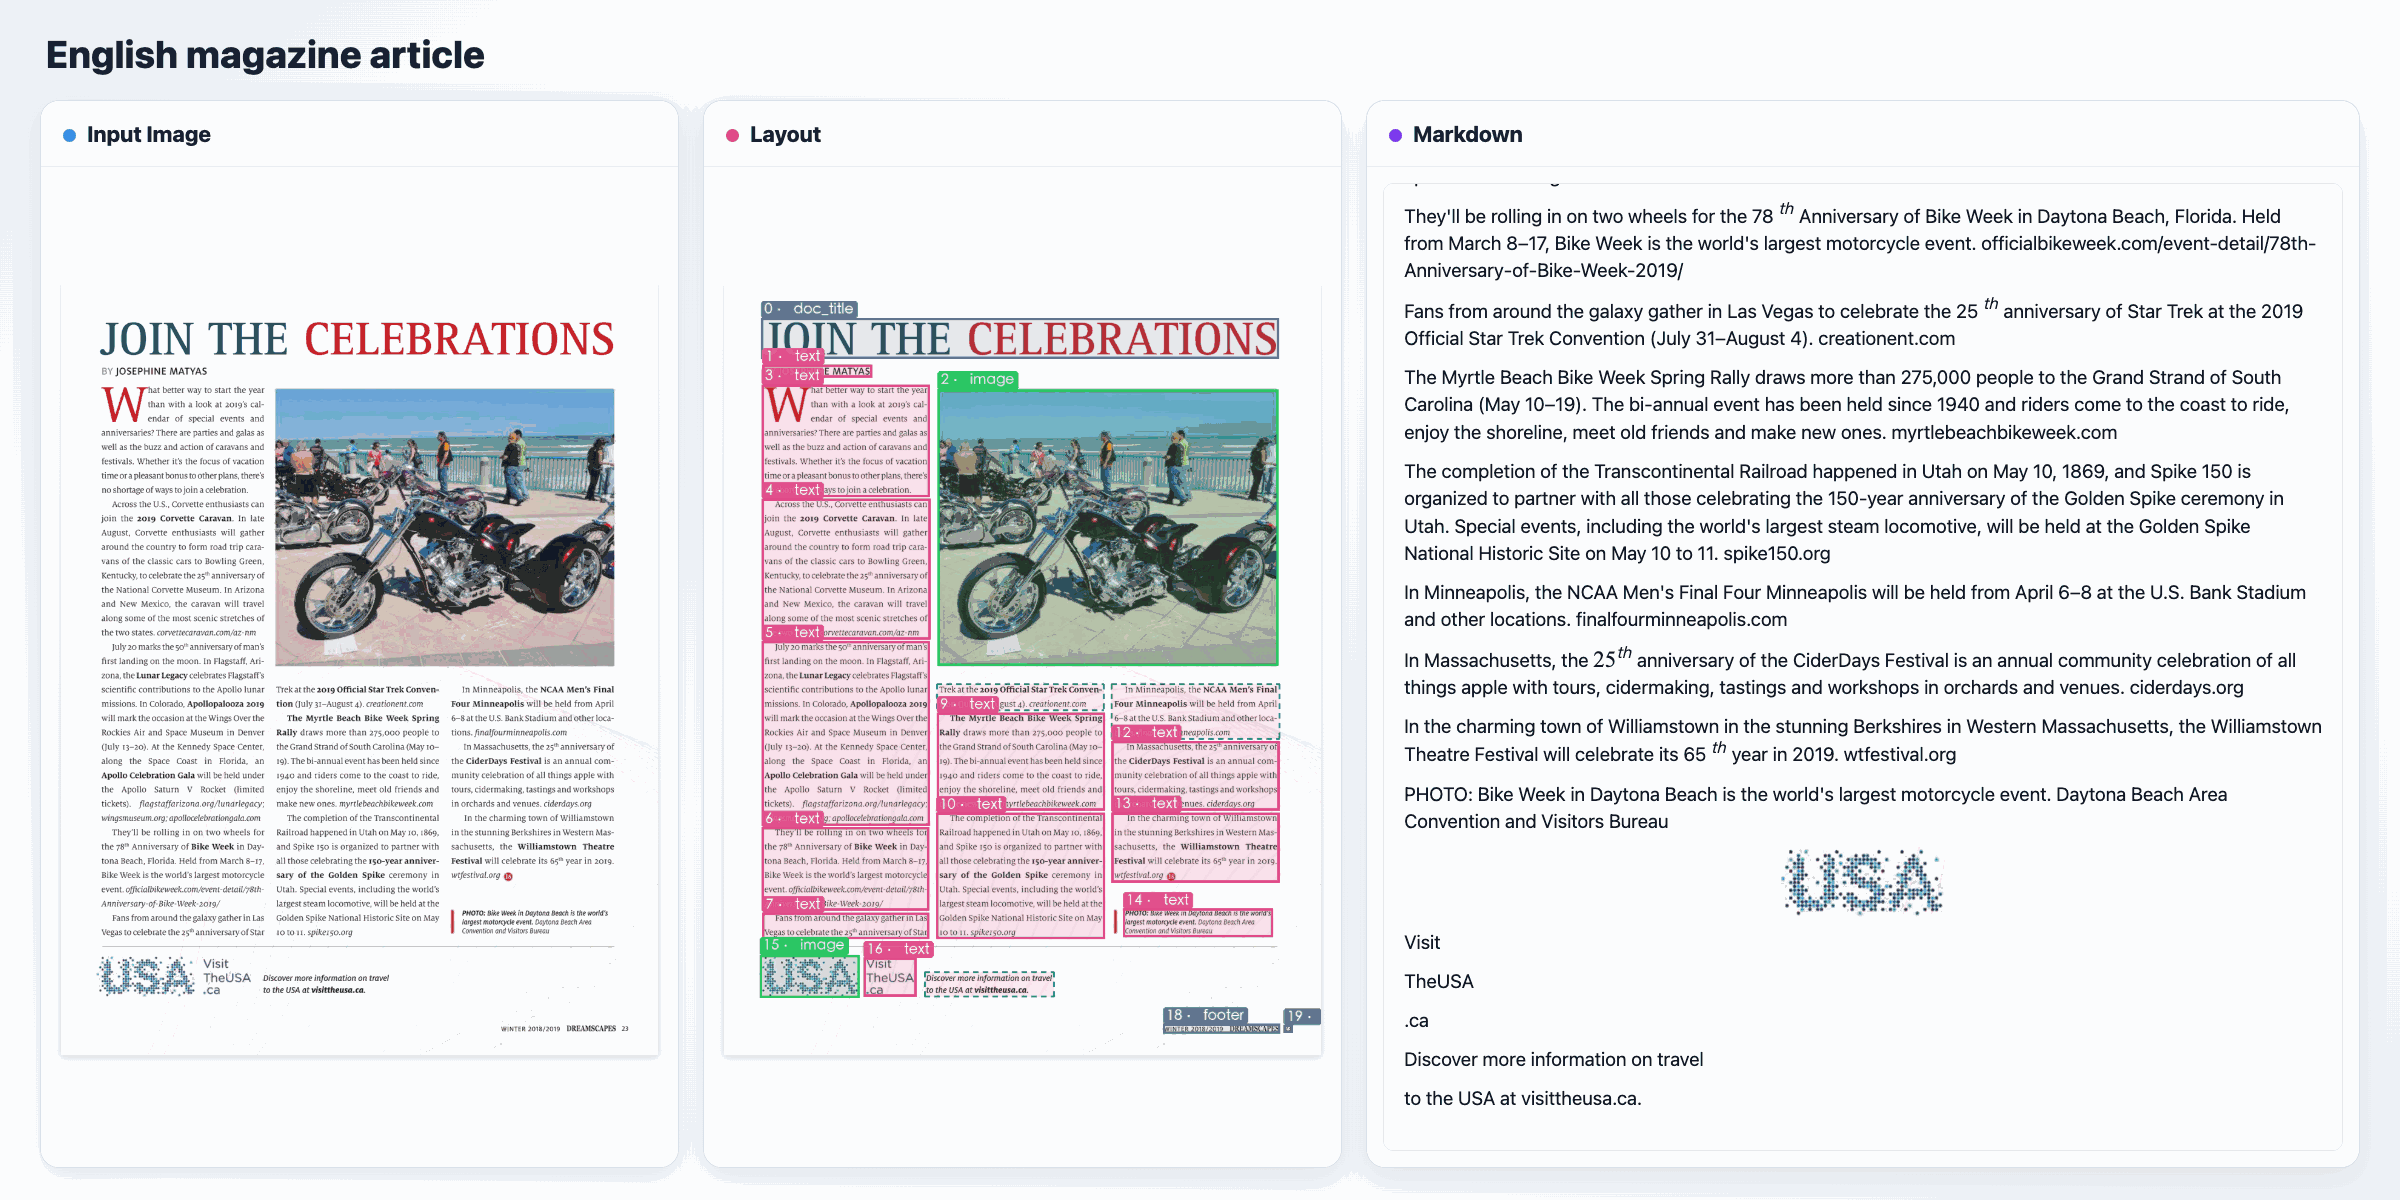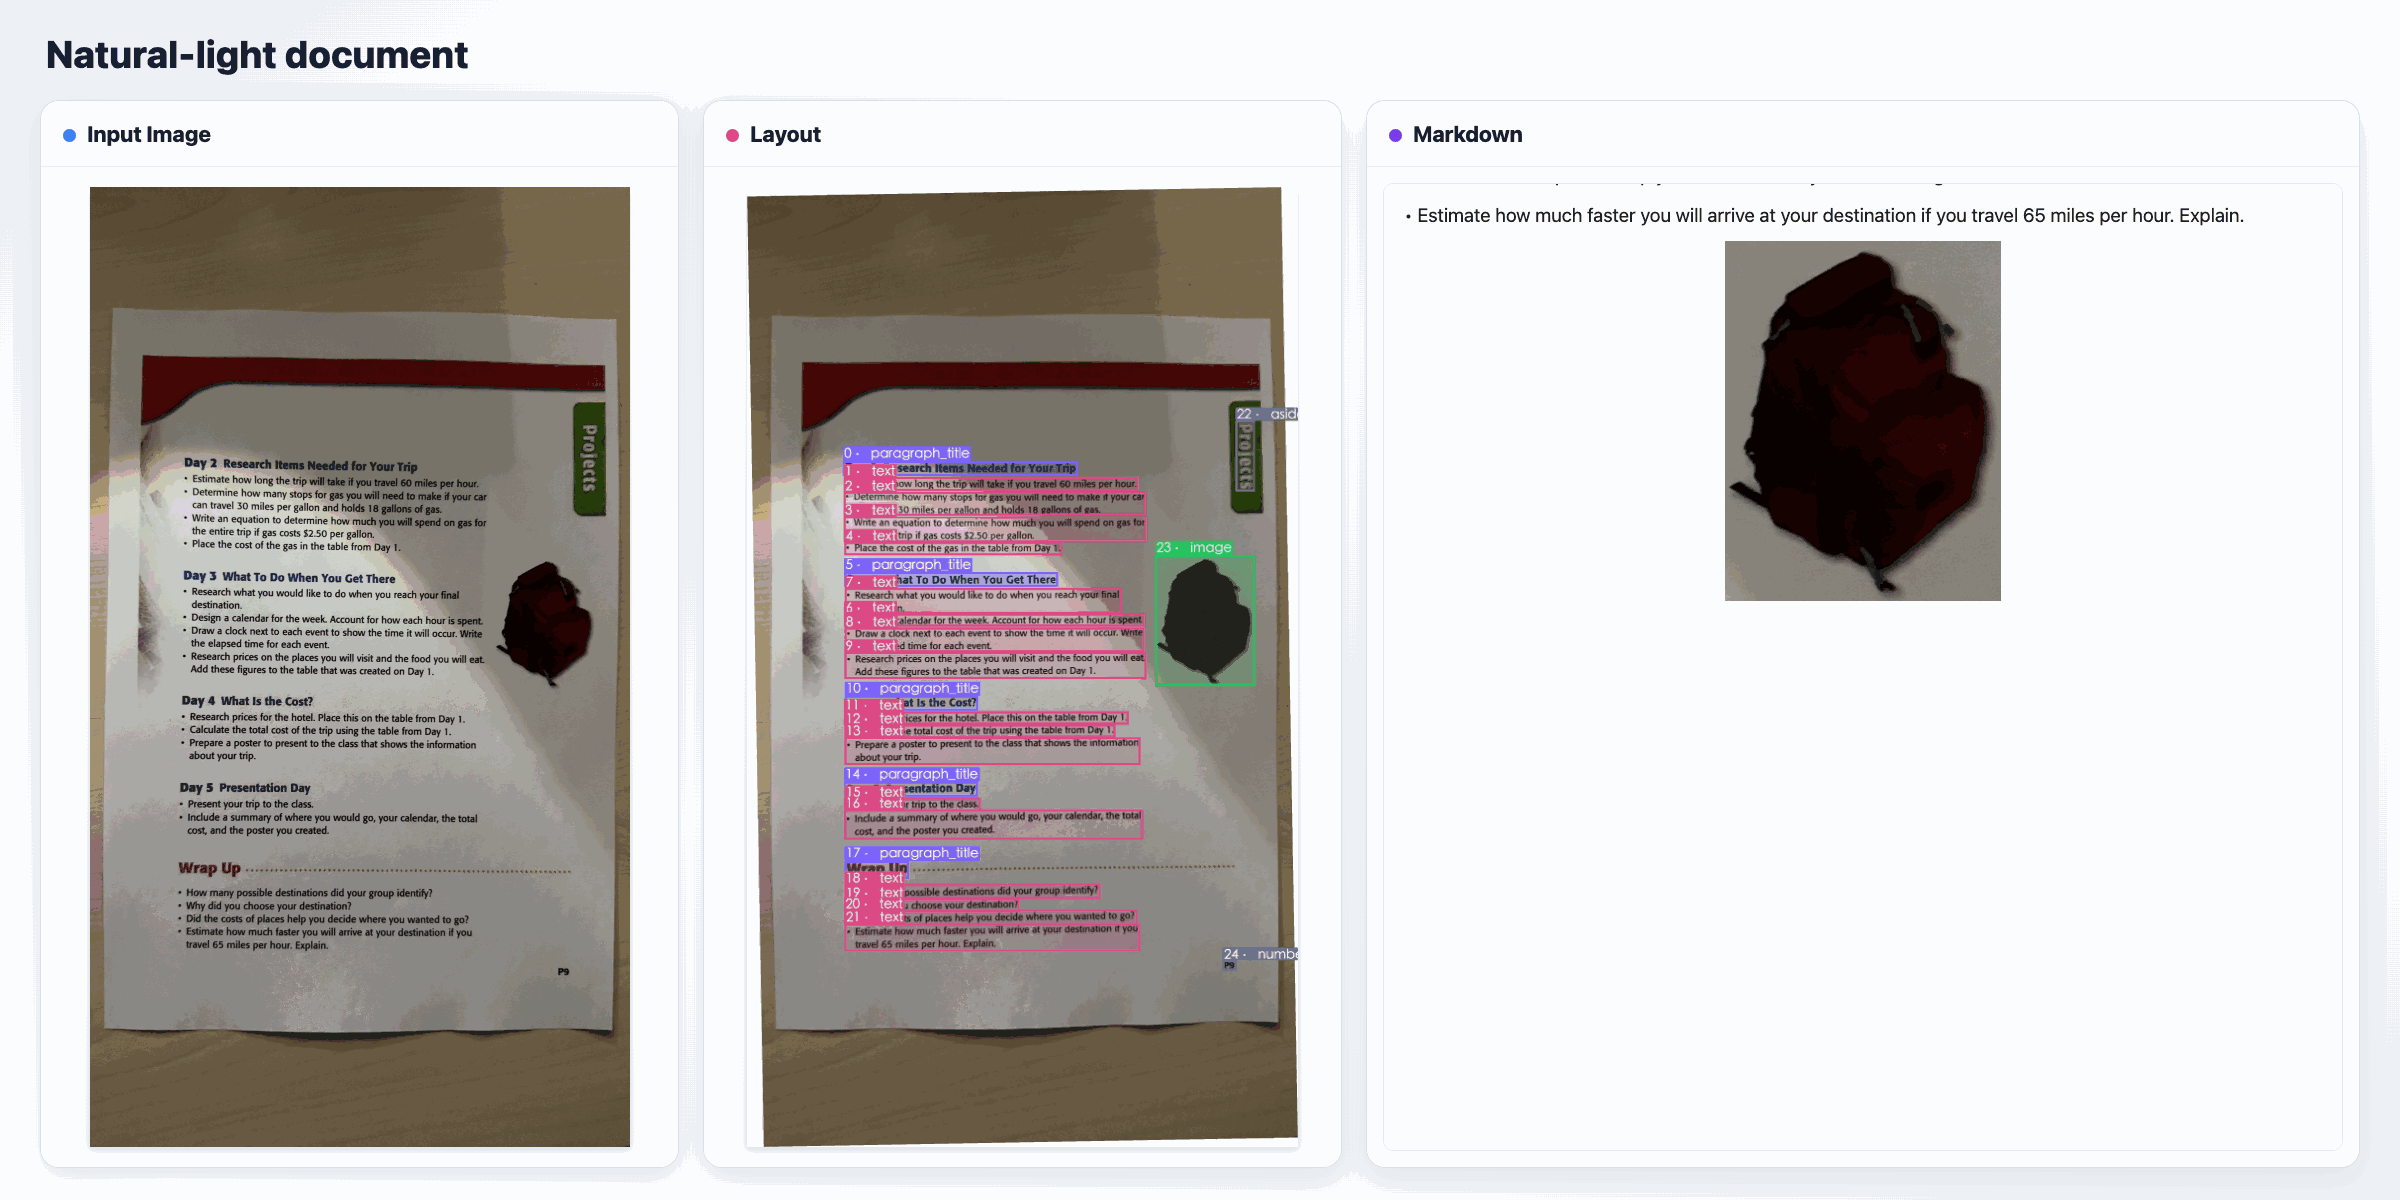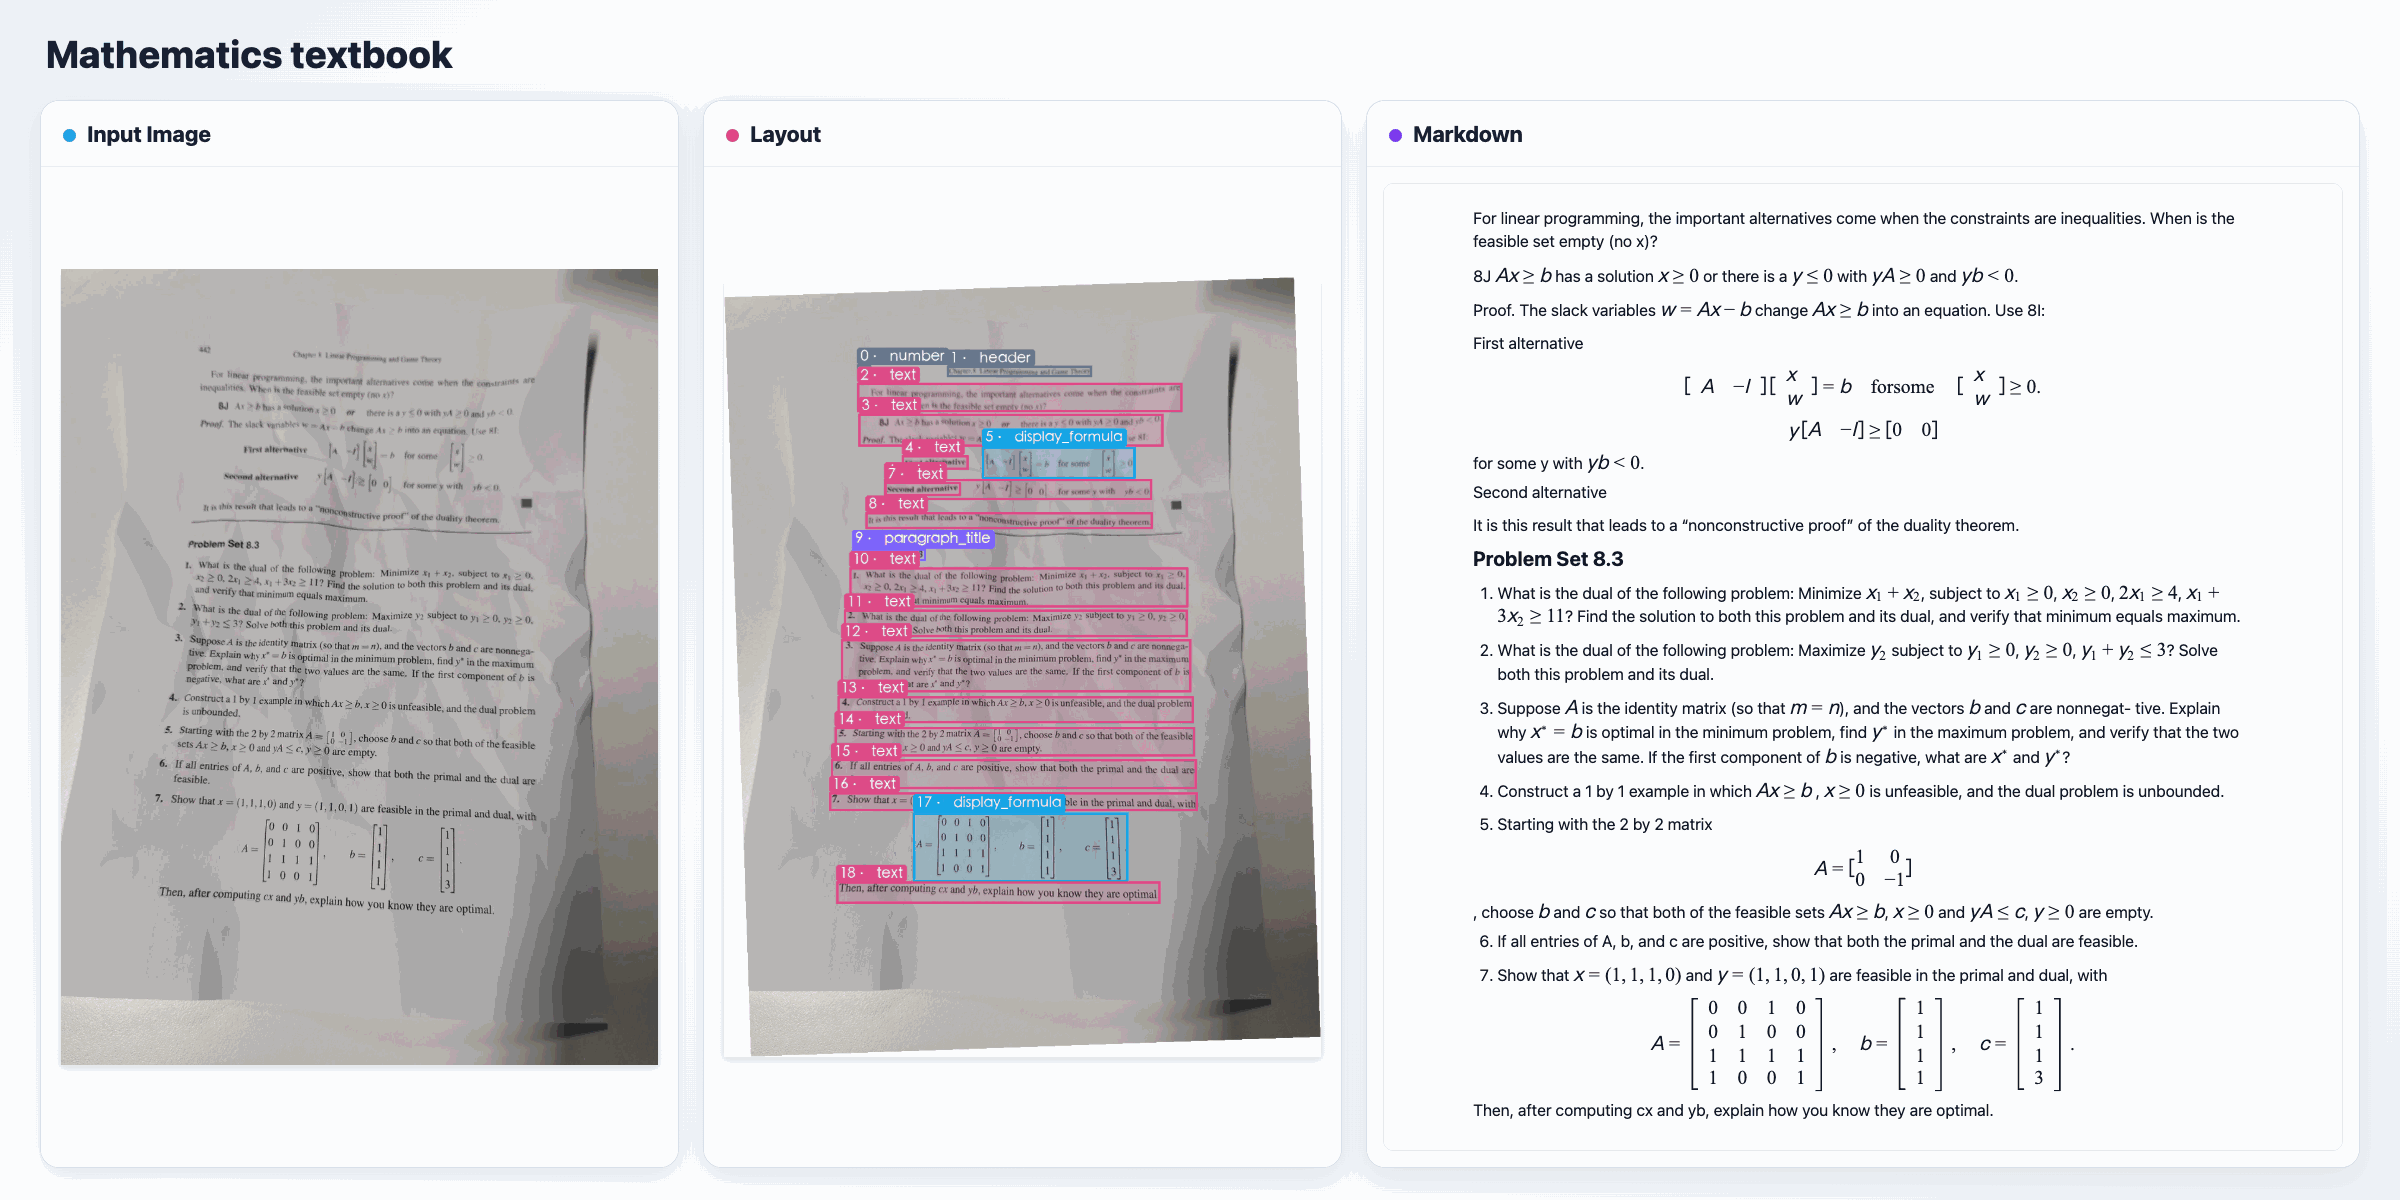
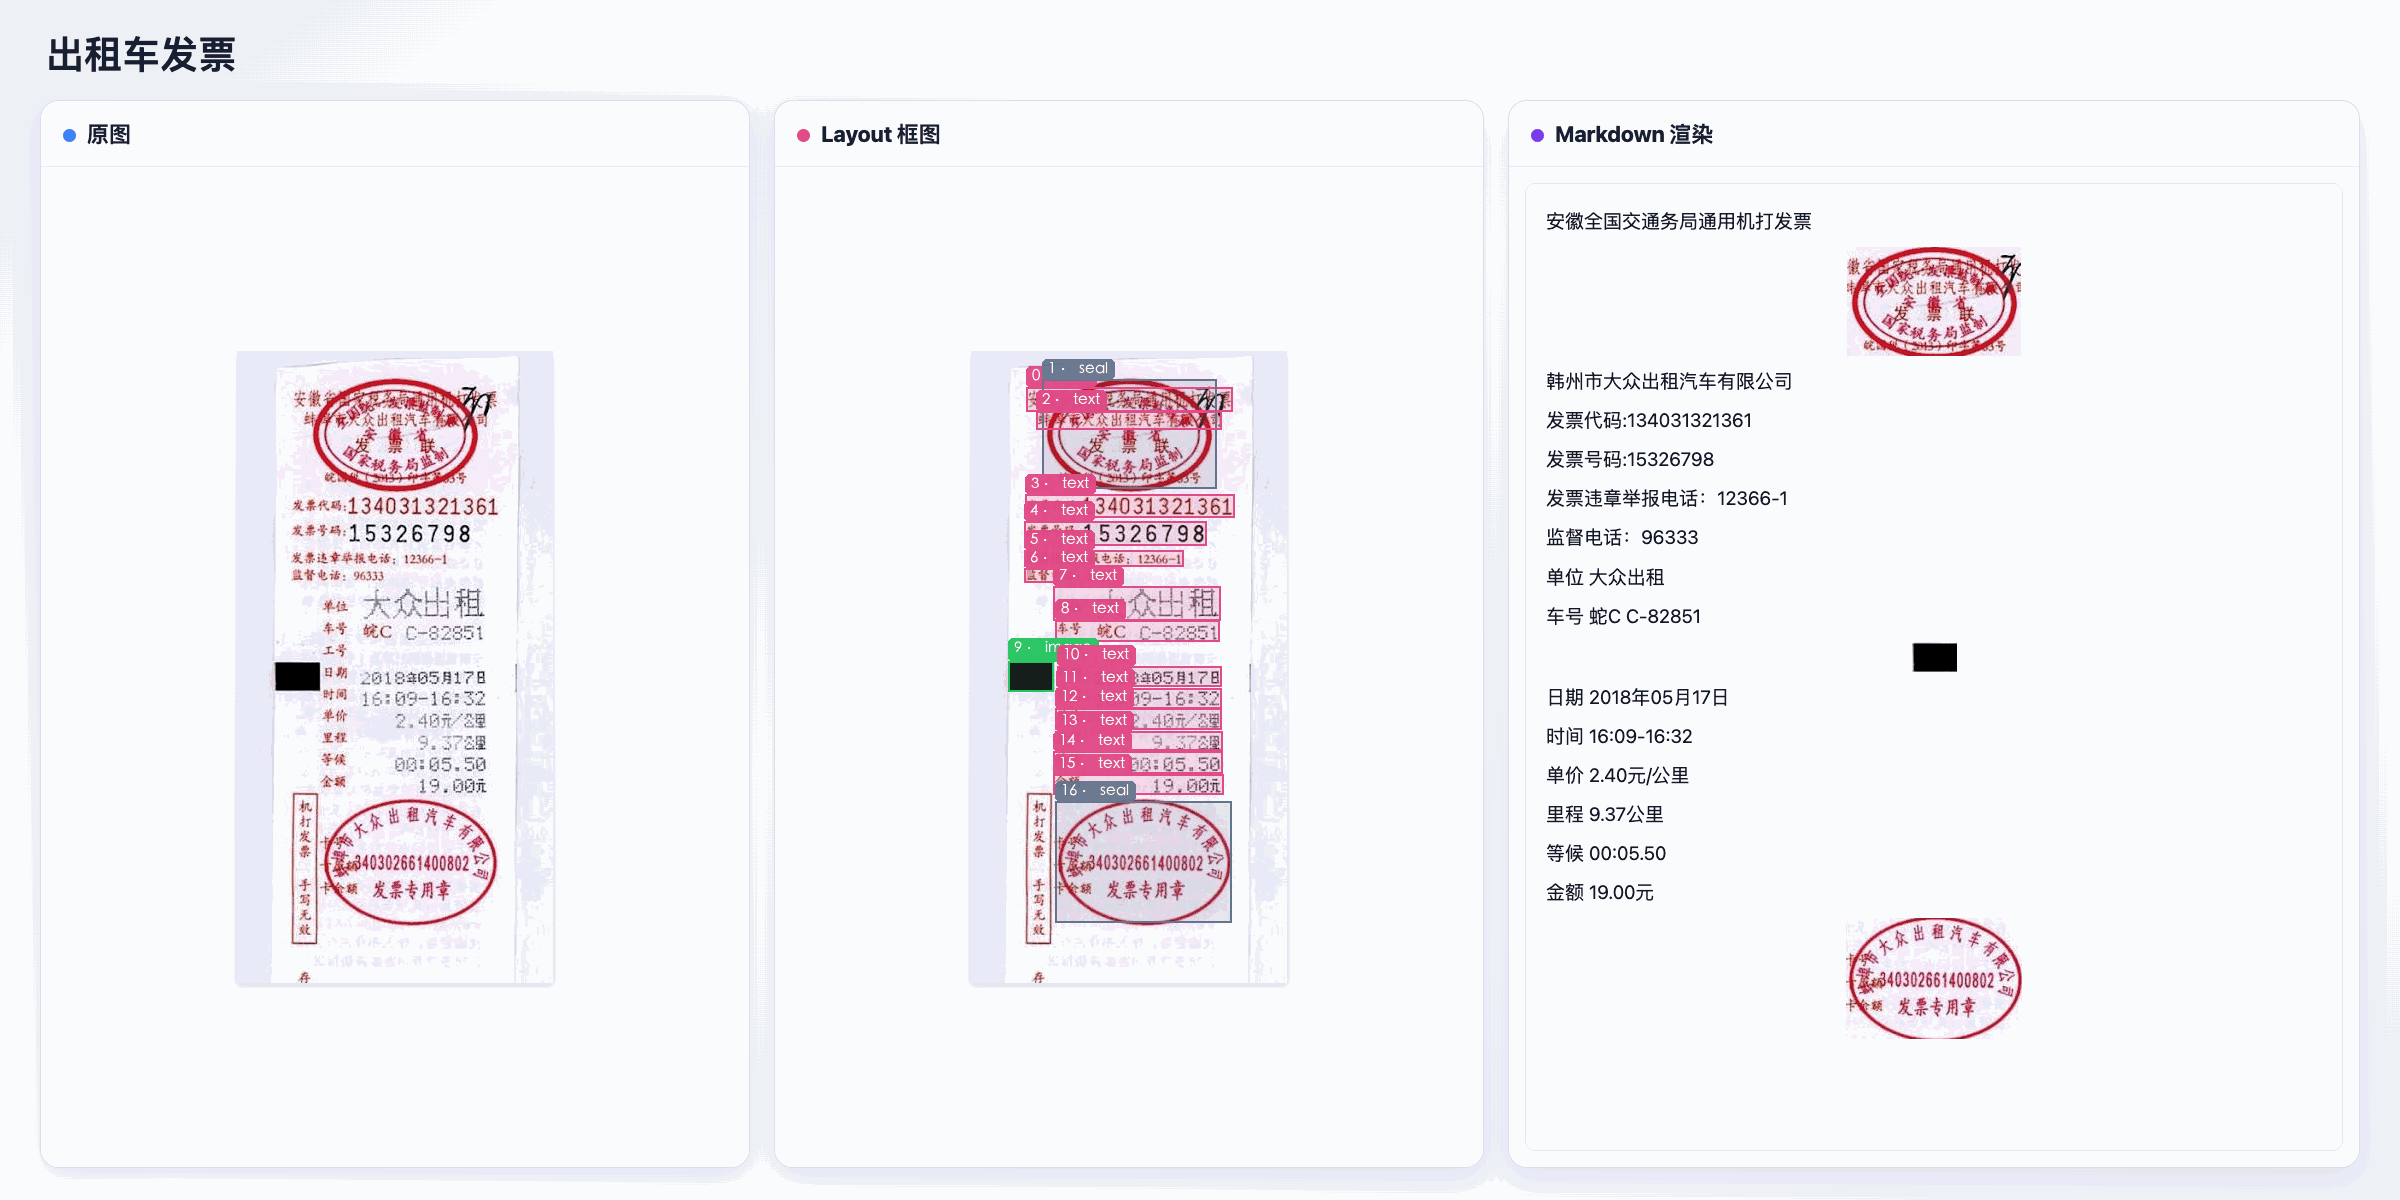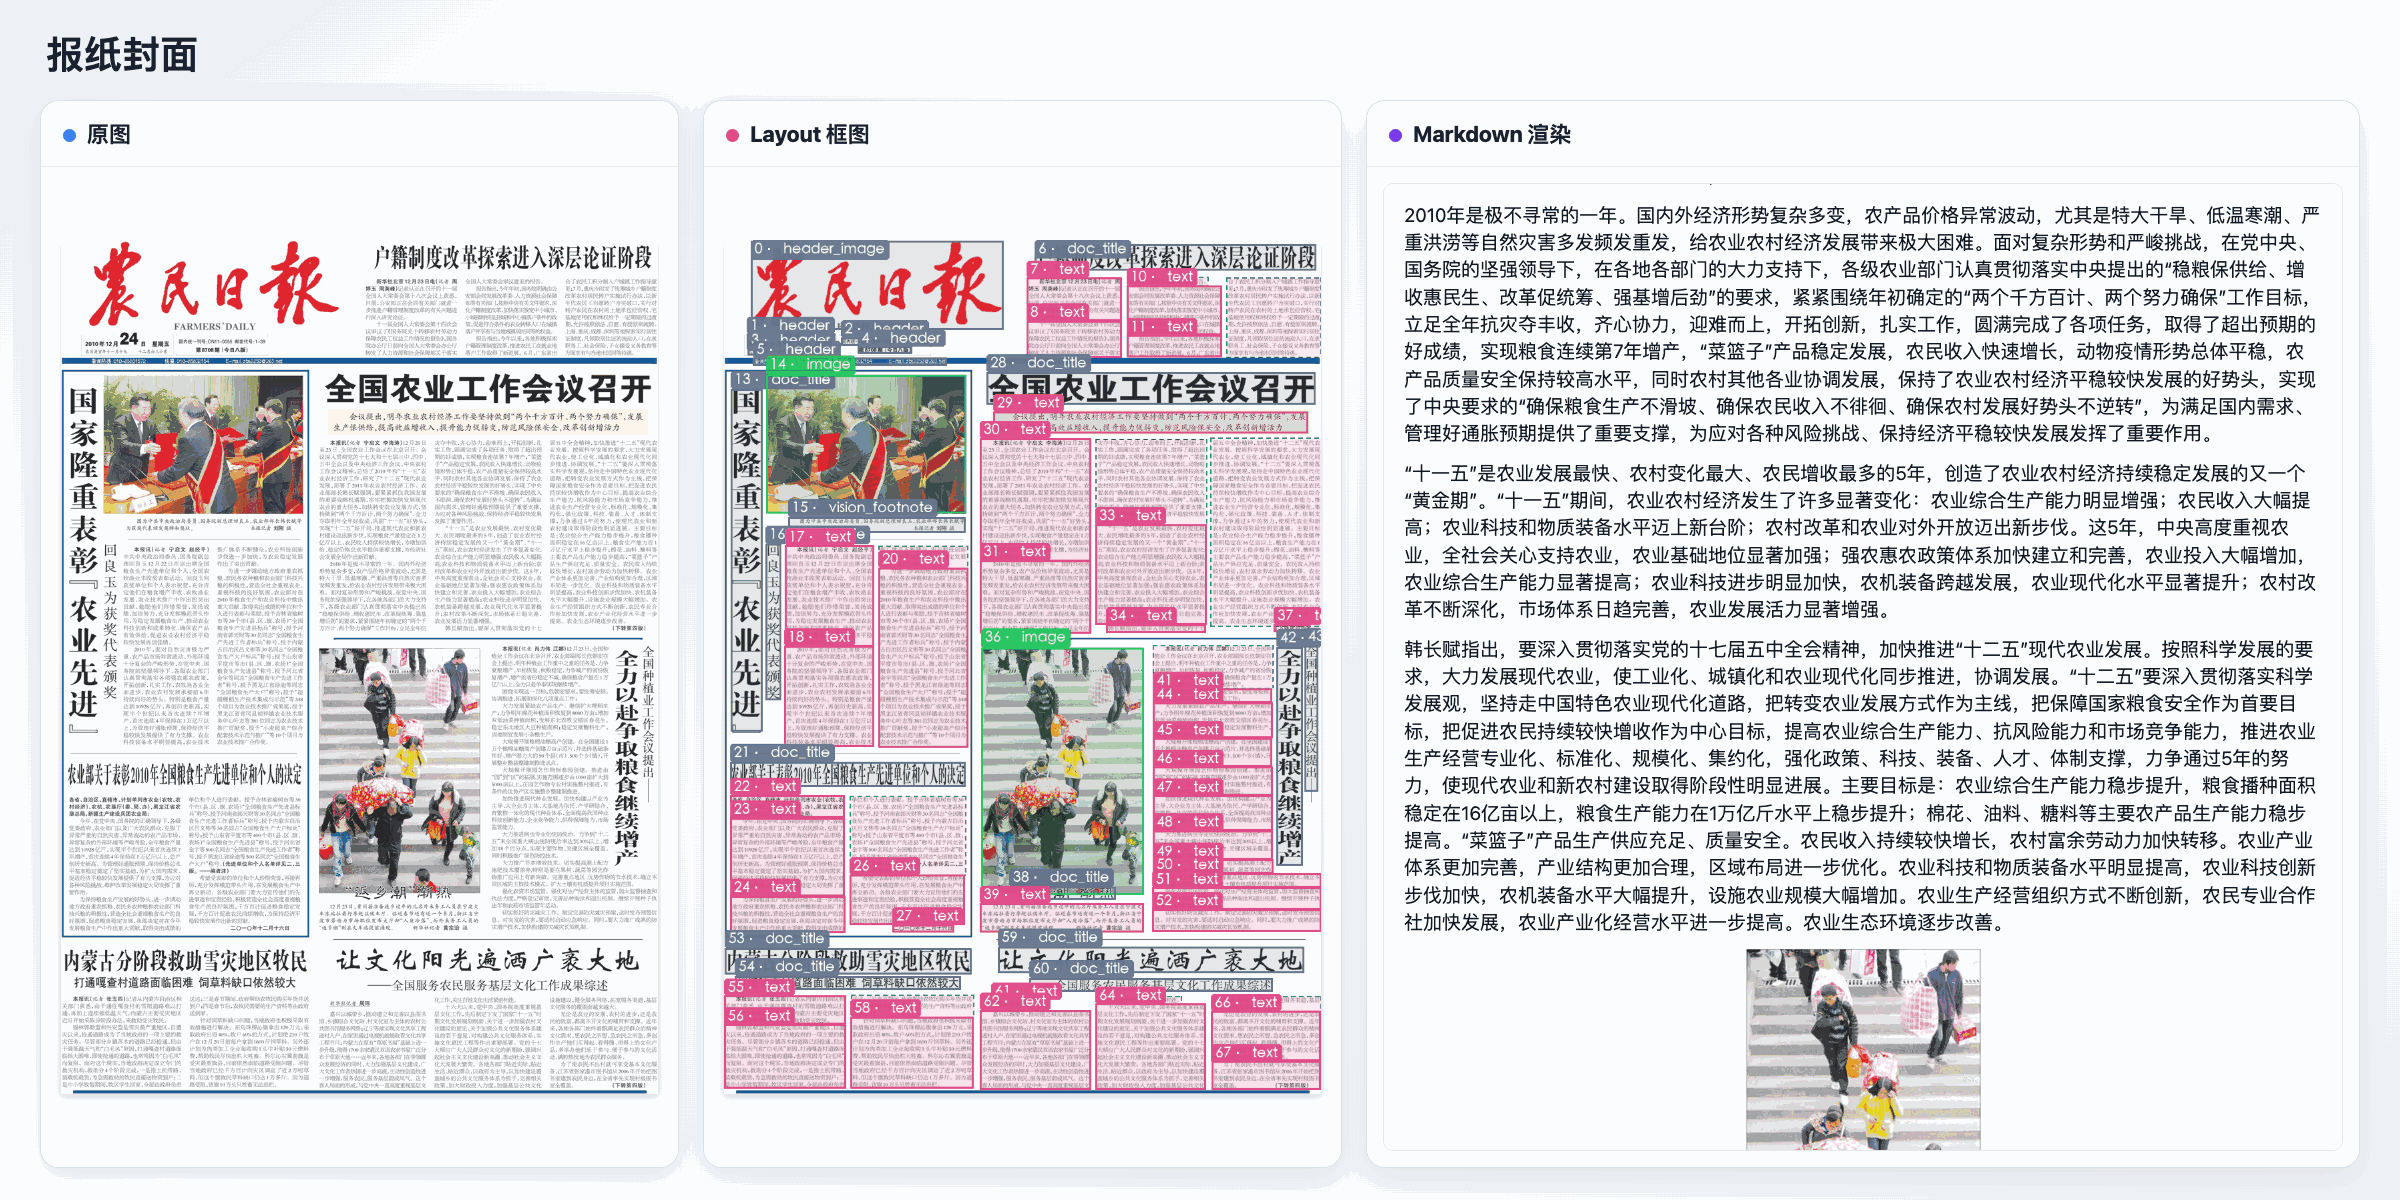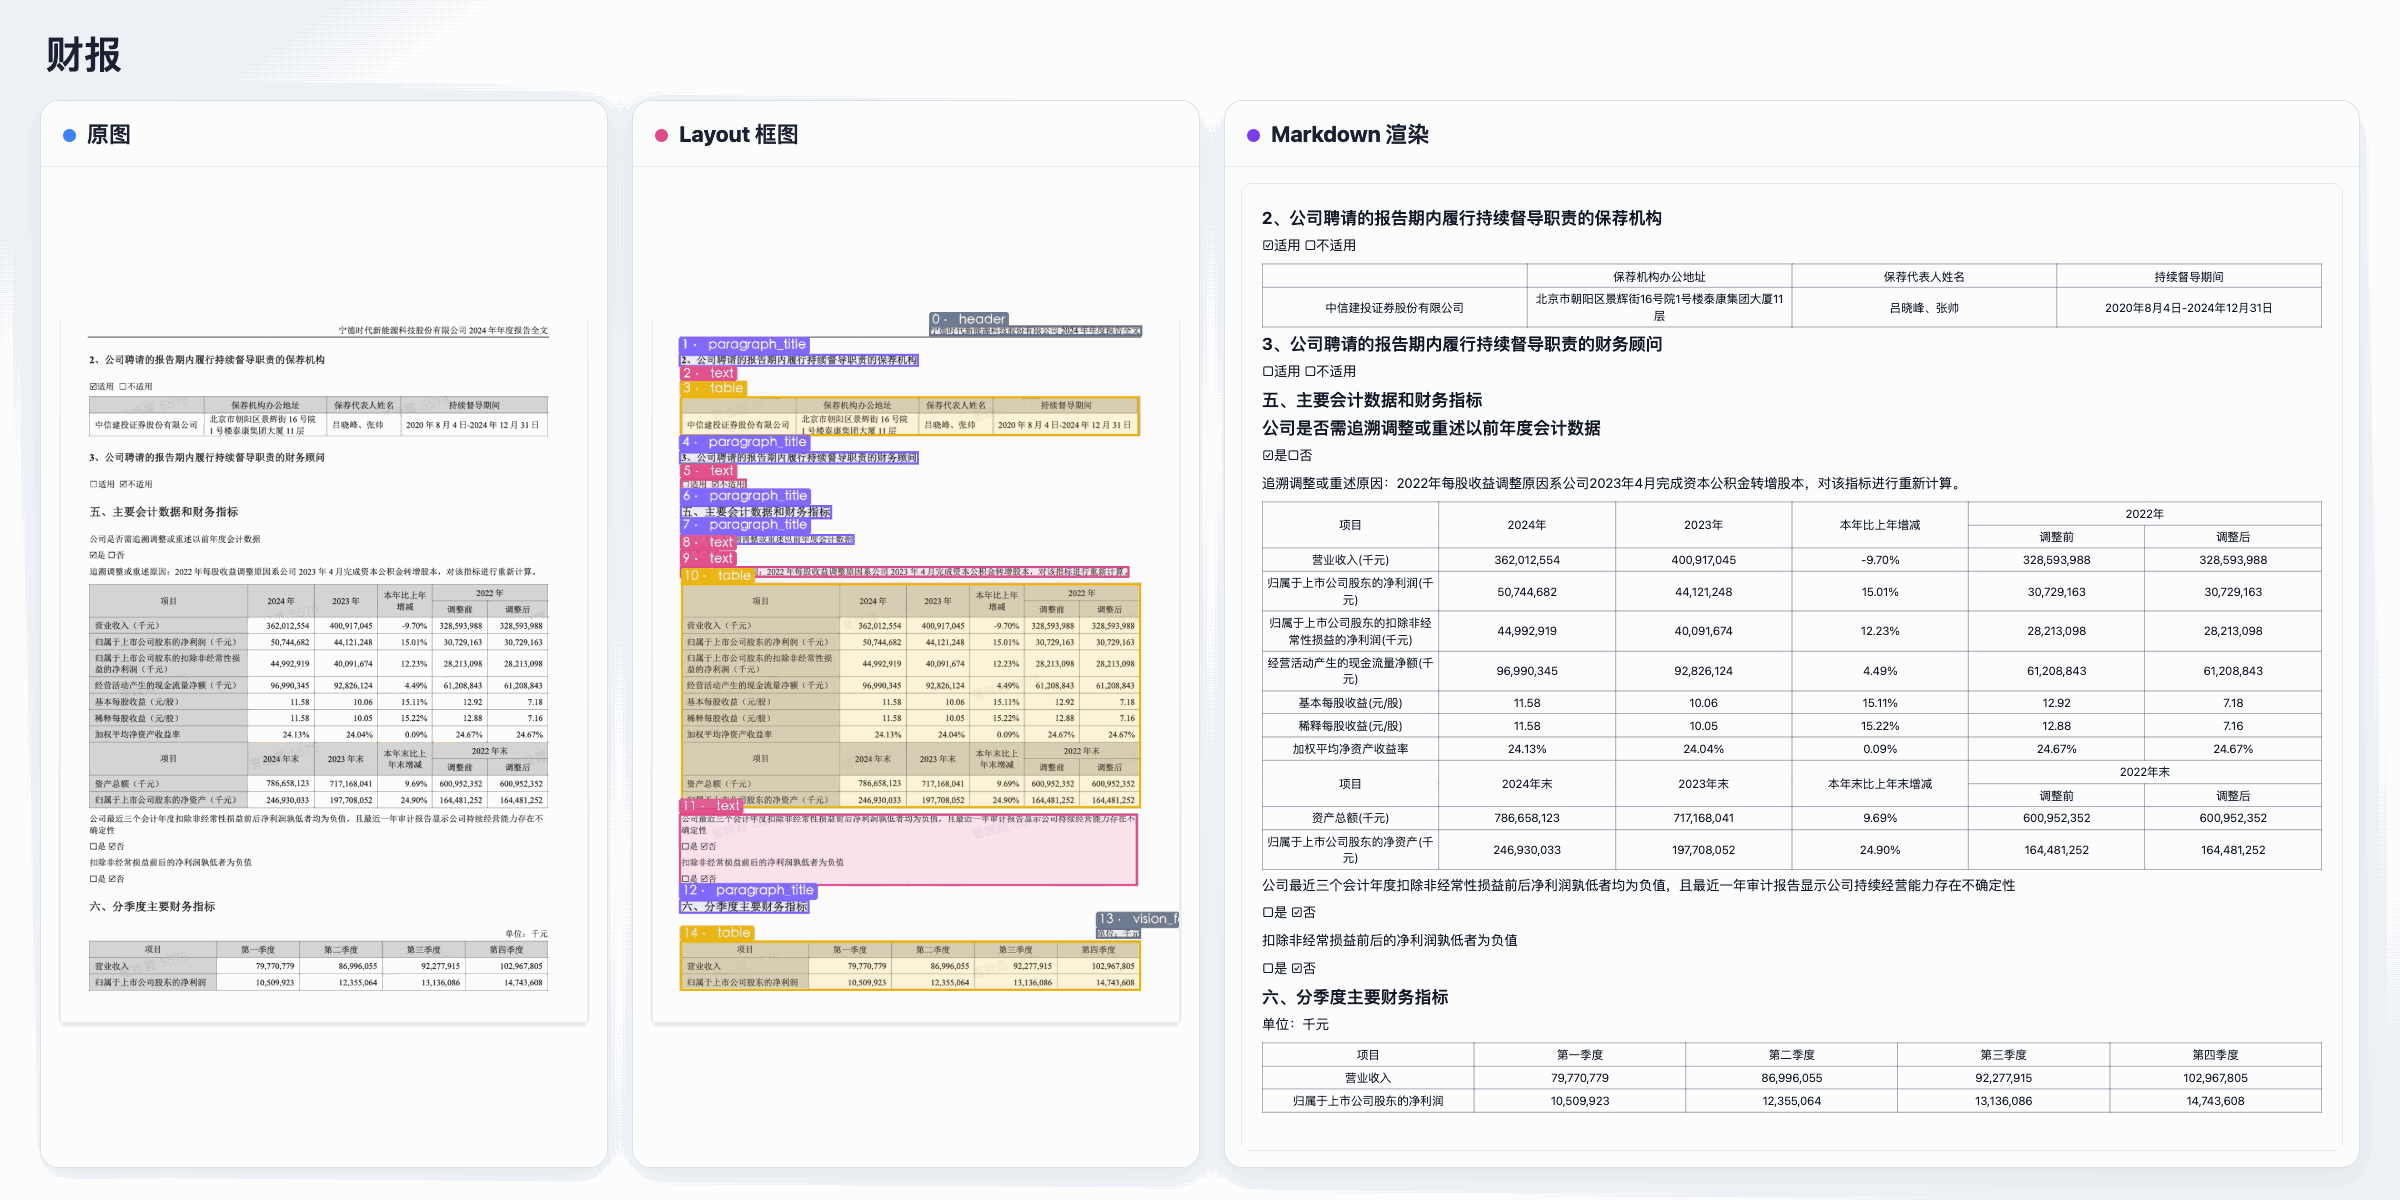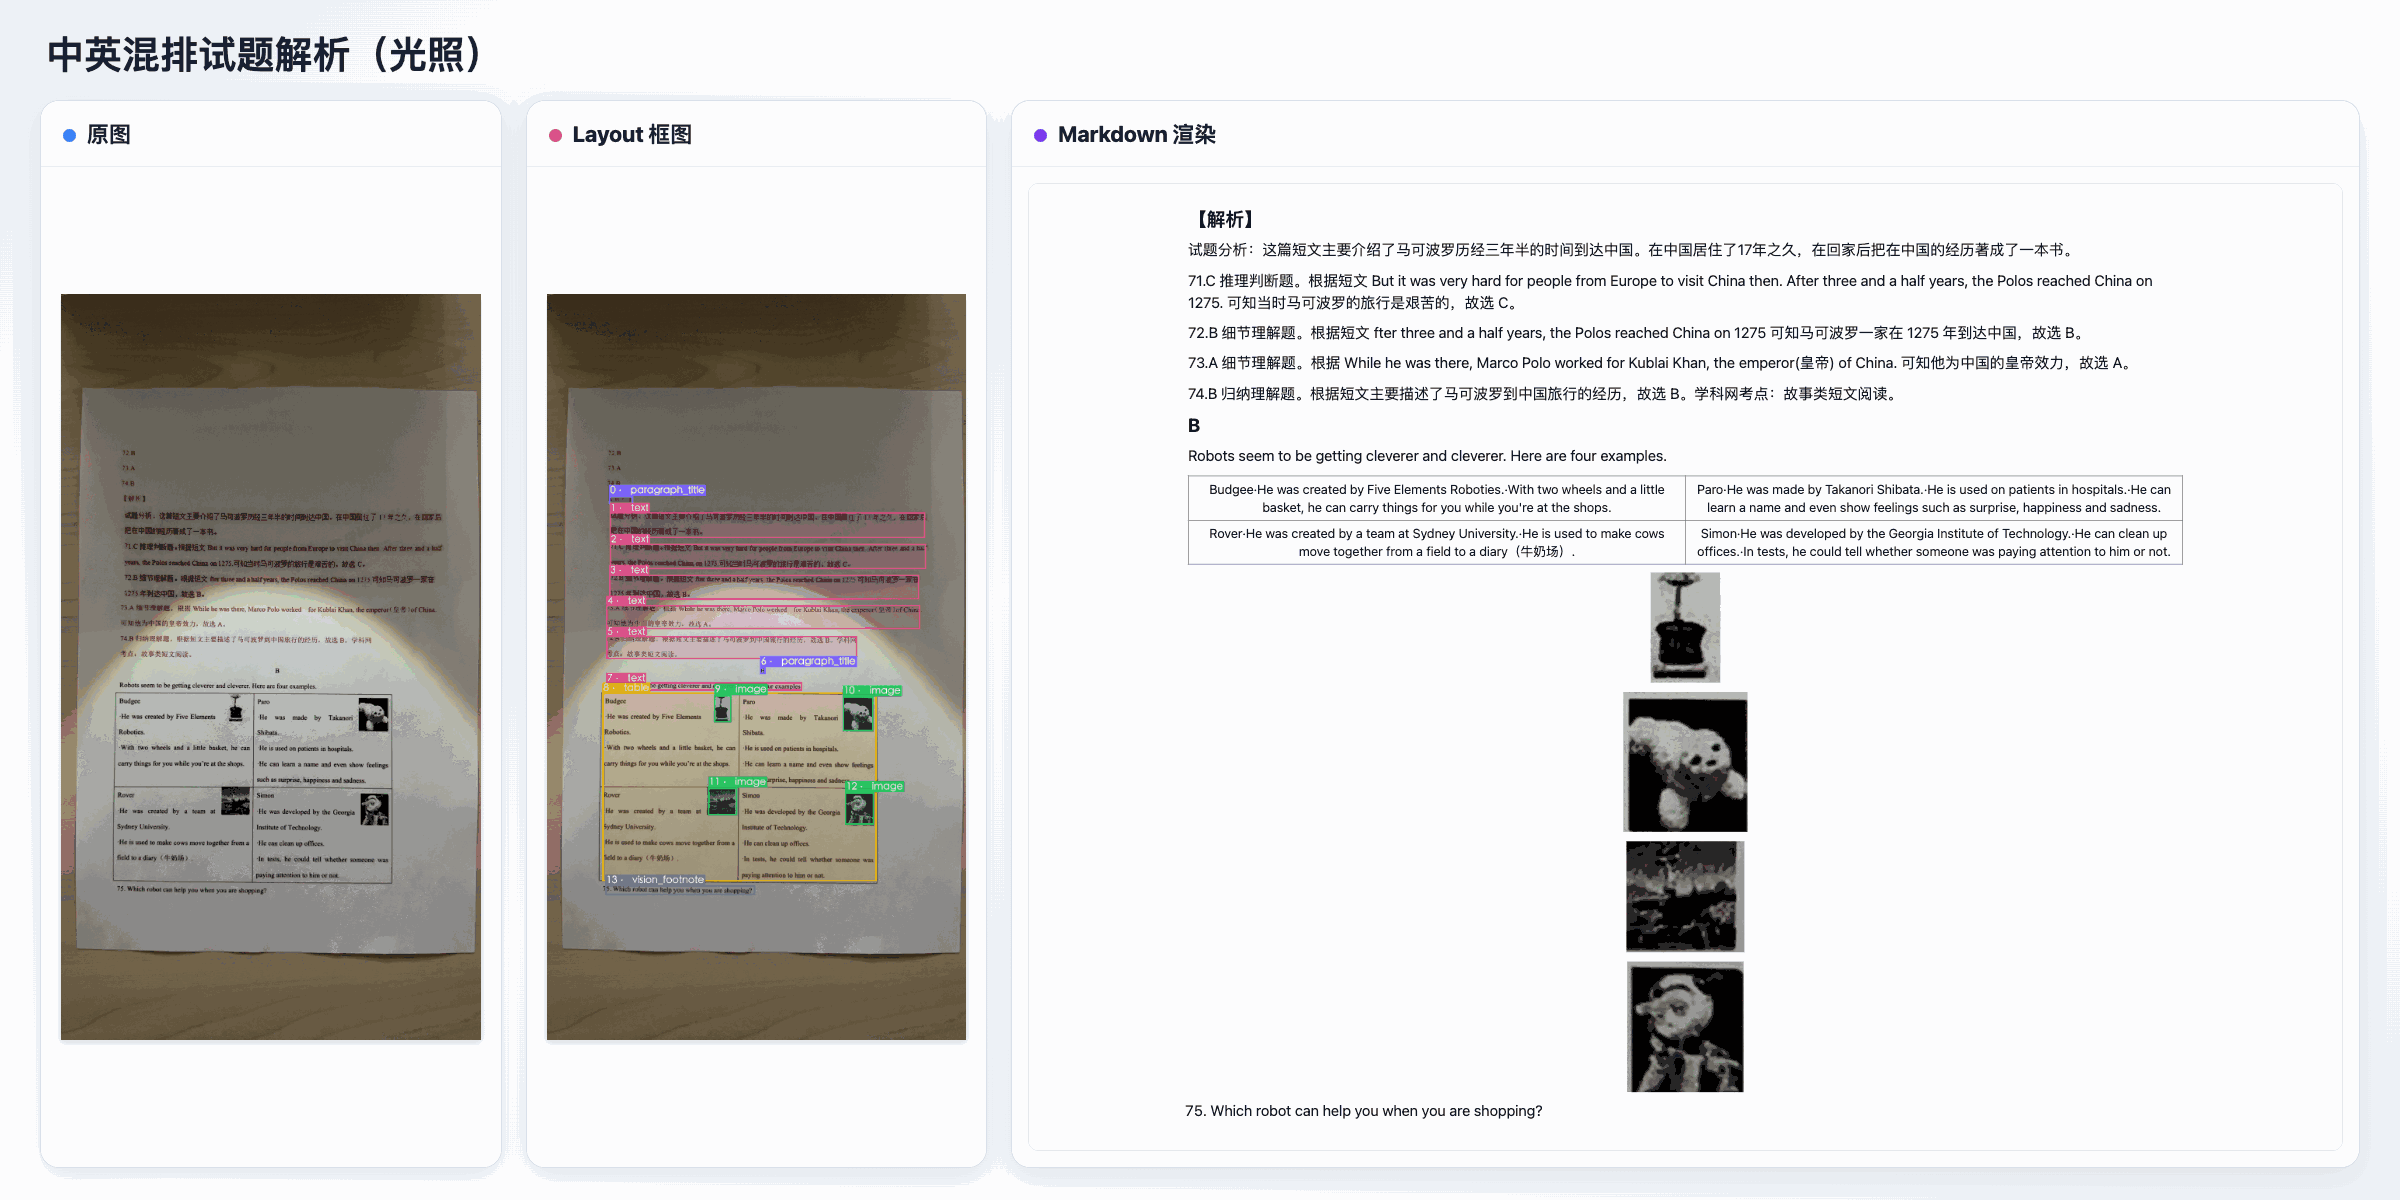
Left to right: original document, detected layout, and rendered Markdown.
**English documents**
**Chinese documents**
### More examples
Original documents and parsed results, side by side.
**English documents**
**Chinese documents**
## Model architecture
| Item | Description |
| :--- | :--- |
| Parameters | 1.3B |
| Base | Trained for OCR on top of MiniCPM-V 4.6 |
| Components | SigLIP vision encoder + Qwen3.5 language model |
| Primary languages | Chinese and English |
| Tasks | Text, tables, formulas, charts, seals, and key information extraction |
| Parsing pipeline | MiniCPM-OCR 1.0 + PP-DocLayoutV3 layout model + `minicpmvocr` SDK |
| Visual tokens | 4× compression, `scale_resolution` 448, up to 9 slices |
See the [model guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpm_ocr_1dot0_en.md) for architecture, parsing workflow,
deployment options, and benchmark breakdowns.
## Quick start
### Document parsing (SDK)
The SDK parses whole documents; the model recognises regions:
1. **Read** — accept PDF/PNG/JPG and rasterise PDF pages.
2. **Layout** — PP-DocLayoutV3 detects regions and reading order, then crops them.
3. **Recognise** — regions are sent to the MiniCPM-OCR 1.0 service concurrently.
4. **Assemble** — results are merged into Markdown in reading order; tables become HTML,
formulas stay LaTeX.
SDK and inference service use separate Python environments and may run on different machines.
See the [SDK tutorial](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpmvocr_tutorial_en.md).
### vLLM
```bash
vllm serve openbmb/MiniCPM-OCR-1.0 \
--served-model-name MiniCPM-OCR \
--trust-remote-code \
--max-model-len 40960
```
Full API example (request fields, image encoding, response checks):
[vLLM deploy guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/vllm_deploy_en.md).
### Other runtimes
| Runtime | Guide |
| :--- | :--- |
| vLLM | [API service and single-region recognition](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/vllm_deploy_en.md) |
| SGLang | [Deployment guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/sglang_deploy.md) |
| llama.cpp | [GGUF deployment guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/llamacpp_deploy.md) |
| Ollama | [SDK service connection and backend configuration](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpmvocr_api_en.md) |
| Transformers | [Service deployment](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_en.md#43-transformers-serve) |
| FlagOS (multi-chip) | [Deployment guide](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/flagos_deploy_en.md) |
### Prompts
The prompt selects the task and must match the region you cropped:
| Region | Prompt | Output |
| :--- | :--- | :--- |
| Text block / paragraph / title / page | `Text Recognition:` | plain text |
| Table | `Table Recognition:` | HTML (via SDK post-processing) |
| Formula | `Formula Recognition:` | LaTeX |
| Inline formula | `Text Recognition:` | LaTeX |
| Seal | `Seal Recognition:` | seal text |
| Chart | `Chart to Table:` | table |
If `finish_reason` is `length`, the output was truncated — raise the token budget.
### Key information extraction (KIE)
MiniCPM-OCR 1.0 can pull specified fields straight out of an image — for example the store name
and amount on a receipt. Send the image with a field-extraction prompt and ask for a JSON object;
you do not need to produce page Markdown first.
Use the [image recognition API example](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/vllm_deploy_en.md#22-image-recognition) and
replace `Text Recognition:` with:
```text
Extract the "store_name", "amount". Format the output as a JSON object with keys: "store_name", "amount". If an item is not in the image, use "###".
```
Replace both field lists with your own field names (Chinese or English). The response is
model-generated text: parse the JSON and check fields and values before using it downstream.
### Agent skill
Have a coding agent follow the skill to set up the environment, download the model, and parse
a first document:
```text
Read and execute https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/SKILL_en.md
```
### Fine-tuning
[LLaMA-Factory](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/llamafactory_minicpm_ocr_french_en.md) ·
[ms-swift](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/swift_minicpm_ocr_french_en.md) — data preparation, full-parameter SFT with
the multimodal projector frozen, training, and evaluation (French handwritten text lines).
## Related checkpoints
| Format | Hugging Face | ModelScope |
| :--- | :--- | :--- |
| BF16 (original) **(this repo)** | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0) |
| GGUF (llama.cpp) | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-gguf) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-gguf) |
| AWQ W4A16 | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-AWQ) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-AWQ) |
| GPTQ W4A16 | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-GPTQ) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-GPTQ) |
| DSpark draft (BF16) | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-DSpark) |
| DSpark draft (GGUF) | [🤗](https://huggingface.co/openbmb/MiniCPM-OCR-1.0-DSpark-gguf) | [ModelScope](https://modelscope.cn/models/OpenBMB/MiniCPM-OCR-1.0-DSpark-gguf) |
DSpark **requires a matching main and draft model from the same release** — do not mix draft
weights with a different main checkpoint. See
[DSpark acceleration](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/minicpmvocr_tutorial_en.md#3-start-the-service).
For OCR quality assessment (auto-accept, human-review routing, best-of-N across models), see
[MiniCPM-OCR Jev](https://huggingface.co/openbmb/MiniCPM-OCR-Jev).
## FAQ
Installation, model downloads, GPU memory, input formats, and unexpected outputs:
[FAQ](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/docs/faq_en.md).
## License
Model weights, code, and documentation are released under the
[Apache License 2.0](https://github.com/OpenBMB/MiniCPM-OCR/blob/main/LICENSE).