---
title: EchoMimicV3
canonical_url: "https://www.modelscope.cn/models/BadToBest/EchoMimicV3"
md_url: "https://www.modelscope.cn/models/BadToBest/EchoMimicV3.md"
repository: BadToBest/EchoMimicV3
last_updated: 2026-01-23
license: apache-2.0
pipeline_tag: image-to-video
tasks:
- image-to-video
parameters: 1.7B
tensor_type:
- BF16
library_name:
- safetensors
- diffusers
- pytorch
frameworks:
- pytorch
downloads: 4240
stars: 16
---
# EchoMimicV3
> EchoMimicV3 - BadToBest 在 ModelScope 开源的模型。EchoMimicV3: 1.3B Parameters are All You Need for Unified Multi-Modal and Multi-Task Human Animation
BadToBest/EchoMimicV3 是 ModelScope 魔搭社区上的 1.7B 参数image-to-video模型,采用 apache-2.0 许可。
- **Repository**: BadToBest/EchoMimicV3
- **License**: apache-2.0
- **Tasks**: image-to-video
- **Parameters**: 1.7B
- **Downloads**: 4240
- **Stars**: 16
- **Last updated**: 2026-01-23
Source: https://www.modelscope.cn/models/BadToBest/EchoMimicV3
---
EchoMimicV3: 1.3B Parameters are All You Need for Unified Multi-Modal and Multi-Task Human Animation
Terminal Technology Department, Alipay, Ant Group.
1Core Contributor
2Corresponding Authors
## 🚀 EchoMimic Series
* EchoMimicV3: 1.3B Parameters are All You Need for Unified Multi-Modal and Multi-Task Human Animation. [GitHub](https://github.com/antgroup/echomimic_v3)
* EchoMimicV2: Towards Striking, Simplified, and Semi-Body Human Animation. [GitHub](https://github.com/antgroup/echomimic_v2)
* EchoMimicV1: Lifelike Audio-Driven Portrait Animations through Editable Landmark Conditioning. [GitHub](https://github.com/antgroup/echomimic)
## 📣 Updates
* [2025.07.08] 🔥 Our [paper](https://arxiv.org/abs/2507.03905) is in public on arxiv.
## 🌅 Gallery

For more demo videos, please refer to the project page.
## Quick Start
### Environment Setup
- Tested System Environment: Centos 7.2/Ubuntu 22.04, Cuda >= 12.1
- Tested GPUs: A100(80G) / RTX4090D (24G) / V100(16G)
- Tested Python Version: 3.10 / 3.11
### 🛠️Installation
#### 1. Create a conda environment and install pytorch, xformers
```
conda create -n echomimic_v3 python=3.10
conda activate echomimic_v3
```
#### 2. Other dependencies
```
pip install -r requirements.txt
```
### 🧱Model Preparation
| Models | Download Link | Notes |
| --------------|-------------------------------------------------------------------------------|-------------------------------|
| Wan2.1-Fun-1.3B-InP | 🤗 [Huggingface](https://huggingface.co/spaces/alibaba-pai/Wan2.1-Fun-1.3B-InP) | Base model
| wav2vec2-base | 🤗 [Huggingface](https://huggingface.co/facebook/wav2vec2-base-960h) | Audio encoder
| EchoMimicV3 | 🤗 [Huggingface](https://huggingface.co/BadToBest/EchoMimicV3) | Our weights
-- The **weights** is organized as follows.
```
./models/
├── Wan2.1-Fun-1.3B-InP
├── wav2vec2-base-960h
└── transformer
└── diffusion_pytorch_model.safetensors
### 🔑 Quick Inference
```
python infer.py
```
> Tips
> - Audio CFG: Audio CFG works optimally between 2~3. Increase the audio CFG value for better lip synchronization, while decreasing the audio CFG value can improve the visual quality.
> - Text CFG: Text CFG works optimally between 4~6. Increase the text CFG value for better prompt following, while decreasing the text CFG value can improve the visual quality.
> - TeaCache: The optimal range for `--teacache_thresh` is between 0~0.1.
> - Sampling steps: 5 steps for talking head, 15~25 steps for talking body.
> - Long video generation: If you want to generate a video longer than 138 frames, you can use Long Video CFG.
## 📝 TODO List
| Status | Milestone |
|:--------:|:-------------------------------------------------------------------------|
| 2025.08.08 | The inference code of EchoMimicV3 meet everyone on GitHub |
| 🚀 | Preview version Pretrained models trained on English and Chinese on HuggingFace |
| 🚀 | Preview version Pretrained models trained on English and Chinese on ModelScope |
| 🚀 | 720P Pretrained models trained on English and Chinese on HuggingFace |
| 🚀 | 720P Pretrained models trained on English and Chinese on ModelScope |
| 🚀 | The training code of EchoMimicV3 meet everyone on GitHub |
## 📒 Citation
If you find our work useful for your research, please consider citing the paper :
```
@misc{meng2025echomimicv3,
title={EchoMimicV3: 1.3B Parameters are All You Need for Unified Multi-Modal and Multi-Task Human Animation},
author={Rang Meng, Yan Wang, Weipeng Wu, Ruobing Zheng, Yuming Li, Chenguang Ma},
year={2025},
eprint={2507.03905},
archivePrefix={arXiv}
}
```
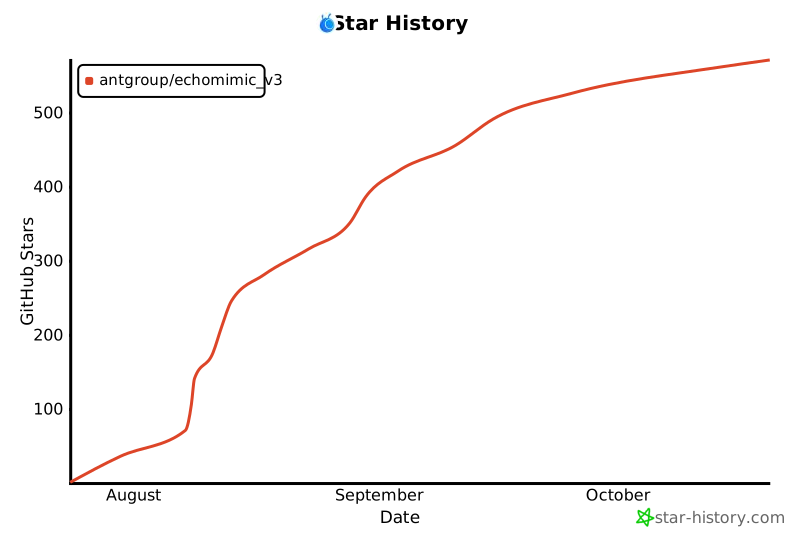
## 🌟 Star History
[](https://star-history.com/#antgroup/echomimic_v3&Date)

