---
title: colpali
canonical_url: "https://www.modelscope.cn/models/AI-ModelScope/colpali"
md_url: "https://www.modelscope.cn/models/AI-ModelScope/colpali.md"
repository: AI-ModelScope/colpali
chinese_name: "ColPali文档检索"
last_updated: 2025-11-25
license: mit
pipeline_tag: visual-document-retrieval
tasks:
- visual-document-retrieval
base_model:
- google/paligemma-3b-mix-448
base_model_relation: finetune
parameters: 39.3M
tensor_type:
- BF16
library_name:
- pytorch
- transformer
- safetensors
frameworks:
- pytorch
language:
- en
downloads: 1937
stars: 0
tags:
- colpali
- vidore
---
# colpali
> colpali - AI-ModelScope 在 ModelScope 开源的模型。ColPali: Visual Retriever based on PaliGemma-3B with ColBERT strategy
AI-ModelScope/colpali 是 ModelScope 魔搭社区上的 39.3M 参数visual-document-retrieval模型,采用 mit 许可,基于 google/paligemma-3b-mix-448 构建。
- **Repository**: AI-ModelScope/colpali
- **License**: mit
- **Tasks**: visual-document-retrieval
- **Parameters**: 39.3M
- **Base model**: google/paligemma-3b-mix-448
- **Tags**: colpali, vidore
- **Downloads**: 1937
- **Stars**: 0
- **Last updated**: 2025-11-25
Source: https://www.modelscope.cn/models/AI-ModelScope/colpali
---
# ColPali: Visual Retriever based on PaliGemma-3B with ColBERT strategy
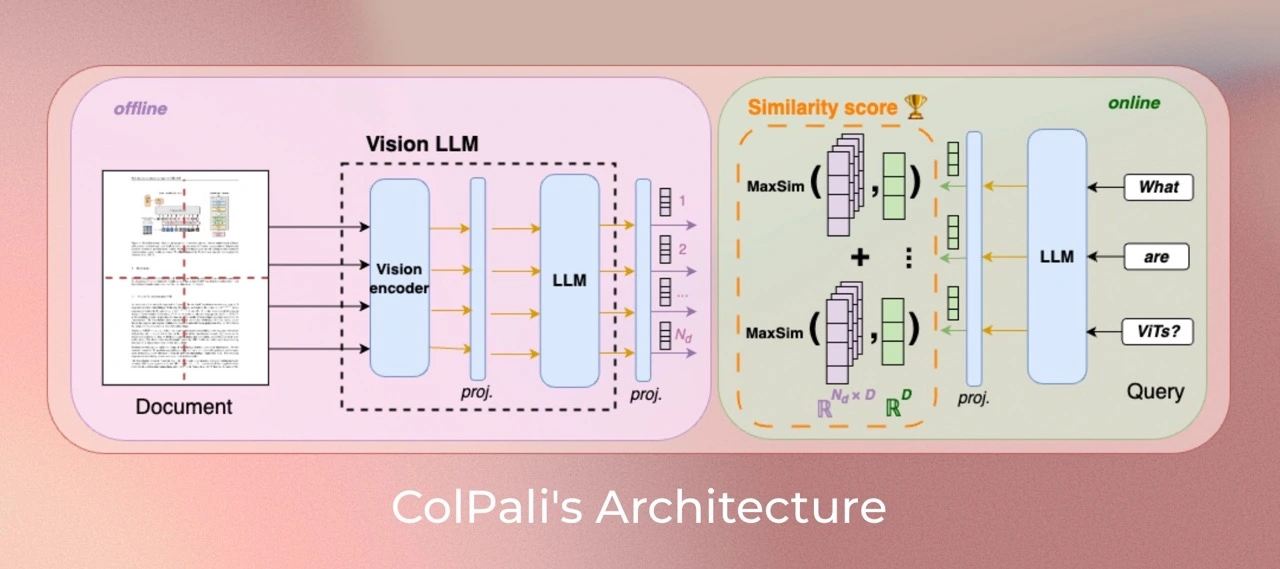
ColPali is a model based on a novel model architecture and training strategy based on Vision Language Models (VLMs) to efficiently index documents from their visual features.
It is a [PaliGemma-3B](https://huggingface.co/google/paligemma-3b-mix-448) extension that generates [ColBERT](https://arxiv.org/abs/2004.12832)- style multi-vector representations of text and images.
It was introduced in the paper [ColPali: Efficient Document Retrieval with Vision Language Models](https://arxiv.org/abs/2407.01449) and first released in [this repository](https://github.com/ManuelFay/colpali)
## Model Description
This model is built iteratively starting from an off-the-shelf [SigLIP](https://huggingface.co/google/siglip-so400m-patch14-384) model.
We finetuned it to create [BiSigLIP](https://huggingface.co/vidore/bisiglip) and fed the patch-embeddings output by SigLIP to an LLM, [PaliGemma-3B](https://huggingface.co/google/paligemma-3b-mix-448) to create [BiPali](https://huggingface.co/vidore/bipali).
One benefit of inputting image patch embeddings through a language model is that they are natively mapped to a latent space similar to textual input (query).
This enables leveraging the [ColBERT](https://arxiv.org/abs/2004.12832) strategy to compute interactions between text tokens and image patches, which enables a step-change improvement in performance compared to BiPali.
## Model Training
### Dataset
Our training dataset of 127,460 query-page pairs is comprised of train sets of openly available academic datasets (63%) and a synthetic dataset made up of pages from web-crawled PDF documents and augmented with VLM-generated (Claude-3 Sonnet) pseudo-questions (37%).
Our training set is fully English by design, enabling us to study zero-shot generalization to non-English languages. We explicitly verify no multi-page PDF document is used both [*ViDoRe*](https://huggingface.co/collections/vidore/vidore-benchmark-667173f98e70a1c0fa4db00d) and in the train set to prevent evaluation contamination.
A validation set is created with 2% of the samples to tune hyperparameters.
*Note: Multilingual data is present in the pretraining corpus of the language model (Gemma-2B) and potentially occurs during PaliGemma-3B's multimodal training.*
### Parameters
All models are trained for 1 epoch on the train set. Unless specified otherwise, we train models in `bfloat16` format, use low-rank adapters ([LoRA](https://arxiv.org/abs/2106.09685))
with `alpha=32` and `r=32` on the transformer layers from the language model,
as well as the final randomly initialized projection layer, and use a `paged_adamw_8bit` optimizer.
We train on an 8 GPU setup with data parallelism, a learning rate of 5e-5 with linear decay with 2.5% warmup steps, and a batch size of 32.
## Usage
### For best performance, newer models are available (vidore/colpali-v1.2)
```bash
# This model checkpoint is compatible with version 0.1.1, but not more recent versions of the inference lib
pip install colpali_engine==0.1.1
```
```python
import torch
import typer
from torch.utils.data import DataLoader
from tqdm import tqdm
from transformers import AutoProcessor
from PIL import Image
from colpali_engine.models.paligemma_colbert_architecture import ColPali
from colpali_engine.trainer.retrieval_evaluator import CustomEvaluator
from colpali_engine.utils.colpali_processing_utils import process_images, process_queries
from colpali_engine.utils.image_from_page_utils import load_from_dataset
def main() -> None:
"""Example script to run inference with ColPali"""
# Load model
model_name = "vidore/colpali"
model = ColPali.from_pretrained("vidore/colpaligemma-3b-mix-448-base", torch_dtype=torch.bfloat16, device_map="cuda").eval()
model.load_adapter(model_name)
processor = AutoProcessor.from_pretrained(model_name)
# select images -> load_from_pdf(), load_from_image_urls([""]), load_from_dataset()
images = load_from_dataset("vidore/docvqa_test_subsampled")
queries = ["From which university does James V. Fiorca come ?", "Who is the japanese prime minister?"]
# run inference - docs
dataloader = DataLoader(
images,
batch_size=4,
shuffle=False,
collate_fn=lambda x: process_images(processor, x),
)
ds = []
for batch_doc in tqdm(dataloader):
with torch.no_grad():
batch_doc = {k: v.to(model.device) for k, v in batch_doc.items()}
embeddings_doc = model(**batch_doc)
ds.extend(list(torch.unbind(embeddings_doc.to("cpu"))))
# run inference - queries
dataloader = DataLoader(
queries,
batch_size=4,
shuffle=False,
collate_fn=lambda x: process_queries(processor, x, Image.new("RGB", (448, 448), (255, 255, 255))),
)
qs = []
for batch_query in dataloader:
with torch.no_grad():
batch_query = {k: v.to(model.device) for k, v in batch_query.items()}
embeddings_query = model(**batch_query)
qs.extend(list(torch.unbind(embeddings_query.to("cpu"))))
# run evaluation
retriever_evaluator = CustomEvaluator(is_multi_vector=True)
scores = retriever_evaluator.evaluate(qs, ds)
print(scores.argmax(axis=1))
if __name__ == "__main__":
typer.run(main)
```
## Limitations
- **Focus**: The model primarily focuses on PDF-type documents and high-ressources languages, potentially limiting its generalization to other document types or less represented languages.
- **Support**: The model relies on multi-vector retreiving derived from the ColBERT late interaction mechanism, which may require engineering efforts to adapt to widely used vector retrieval frameworks that lack native multi-vector support.
## License
ColPali's vision language backbone model (PaliGemma) is under `gemma` license as specified in its [model card](https://huggingface.co/google/paligemma-3b-mix-448). The adapters attached to the model are under MIT license.
## Contact
- Manuel Faysse: manuel.faysse@illuin.tech
- Hugues Sibille: hugues.sibille@illuin.tech
- Tony Wu: tony.wu@illuin.tech
## Citation
If you use any datasets or models from this organization in your research, please cite the original dataset as follows:
```bibtex
@misc{faysse2024colpaliefficientdocumentretrieval,
title={ColPali: Efficient Document Retrieval with Vision Language Models},
author={Manuel Faysse and Hugues Sibille and Tony Wu and Bilel Omrani and Gautier Viaud and Céline Hudelot and Pierre Colombo},
year={2024},
eprint={2407.01449},
archivePrefix={arXiv},
primaryClass={cs.IR},
url={https://arxiv.org/abs/2407.01449},
}
```