---
title: llava-critic-113k
canonical_url: "https://www.modelscope.cn/datasets/lmms-lab/llava-critic-113k"
md_url: "https://www.modelscope.cn/datasets/lmms-lab/llava-critic-113k.md"
repository: lmms-lab/llava-critic-113k
last_updated: 2024-11-21
license: "Apache License 2.0"
storage_size: "5.5 GB"
domain:
- pretty_name
tasks:
- LLaVA-Critic-113k
downloads: 3283
stars: 0
---
# llava-critic-113k
> llava-critic-113k - lmms-lab 在 ModelScope 开源的数据集。Dataset Card for LLaVA-Critic-113k
lmms-lab/llava-critic-113k 是 ModelScope 魔搭社区上的LLaVA-Critic-113k数据集,涉及 pretty_name 领域,存储大小 5.5 GB,采用 Apache License 2.0 许可。
- **Repository**: lmms-lab/llava-critic-113k
- **License**: Apache License 2.0
- **Tasks**: LLaVA-Critic-113k
- **Domain**: pretty_name
- **Storage size**: 5.5 GB
- **Downloads**: 3283
- **Stars**: 0
- **Last updated**: 2024-11-21
Source: https://www.modelscope.cn/datasets/lmms-lab/llava-critic-113k
---
# Dataset Card for LLaVA-Critic-113k
- 🪐 Project Page: https://llava-vl.github.io/blog/2024-10-03-llava-critic/
- 📰 Paper: https://arxiv.org/abs/2410.02712
- 🤗 Huggingface Collection: https://huggingface.co/collections/lmms-lab/llava-critic-66fe3ef8c6e586d8435b4af8
- 👋 Point of Contact: [Tianyi Xiong](https://tyxiong23.github.io/)
## Dataset Summary
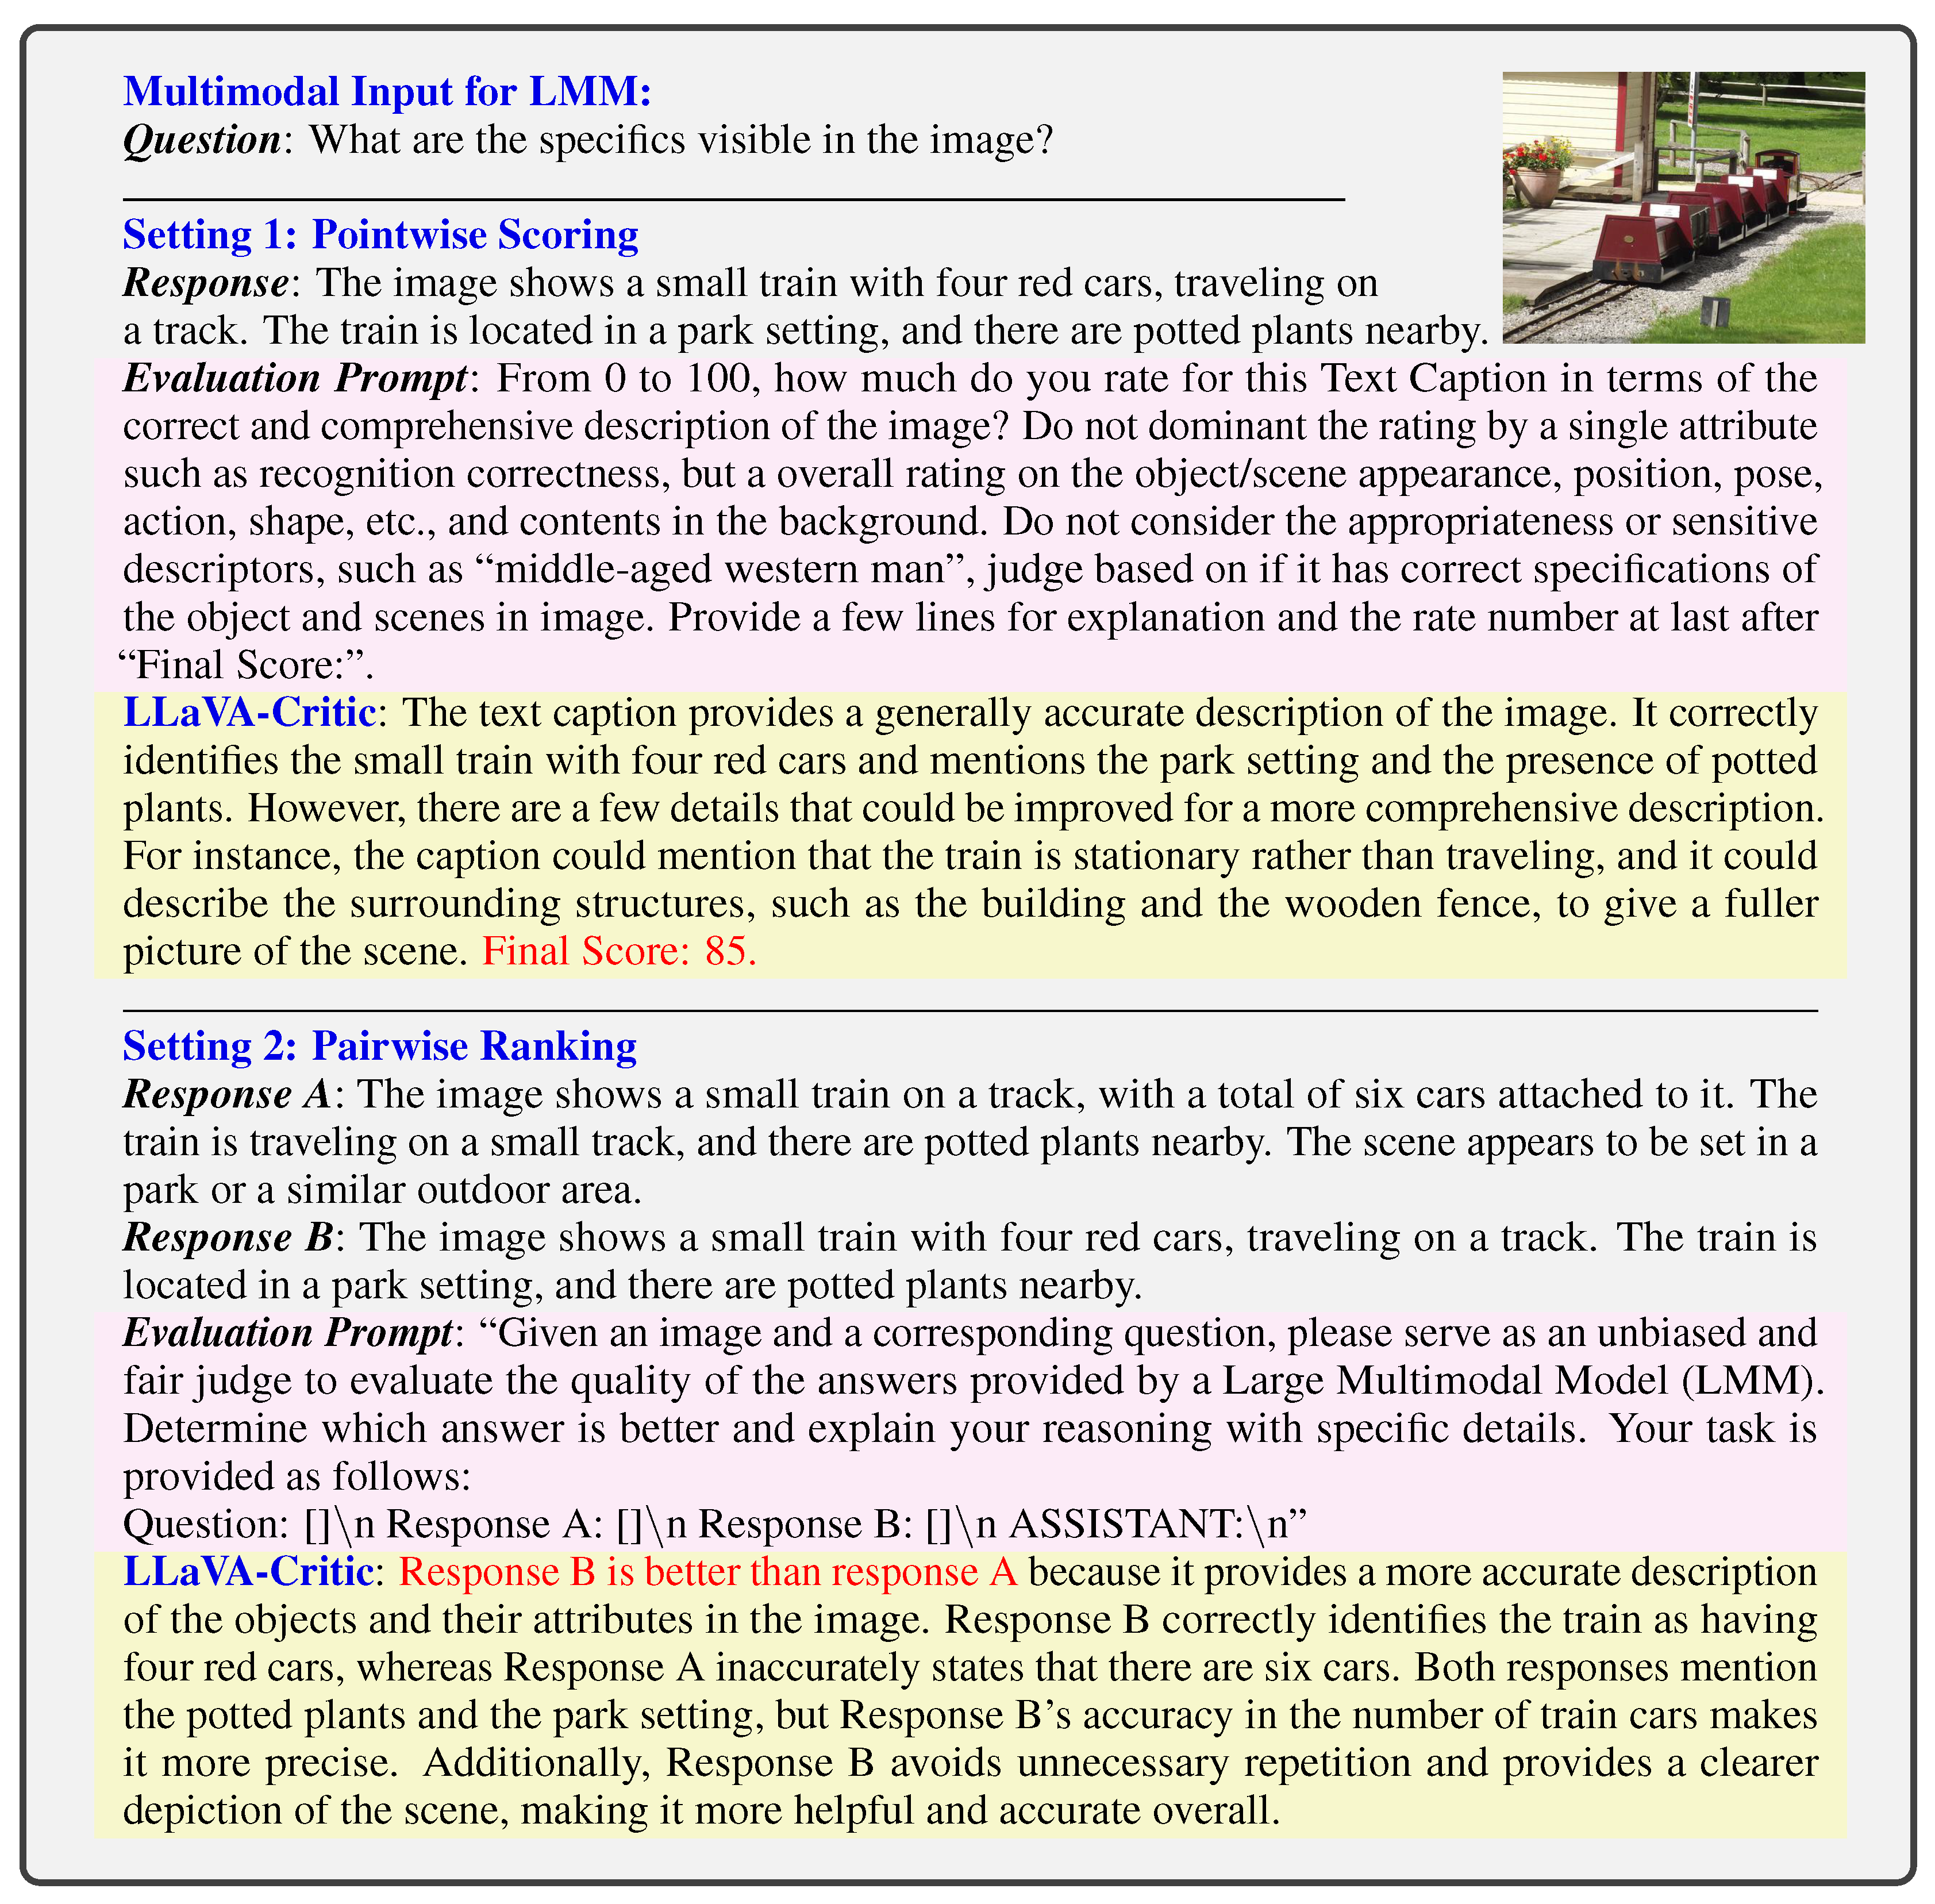
LLaVA-Critic-113k is a high quality **critic instruction-following dataset** tailored to follow instructions in complex evaluation setting, providing both **quantitative judgments** and the **corresponding reasoning process**. It consists of 46k images with 113k evaluation instruction samples, primarily including two evaluation settings:
- Pointwise Scoring: Assign a score to an individual candidate response.
We collect instrucion-response pairs across 8 multimodal datasets and 13 response models, gather evaluation prompts from 7 open-ended benchmarks, and utilize GPT-4o to produce judgment scores and reasons.
*Data Format* (`Input` + Output):
`Image`, `Question`, `Response`, `Reference(optional)`, `Evaluation Criteria`, Score, Reason
- Pairwise Ranking: Compare two candidate responses to determine their relative quality.
We gather pairwise responses with known preferences, design a set of 30 pairwise evaluation prompt templates, and ask GPT-4o to generate justification for the preference.
*Data Format* (`Input` + Output):
`Image`, `Question`, `Response 1&2`, `Evaluation Criteria`, Preference, Reason
### Data Statistics
 ### Example Data
 ## Citation
```
@article{xiong2024llavacritic,
title={LLaVA-Critic: Learning to Evaluate Multimodal Models},
author={Xiong, Tianyi and Wang, Xiyao and Guo, Dong and Ye, Qinghao and Fan, Haoqi and Gu, Quanquan and Huang, Heng and Li, Chunyuan},
year={2024},
eprint={2410.02712},
archivePrefix={arXiv},
primaryClass={cs.CV},
url={https://arxiv.org/abs/2410.02712},
}
```