---
title: dart-math-hard
canonical_url: "https://www.modelscope.cn/datasets/hkust-nlp/dart-math-hard"
md_url: "https://www.modelscope.cn/datasets/hkust-nlp/dart-math-hard.md"
repository: hkust-nlp/dart-math-hard
last_updated: 2025-02-17
license: "Apache License 2.0"
storage_size: "313 MB"
downloads: 1232
stars: 0
---

# dart-math-hard

> dart-math-hard - hkust-nlp 在 ModelScope 开源的数据集。🎯 DART-Math: Difficulty-Aware Rejection Tuning for Mathematical Problem-Solving

hkust-nlp/dart-math-hard 是 ModelScope 魔搭社区上的数据集，存储大小 313 MB，采用 Apache License 2.0 许可。

- **Repository**: hkust-nlp/dart-math-hard
- **License**: Apache License 2.0
- **Storage size**: 313 MB
- **Downloads**: 1232
- **Stars**: 0
- **Last updated**: 2025-02-17

Source: https://www.modelscope.cn/datasets/hkust-nlp/dart-math-hard

---

# 🎯 DART-Math: Difficulty-Aware Rejection Tuning for Mathematical Problem-Solving

📝 [Paper@arXiv](https://arxiv.org/abs/2407.13690) | 🤗 [Datasets&Models@HF](https://huggingface.co/collections/hkust-nlp/dart-math-665704599b35de59f8fdf6c1) | 🐱 [Code@GitHub](https://github.com/hkust-nlp/dart-math)

🐦 [Thread@X(Twitter)](https://x.com/tongyx361/status/1811413243350454455) | 🐶 [中文博客@知乎](https://zhuanlan.zhihu.com/p/708371895) | 📊 [Leaderboard@PapersWithCode](https://paperswithcode.com/paper/dart-math-difficulty-aware-rejection-tuning#results) | 📑 [BibTeX](https://github.com/hkust-nlp/dart-math?tab=readme-ov-file#citation)

> [!IMPORTANT]
> 🔥 Excited to find **[our `DART-Math-DSMath-7B` (Prop2Diff)](https://huggingface.co/hkust-nlp/dart-math-dsmath-7b-prop2diff) trained on [`DART-Math-Hard`](https://huggingface.co/datasets/hkust-nlp/dart-math-hard) [comparable](https://github.com/project-numina/aimo-progress-prize/blob/main/report/numina_dataset.pdf) to the AIMO winner [NuminaMath-7B](https://huggingface.co/AI-MO/NuminaMath-7B-CoT)** on CoT,
> but based solely on [MATH](https://huggingface.co/datasets/hkust-nlp/dart-math-pool-math-query-info) & [GSM8K](https://huggingface.co/datasets/hkust-nlp/dart-math-pool-gsm8k-query-info) prompt set, leaving much room to improve!
> Besides, our [`DART` method](https://github.com/hkust-nlp/dart-math?tab=readme-ov-file#dars--difficulty-aware-rejection-sampling) is also fully compatible with [tool-integrated reasoning](https://github.com/hkust-nlp/dart-math?tab=readme-ov-file#tool-integrated-reasoning-reasoning-in-natural-language-interleaved-with-python-code).
> Find more details and join the discussion under this [X thread](https://x.com/tongyx361/status/1815112376649134172)!

## Datasets: `DART-Math`

`DART-Math` datasets are the **state-of-the-art** and **data-efficient** **open-source** instruction tuning datasets for mathematical reasoning.

<style>
    .container {
        display: flex;
        justify-content: space-around;
    }
    .container img {
        max-width: 45%;
        height: auto;
    }
    .caption {
        text-align: center;
        font-size: small;
        margin-top: 10px;
    }
</style>
<div class="container">
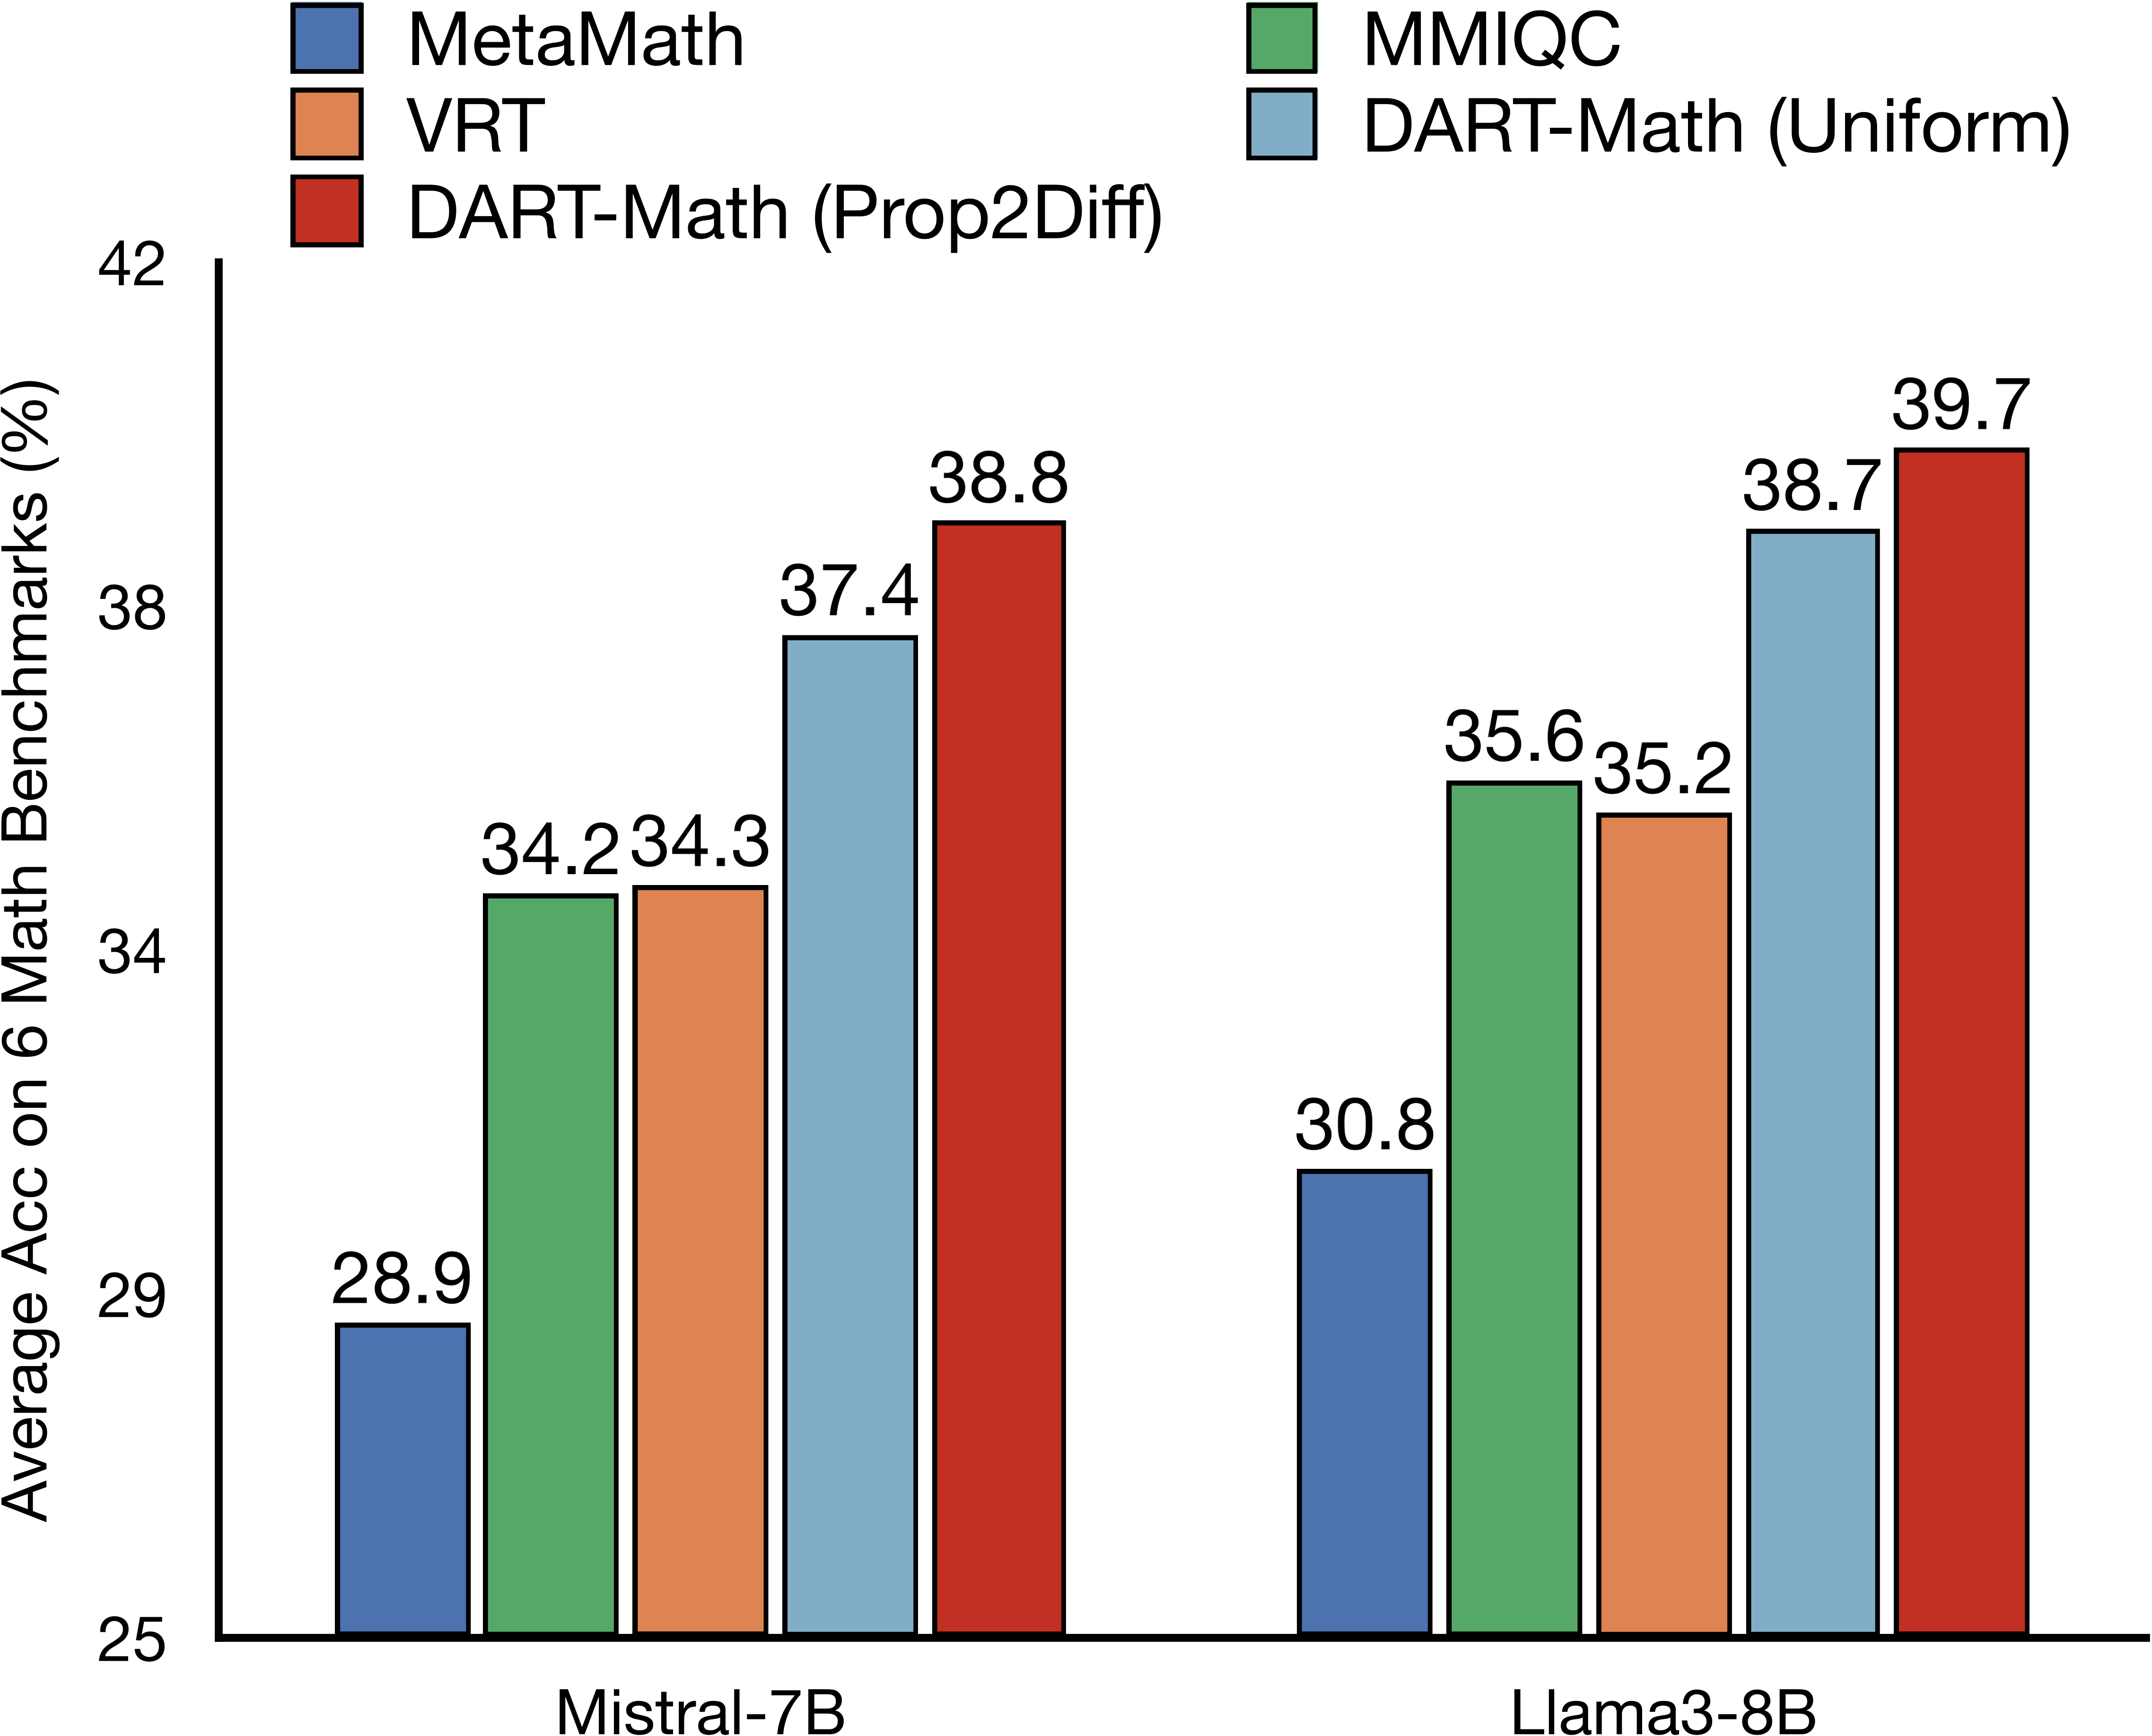
    <img src="https://tongyx361.github.io/assets/dart-math/main-results.png" alt="Main results averaged on 2 in-domain and 4 challenging out-of-domain mathematical reasoning benchmarks.">
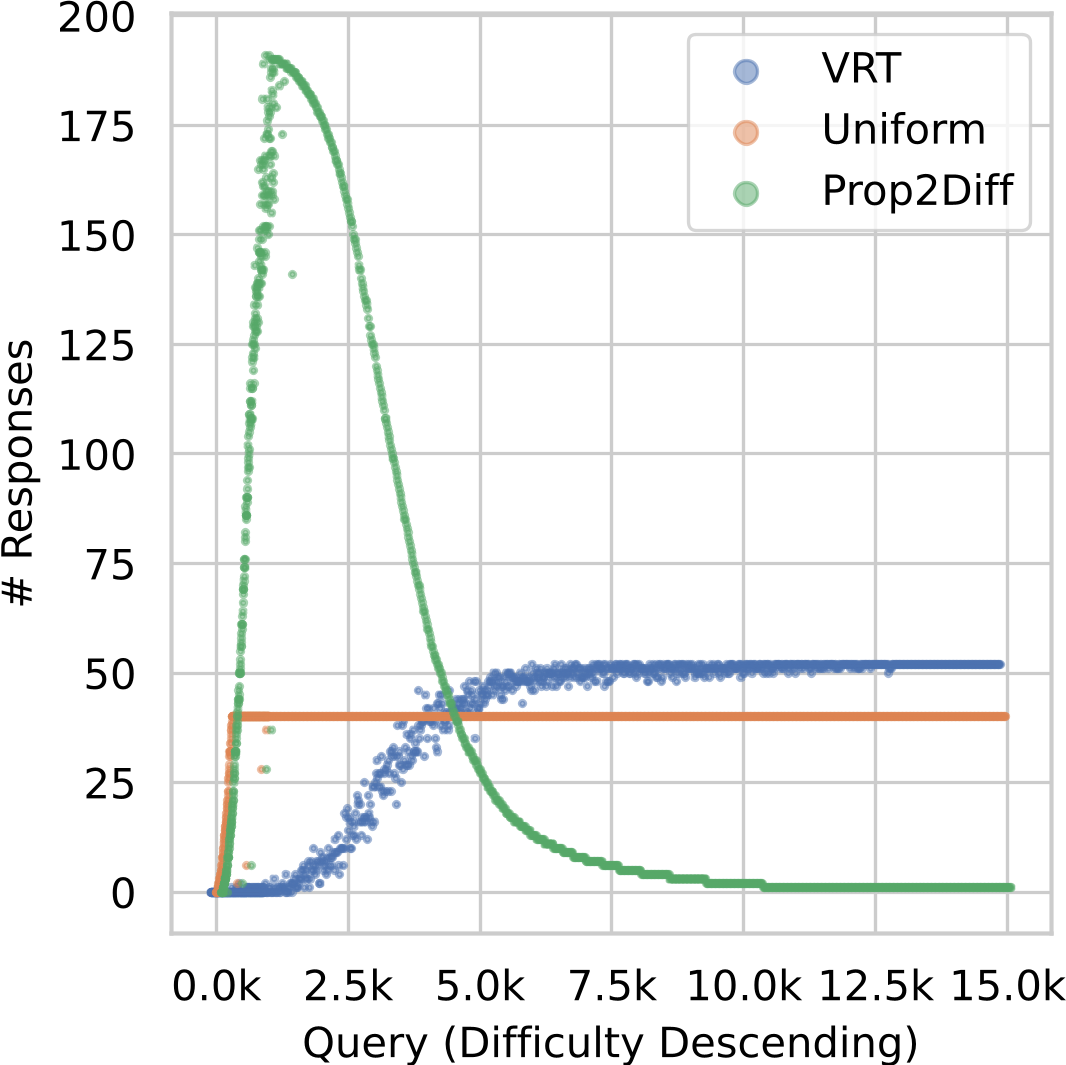
    <img src="https://tongyx361.github.io/assets/dart-math/main-nresp-vs-query.png" alt="Number of responses v.s. query descending in difficulty in DART-Math datasets and similar-sized VRT baseline.">
</div>
<div class="caption">
  Figure 1: <strong>Left:</strong> Average accuracy on 6 mathematical benchmarks. We compare with models fine-tuned on the best, public instruction tuning datasets for mathematical problem-solving:
  MetaMath <a href="https://openreview.net/forum?id=N8N0hgNDRt">(Yu et al., 2024)</a> with 395K
  examples,
  MMIQC <a href="https://arxiv.org/abs/2401.09003">(Liu et al., 2024a)</a> with 2.3 million examples,
  as well as vanilla rejection tuning (VRT) with 590K examples.
  Both <em>DART-Math (Uniform)</em> and <em>DART-Math (Prop2Diff)</em> use 590K training examples.
  <strong>Right:</strong> Number of responses for each query descending by difficulty across 3 synthesis strategies.
  Queries are from the MATH training split <a href="https://datasets-benchmarks-proceedings.neurips.cc/paper/2021/hash/be83ab3ecd0db773eb2dc1b0a17836a1-Abstract-round2.html">(Hendrycks et al., 2021)</a>.
  VRT is the baseline biased towards easy queries, while <em>Uniform</em> and <em>Prop2Diff</em> are proposed in this work to balance and bias towards difficult queries respectively.
  Points are slightly shifted and downsampled for clarity.
</div>

`DART-Math-Hard` contains \~585k mathematical QA pair samples constructed by applying `DARS-Prop2Diff` to the query set from MATH and GSK8K training sets, achieves **SOTA** on many challenging mathematical reasoning benchmarks. It introduces a **deliberate bias towards hard queries**, opposite to vanilla rejection sampling.

Performance produced by  `DART-Math-Hard` is usually but not necessarily **slightly better (\~1% absolutely)** than `DART-Math-Uniform`, which contains \~591k samples constructed by applying `DARS-Uniform`.

### Comparison between Mathematical Instruction Tuning Datasets

Most of previous datasets are **constructed with ChatGPT**, and many of them are **not open-source**, especially for ones of the best performance.

| Math SFT Dataset                                                                   | # of Samples | [MATH](https://huggingface.co/datasets/hendrycks/competition_math) | [GSM8K](https://huggingface.co/datasets/gsm8k) | [College](https://github.com/hkust-nlp/dart-math/tree/main/data/eval-dsets/mwpbench/college-math-test.jsonl) | Synthesis Agent(s)      |                                 Open-Source                                 |
| :--------------------------------------------------------------------------------- | -----------: | -----------------------------------------------------------------: | ---------------------------------------------: | -----------------------------------------------------------------------------------------------------------: | :---------------------- | :-------------------------------------------------------------------------: |
| [WizardMath](https://arxiv.org/abs/2308.09583)                                     |          96k |                                                               32.3 |                                           80.4 |                                                                                                         23.1 | GPT-4                   |                                      ✗                                      |
| [MetaMathQA](https://arxiv.org/abs/2309.12284)                                     |         395k |                                                               29.8 |                                           76.5 |                                                                                                         19.3 | GPT-3.5                 |          [✓](https://huggingface.co/datasets/meta-math/MetaMathQA)          |
| [MMIQC](https://arxiv.org/abs/2401.09003)                                          |    **2294k** |                                                               37.4 |                                           75.4 |                                                                                                       _28.5_ | **GPT-4+GPT-3.5+Human** |           [**✓**](https://huggingface.co/datasets/Vivacem/MMIQC)            |
| [Orca-Math](https://arxiv.org/abs/2402.14830)                                      |         200k |                                                                 -- |                                             -- |                                                                                                           -- | GPT-4                   | [✓](https://huggingface.co/datasets/microsoft/orca-math-word-problems-200k) |
| [Xwin-Math-V1.1](https://arxiv.org/abs/2403.04706)                                 |    **1440k** |                                                             _45.5_ |                                       **84.9** |                                                                                                         27.6 | **GPT-4**               |                                    **✗**                                    |
| [KPMath-Plus](https://arxiv.org/abs/2403.02333)                                    |    **1576k** |                                                           **46.8** |                                           82.1 |                                                                                                           -– | **GPT-4**               |                                    **✗**                                    |
| [MathScaleQA](https://arxiv.org/abs/2403.02884)                                    |        2021k |                                                               35.2 |                                           74.8 |                                                                                                         21.8 | GPT-3.5+Human           |                                      ✗                                      |
| [`DART-Math-Uniform`](https://huggingface.co/datasets/hkust-nlp/dart-math-uniform) |     **591k** |                                                               43.5 |                                         _82.6_ |                                                                                                         26.9 | **DeepSeekMath-7B-RL**  |    [**✓**](https://huggingface.co/datasets/hkust-nlp/dart-math-uniform)     |
| [`DART-Math-Hard`](https://huggingface.co/datasets/hkust-nlp/dart-math-hard)       |     **585k** |                                                             _45.5_ |                                           81.1 |                                                                                                     **29.4** | **DeepSeekMath-7B-RL**  |      [**✓**](https://huggingface.co/datasets/hkust-nlp/dart-math-hard)      |

<sup>MATH and GSM8K are **in-domain**, while College(Math) is **out-of-domain**. Performance here are of models fine-tuned from [Mistral-7B](https://huggingface.co/mistralai/Mistral-7B-v0.1), except for Xwin-Math-V1.1 based on [Llama2-7B](https://huggingface.co/meta-llama/Llama-2-7b-hf). **Bold**/_Italic_ means the best/second best score here.</sup>

## Dataset Construction: `DARS` - Difficulty-Aware Rejection Sampling

Previous works usually synthesize data from proprietary models to augment existing datasets, followed by instruction tuning to achieve top-tier results.
However, our analysis of these datasets reveals **severe biases towards easy queries, with frequent failures to generate any correct response for the most challenging queries**.

Motivated by the observation above, we propose to *Difficulty-Aware Rejection Sampling* (`DARS`), to collect more responses for more difficult queries.
Specifically, we introduce two strategies to increase the number of correct responses for difficult queries:

1) **Uniform**, which involves sampling responses for each query until **each query accumulates $k_u$ correct
responses**, where $k_u$ is a preset hyperparameter determined by the desired size of the synthetic dataset;
2) **Prop2Diff**, where we continue sampling responses until the number of correct responses for each
query is **proportional to its difficulty score**. The most challenging queries will receive $k_p$ responses
and kp is a hyperparameter. This method introduces a deliberate bias in the opposite direction to
vanilla rejection sampling, towards more difficult queries, inspired by previous works
that demonstrate **difficult samples can be more effective to enhance model capabilities** ([Sorscher et al.,
2022](https://proceedings.neurips.cc/paper_files/paper/2022/hash/7b75da9b61eda40fa35453ee5d077df6-Abstract-Conference.html); [Liu et al., 2024b](https://openreview.net/forum?id=BTKAeLqLMw)).

See [Figure 1 (Right)](https://tongyx361.github.io/assets/dart-math/main-nresp-vs-query.png) for examples of `DART-Math-Uniform` by `DARS-Uniform` and `DART-Math-Hard` by `DARS-Prop2Diff`.

## Citation

If you find our data, model or code useful for your work, please kindly cite [our paper](https://arxiv.org/abs/2407.13690):

```latex
@article{tong2024dartmath,
  title={DART-Math: Difficulty-Aware Rejection Tuning for Mathematical Problem-Solving},
  author={Yuxuan Tong and Xiwen Zhang and Rui Wang and Ruidong Wu and Junxian He},
  year={2024},
  eprint={2407.13690},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2407.13690},
}
```